ToolMage
Sign in

AI TOOL COMPARISON

Fluidstack vs Nebius

What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.

Jump to key differences

Product overview

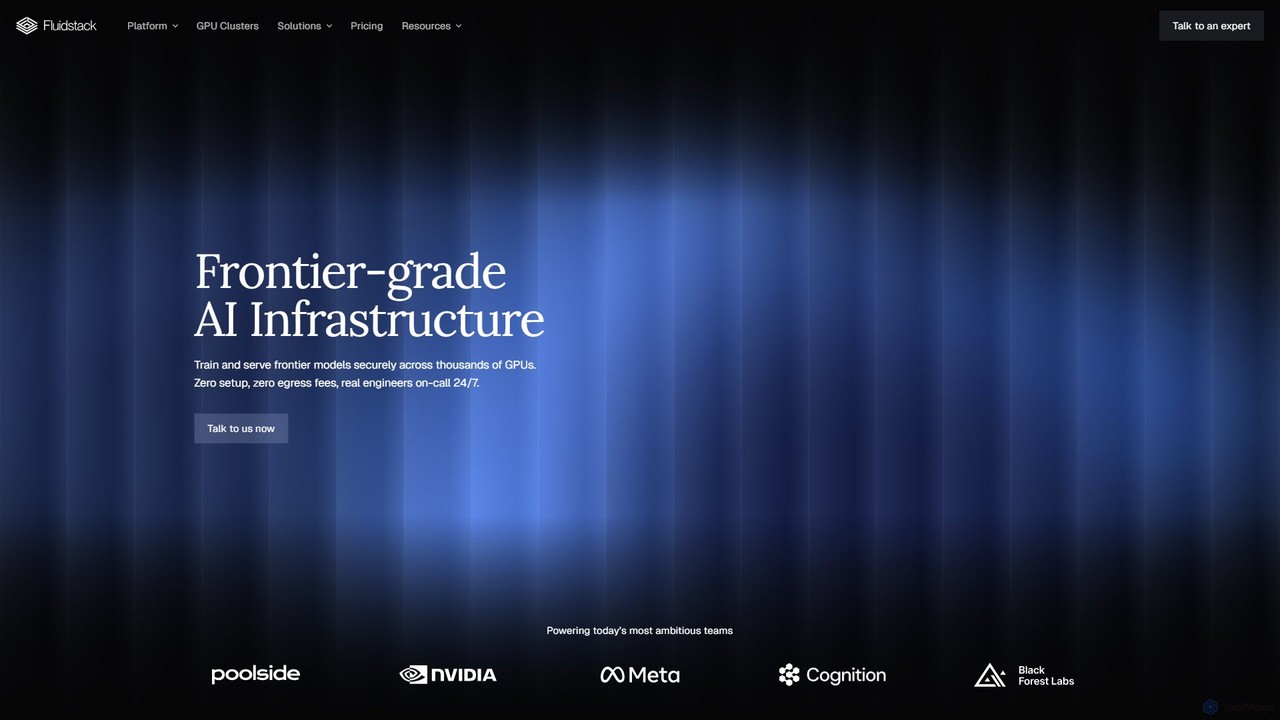
Fluidstack Product overview

Fluidstack is a leading AI cloud platform providing high-performance, dedicated GPU clusters for training and serving frontier AI models. It offers rapid deployment of thousands of GPUs, fully managed services with 24/7 expert support, and transparent pricing with zero egress fees, empowering AI teams to scale without infrastructure friction.

Preview

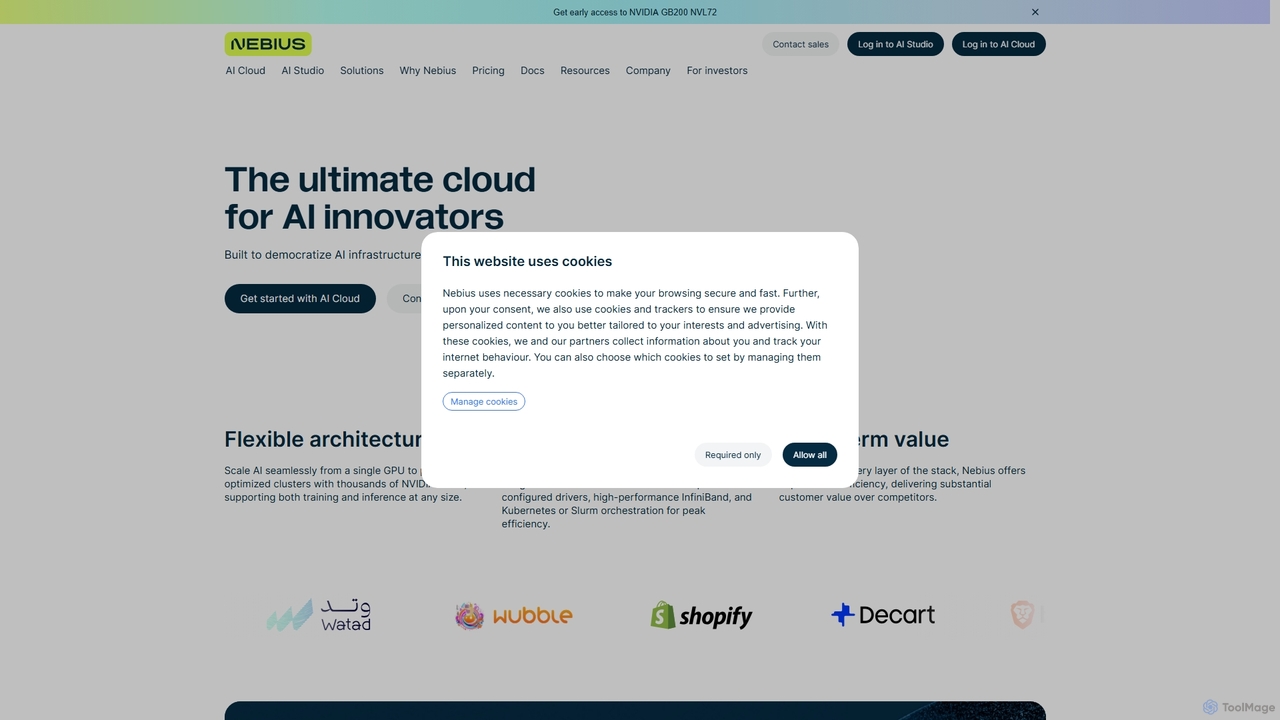
Nebius Product overview

Nebius is a high-performance cloud platform specifically engineered for demanding AI and Machine Learning workloads. It provides scalable access to the latest NVIDIA GPUs, from single instances to massive clusters, complemented by a suite of managed services and an integrated AI Studio to streamline the entire ML lifecycle from training to inference.

Preview

Quick facts

Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.

Fluidstack VS Nebius — Quick facts
Quick factsFluidstackNebius
Pricing modelPaidPaid
Product typeWebWeb
Primary focusEnterprise SolutionsGpu Cloud
Audience and rolesNo data availableAI Researcher · CTO · Data Scientist · DevOps Engineer · Machine Learning Engineer · Product Manager · Software Developer
CategoriesEnterprise Solutions · Machine Learning · Cloud ComputingGpu Cloud · Machine Learning · Cloud Computing
AddedAug 9, 2025Sep 10, 2025
UpdatedNov 19, 2026Nov 19, 2026

Features, usage and use cases

Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.

Fluidstack

Fluidstack is a specialized AI cloud platform designed to provide high-performance GPU infrastructure for the world's most ambitious AI teams, from frontier startups to established enterprises. The platform's core mission is to eliminate the complexities and delays associated with setting up and managing large-scale GPU clusters, allowing researchers and developers to focus solely on model development and innovation. Fluidstack delivers fully managed, dedicated GPU clusters that are benchmarked to achieve over 95% of theoretical performance, ensuring maximum throughput for demanding AI workloads.

Trusted by leading AI labs and companies like poolside, Fluidstack has proven its capability to deploy thousands of GPUs, such as NVIDIA H100s and A100s, within days—a stark contrast to the months-long lead times of traditional hyperscalers. The platform is built on a purpose-built stack, including the Atlas OS for fast provisioning and the Lighthouse monitoring system for proactive issue detection and auto-remediation, guaranteeing high uptime and reliability.

How to use Fluidstack

Getting started with Fluidstack is a streamlined, consultative process designed for serious AI development:

  1. Consultation: Begin by contacting Fluidstack's expert team through their website to discuss your specific computational needs, including the required number and type of GPUs, project timeline, and scale.
  2. Cluster Design: Fluidstack's engineers will work with you to design a custom, dedicated GPU cluster optimized for your workloads, whether it's for large-scale model training or high-throughput inference.
  3. Rapid Deployment: Once the contract is signed, Fluidstack provisions your dedicated cluster. This process is incredibly fast, with deployments of thousands of GPUs possible within 48 hours.
  4. Access and Integration: Access your fully managed cluster through standard orchestration tools like SLURM or Kubernetes. Fluidstack handles all the setup, maintenance, and upgrades, allowing for seamless integration into your existing workflow.
  5. Ongoing Management: Leverage Fluidstack's 24/7 hands-on support and the Lighthouse monitoring platform. The system automatically detects and resolves issues, while engineers are available with a 15-minute response SLA for any complex problems.

Core Features of Fluidstack

  • Dedicated GPU Clusters: Access to the latest GPU architectures, including NVIDIA H100, H200, B200, and GB200, with the ability to scale to over 12,000 GPUs on a single fabric.
  • Atlas OS: A proprietary bare-metal operating system for AI infrastructure that enables fast provisioning, smooth orchestration, and total ownership.
  • Lighthouse Monitoring: A proactive monitoring and auto-remediation platform that monitors, heals, and optimizes workloads, catching problems before they impact performance.
  • Fully Managed Service: End-to-end management of your cluster, including setup, orchestration (SLURM or Kubernetes), maintenance, and upgrades.
  • 24/7 Expert Engineering Support: Direct access to real engineers via Slack with a guaranteed 15-minute response time SLA, providing expert answers and hands-on support.
  • High Security and Compliance: Infrastructure is single-tenant by default, ensuring full isolation. The platform is compliant with HIPAA, GDPR, ISO27001, and SOC 2 Type I standards.
  • Transparent Pricing: No hidden fees, including zero egress or ingress charges, and on-node NVMe storage is included.

Use Cases for Fluidstack

Fluidstack is ideal for organizations with demanding, large-scale AI requirements:

  • Research Labs: Enables top researchers to skip infrastructure delays and focus entirely on pushing the boundaries of AI model development.
  • Enterprise AI Teams: Provides reliable, high-performance, and compliant clusters for running business-critical AI applications at scale.
  • Sovereign AI Initiatives: Offers secure, region-specific deployments with full physical and operational security to build national AI capabilities.
  • Financial Services: Powers fast and secure inference, quantitative modeling, and risk analysis workloads.
  • AI Startups: As demonstrated by the poolside case study, Fluidstack allows fast-moving startups to deploy large clusters quickly, accelerate time-to-market, and scale efficiently without large upfront capital or long-term commitments.

Advantages of Fluidstack

Fluidstack offers significant advantages over traditional cloud providers:

  • Unmatched Speed: Deploy multi-thousand GPU clusters in days, not months.
  • Peak Performance: Clusters are fully burned-in and benchmarked to deliver >95% of theoretical performance from day one.
  • Operational Simplicity: Frees your team from the complexities of infrastructure management, from hardware setup to Kubernetes configuration.
  • Cost-Efficiency: Transparent, all-inclusive pricing without surprise data transfer fees, leading to a more predictable and often lower total cost of ownership.
  • Superior Support: Direct, partnership-style support from experienced engineers, not a tiered ticketing system.

Pricing and Plans

Fluidstack offers flexible pricing models tailored to different needs, all with transparent, all-inclusive terms.

  • Reserved Clusters: Designed for large-scale training and inference with terms of 30 days or more. Offers discounted rates and guaranteed resources for 256 to 10,000+ GPUs. Pricing is available upon request.
  • On-Demand: For flexible scaling needs, allowing you to launch GPU instances in under 5 minutes and scale from 8 to 4,000+ GPUs. Billed per hour.
  • Private Cloud: Custom-built, dedicated clusters for complex needs, specific regions, or custom stacks.

Example on-demand hourly rates:

  • NVIDIA H200 SXM: $2.30 / GPU / Hour
  • NVIDIA H100 SXM: $2.10 / GPU / Hour
  • NVIDIA A100 80GB SXM: $1.30 / GPU / Hour

All plans include 24/7 engineering support, a 15-minute response SLA, managed SLURM or K8s, proactive monitoring, and no egress/ingress fees.

Nebius

Nebius is a specialized, high-performance cloud provider designed from the ground up to meet the intensive demands of artificial intelligence and machine learning. As an NVIDIA Reference Platform Cloud Partner, Nebius offers a robust and scalable infrastructure for AI explorers, researchers, and enterprises. The platform combines cutting-edge hardware, including the latest NVIDIA GPUs, with a comprehensive suite of managed services and a user-friendly AI Studio, creating an end-to-end environment for developing, training, and deploying AI models of any size.

The core of Nebius is its AI-optimized infrastructure, built within its own sustainable and highly efficient data centers. This allows for unparalleled performance and cost-effectiveness. Whether you're fine-tuning a large language model, running complex scientific simulations, or deploying generative AI applications, Nebius provides the power and flexibility needed to accelerate innovation.

How to use Nebius

Getting started with Nebius is designed to be straightforward for developers and ML engineers. Users can begin by signing up on the platform. From there, you can provision resources through multiple interfaces: the intuitive web console, a powerful command-line interface (CLI), a comprehensive API, or by using Infrastructure as Code tools like Terraform for automated deployments. You can select from a range of NVIDIA GPU instances (such as H100, H200, B200) and configure them as standalone machines or as part of large, multi-node clusters orchestrated with Managed Kubernetes or Slurm. For a more streamlined workflow, the Nebius AI Studio offers ready-to-use services for model fine-tuning, inference, and batch processing, accessible in just a few clicks.

Core Features of Nebius

  • Latest NVIDIA GPUs: Access to a wide range of top-tier NVIDIA accelerators, including the H100, H200, B200, and pre-orders for the GB200 NVL72, ensuring peak performance for AI workloads.
  • Scalable AI Clusters: Flexibly scale from a single GPU to superclusters with thousands of GPUs, interconnected with high-speed InfiniBand networking (up to 3.2Tbit/s per host).
  • Managed Services: Fully managed solutions for Kubernetes, Slurm, PostgreSQL, MLflow, and Apache Spark, reducing operational overhead and allowing teams to focus on ML development.
  • Nebius AI Studio: An integrated platform offering services for inference, fine-tuning, AI image generation, and batch processing to accelerate the ML lifecycle.
  • Cloud-Native Experience: Full support for modern DevOps practices with Terraform, API, and CLI for infrastructure management.
  • Enterprise-Grade Security: Robust security measures, including enterprise-grade encryption, smart access management, and a secure-by-design infrastructure to protect sensitive AI workloads.
  • Expert Support: 24/7 expert support and dedicated assistance from solution architects for complex multi-node deployments, provided free of charge.

Use Cases for Nebius

Nebius is ideal for a wide array of computationally intensive tasks. Its primary use cases include training and fine-tuning large language models (LLMs), developing and deploying generative AI applications like image and text generators, and running high-performance computing (HPC) simulations for scientific research in fields like genomics and quantum chemistry. Furthermore, enterprises leverage Nebius to build scalable MLOps pipelines, manage complex AI workflows, and run large-scale batch inference jobs efficiently.

Advantages of Nebius

The main advantage of Nebius lies in its singular focus on AI. By optimizing every layer of the stack—from its custom-designed, power-efficient data centers to its pre-configured software environments—Nebius delivers superior performance and significant cost savings compared to general-purpose cloud providers. Its status as an NVIDIA Reference Platform Cloud Partner guarantees access to the latest technology and optimized architectures. The combination of raw computing power, managed services, and a dedicated AI Studio provides a comprehensive, developer-friendly platform that simplifies and accelerates the entire AI development journey.

Pricing and Plans

Nebius offers a pay-as-you-go pricing model for its GPU resources, providing transparency and flexibility. Pricing is typically calculated on an hourly basis. For example, indicative prices are:

  • NVIDIA H100 GPU: Starting from $2.00 per hour
  • NVIDIA H200 GPU: Starting from $2.30 per hour
  • NVIDIA B200 GPU: Starting from $3.00 per hour
For large-scale commitments (hundreds of units for at least 3 months), Nebius offers competitive pricing and improved cost savings. Prospective customers are encouraged to contact the sales team for a personalized offer. All listed prices are exclusive of applicable taxes.

Positioning

Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.

Categories

Shared
Machine LearningCloud Computing
Only Fluidstack
Enterprise Solutions
Only Nebius
Gpu Cloud

Tags

Shared
AI infrastructuredeep learningGPU cloudhigh performance computingmachine learningmodel training
Only Fluidstack
B200cloud computingenterprise AIH100inference
Only Nebius
cloud platformkubernetesMLOpsmodel inferenceNVIDIA GPUslurm

Audience and roles

Shared
No listed items
Only Fluidstack
No listed items
Only Nebius
AI ResearcherCTOData ScientistDevOps EngineerMachine Learning EngineerProduct ManagerSoftware Developer

Traffic comparison

Traffic is shown on the same scale so differences in market visibility are not visually understated.

How to interpret the traffic data

Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.

Fluidstack monthly traffic:

Latest traffic · 2026-05

Monthly visits
101.4K
Avg. visit duration
1:06
Pages per visit
2.58
Bounce rate
39.33%
Data updated 2026-06-11

Monthly traffic trend

  • 2025-09: 28.9K
  • 2026-01: 91.6K
  • 2026-02: 69.4K
  • 2026-03: 95.5K
  • 2026-04: 101K
  • 2026-05: 101.4K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇺🇸United States87.31%88.5K
🇬🇧United Kingdom6.99%7.1K
🇮🇳India2.34%2.4K
🇨🇦Canada1.75%1.8K
🇻🇳Vietnam1.61%1.6K

Traffic sources

Source typePercentageEstimated visits
Direct77.86%79K
Referral16.42%16.7K
Email5.72%5.8K

Search keywords

fluid stackfluidstackfluidstack careersfluidstack jobsfluidstack technical program manager, deployments

Nebius monthly traffic:

Latest traffic · 2026-05

Monthly visits
2.3K
Avg. visit duration
0:24
Pages per visit
2.06
Bounce rate
30.76%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 6.4K
  • 2026-01: 78
  • 2026-02: 0
  • 2026-03: 365
  • 2026-04: 1.4K
  • 2026-05: 2.3K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇮🇳India70.68%1.6K
🇺🇸United States19.85%454
🇬🇧United Kingdom9.47%217

Search keywords

nebiusnebius ainebius ai cloudnebius gpunebius logo

Community signals

Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.

Fluidstack

Rating
No data available
Comments
0
Favorites
160
Likes
152

Nebius

Rating
No data available
Comments
0
Favorites
174
Likes
191

Fluidstack vs Nebius · Comparison FAQ

What do Fluidstack and Nebius have in common?
Both tools are listed under Machine Learning、Cloud Computing. These categories indicate overlapping use cases; compare their detailed descriptions for workflows, capabilities and limitations.
Are Fluidstack and Nebius free?
Listed pricing models: Fluidstack — Paid; Nebius — Paid. Missing pricing is not proof of a free plan, and freemium does not mean every feature is free. Check official sites for current plans, limits and trials.
How should I choose between Fluidstack and Nebius?
The primary listed category is Enterprise Solutions for Fluidstack, and Gpu Cloud for Nebius. Compare features, steps and use cases, then verify pricing, data permissions and deployment needs. This page does not include hands-on testing and does not declare a winner from traffic or tags.

Sources and comparison methodology

This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.
  • Feature and plan descriptions reflect information in the listings, not real-time guarantees. Verify pricing, quotas, availability and privacy terms on the official sites.
  • Traffic uses the reporting months shown. Missing statistics do not mean zero visits, and different periods do not establish growth or superiority. Regional and source visit counts are estimates based on shares.
  • Different tags indicate differences in the listings, not proof that the other product lacks a capability. Ratings, favorites and visits are not used to declare a winner.

Related comparisons