hystruct
Scraping
AI TOOL COMPARISON
What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.
Scraping
Scraping
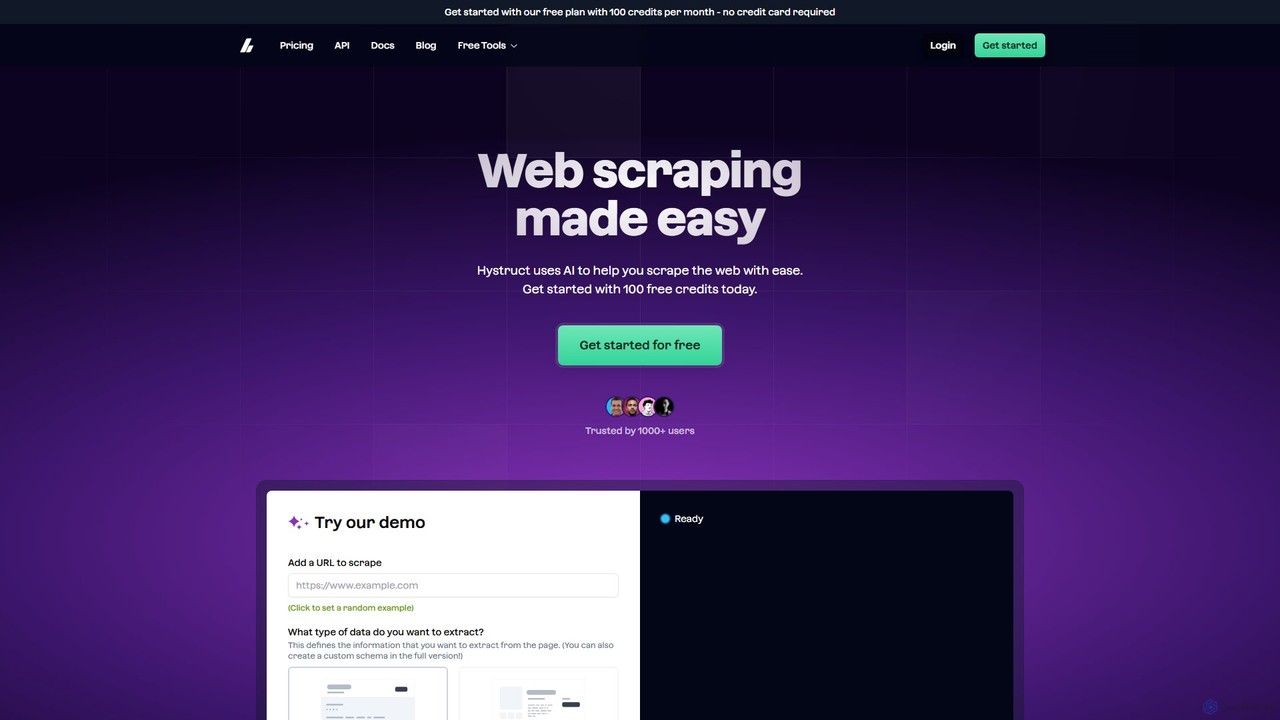
hystruct is an AI-powered web scraping tool that simplifies data extraction. It allows users to easily turn unstructured web content into structured data using pre-built or custom schemas, without needing to code. With integrations like Zapier, it automates workflows for market research, lead generation, and more. It's designed for everyone from beginners to enterprise teams.
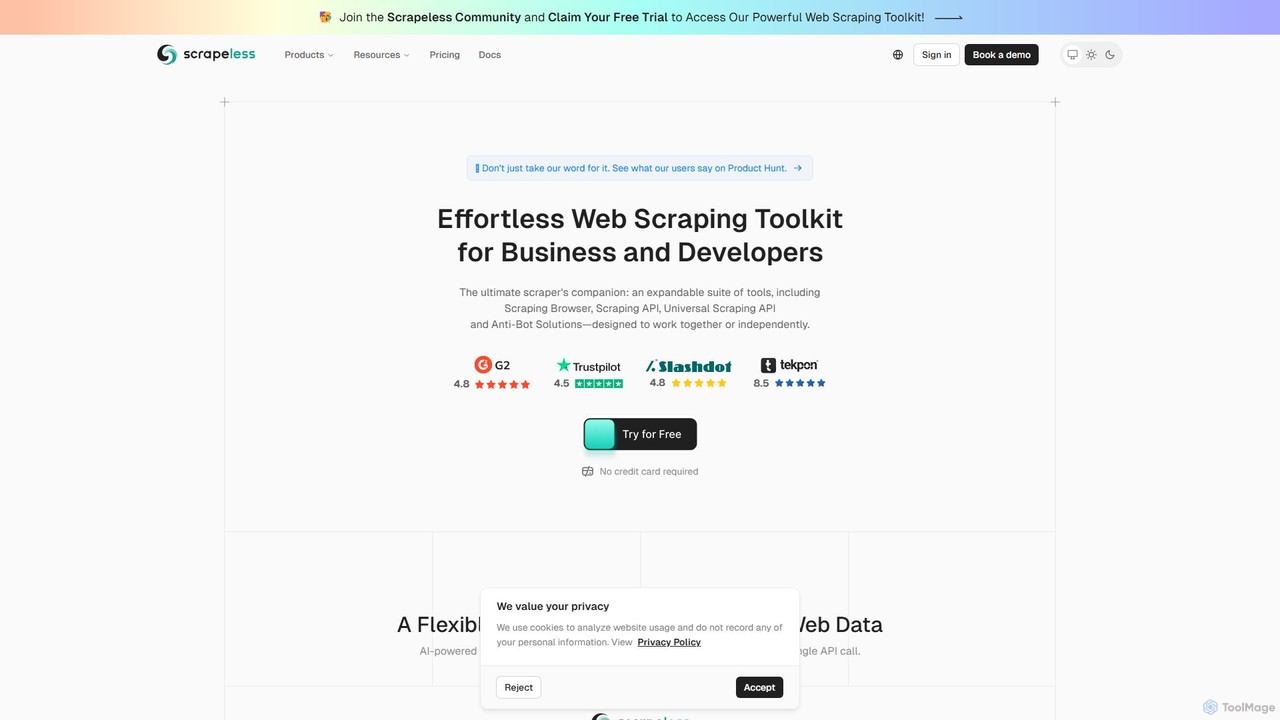
An AI-powered web scraping toolkit for developers and businesses. It offers a suite of tools including a Scraping Browser, Universal Scraping API, and Deep SERP API to effortlessly extract public web data at scale. It specializes in bypassing anti-bot measures, providing structured data for e-commerce, market research, and AI model training, with a focus on reliability and ease of use.
Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.
| Quick facts | hystruct | Scrapeless |
|---|---|---|
| Pricing model | Freemium | Freemium |
| Product type | Web | Web |
| Primary focus | Scraping | Scraping |
| Audience and roles | No data available | No data available |
| Categories | Scraping · Api · Lead Generation · Automation | Scraping · Api · Seo · Automation |
| Added | Aug 4, 2025 | Aug 4, 2025 |
| Updated | Nov 19, 2026 | Nov 19, 2026 |
Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.
hystruct is an advanced, AI-driven web scraping platform designed to make data extraction from any website effortless and efficient. It empowers users, regardless of their technical expertise, to convert unstructured web pages into clean, structured data. By leveraging artificial intelligence, hystruct eliminates the need for manual data entry or complex coding, automating the entire process from URL input to data output. The platform is built for a wide range of users, from individuals and small teams to large enterprises, providing a scalable solution for diverse data needs.
Using hystruct is a simple, three-step process designed for maximum efficiency:
hystruct is versatile and can be applied to numerous scenarios:
hystruct offers a significant competitive edge by simplifying a traditionally complex task. Its main advantages include speed, by automating what would take hours of manual work or coding; accessibility, by providing a no-code solution for all skill levels; and flexibility, through its support for both simple and complex data extraction needs with custom schemas and API access. The integration capabilities further enhance productivity by fitting directly into existing business workflows.
hystruct offers a tiered pricing model to suit different needs:
Scrapeless is an advanced, AI-driven web scraping platform designed to simplify and scale data extraction for businesses and developers. It's not just a single tool, but a flexible toolkit comprising a Scraping Browser, a Universal Scraping API, and a specialized Deep SERP API. This suite is engineered to handle everything from simple data gathering to complex anti-bot challenges, ensuring seamless access to public web data. By leveraging AI, Scrapeless automates the process of bypassing blocks, parsing content, and delivering structured, actionable data, making it an essential companion for anyone needing reliable web information.
Using Scrapeless is designed to be a straightforward process, integrating powerful scraping capabilities through a simple API interface. Here's a typical workflow:
1. Sign Up & Get API Key: Register for a free account on the Scrapeless website. No credit card is required for the trial, which gives you immediate access to your personal API key from the dashboard.
2. Choose the Right Tool: Based on your needs, select the appropriate service. Use the Universal Scraping API for general-purpose scraping of any public website. Opt for the Deep SERP API for targeted, real-time extraction of structured search engine results. For websites with heavy JavaScript and complex anti-bot measures, the Scraping Browser is the ideal choice.
3. Integrate into Your Code: Use the provided code examples available on the dashboard to integrate Scrapeless into your application. It's fully compatible with all major programming languages like Python, Node.js, Java, Go, and more.
4. Make an API Call: Construct your API request with your target URL and any specific parameters you need, such as geolocation for SERP queries or session management settings.
5. Let Scrapeless Do the Work: Once the request is sent, Scrapeless handles all the complexities in the background. This includes managing a vast proxy network, rotating IP addresses, solving CAPTCHAs, and using real browser fingerprints to mimic human behavior and avoid getting blocked.
6. Receive Structured Data: You receive clean, structured data in JSON format, ready for immediate use in your applications, databases, or AI models. You only pay for successful requests, ensuring cost-efficiency.
Scrapeless is a versatile tool applicable across various industries and functions:
• E-commerce & Market Intelligence: Track competitor product prices, monitor stock levels, analyze pricing strategies, and aggregate customer reviews from any e-commerce platform or marketplace.
• SEO & Content Strategy: Utilize the Deep SERP API to monitor keyword rankings in real-time, analyze SERP features, track brand mentions, and discover content opportunities.
• AI and Machine Learning: Fuel Large Language Models (LLMs) and Retrieval-Augmented Generation (RAG) systems with fresh, structured, and relevant data from across the web, enhancing the accuracy and timeliness of AI-driven insights.
• Lead Generation: Systematically extract contact information, company details, and other relevant data from business directories, professional networks, and corporate websites to build targeted lead lists.
• Financial Data Analysis: Gather real-time stock market data, financial news, and economic indicators from various online sources to perform market trend analysis and inform investment strategies.
The platform provides a distinct competitive edge through several key advantages:
• Simplicity and Speed: A single, unified API replaces the need to build and maintain a complex infrastructure of proxies, headless browsers, and parsers, saving significant development time and operational overhead.
• High Success Rate: The intelligent, AI-driven anti-bot technology ensures a consistently high rate of successful requests, minimizing failures, retries, and data gaps.
• Cost-Effectiveness: With a 'pay for success' model, users are only charged for successfully retrieved data, which maximizes the return on investment and eliminates wasted budget on failed attempts.
• Unmatched Scalability: The robust infrastructure is engineered to handle millions of requests, allowing your data operations to scale effortlessly from small projects to enterprise-level workloads.
• Guaranteed Data Quality: Optional data cleaning and transformation services ensure that the data you receive is accurate, structured, and ready for immediate analysis and integration.
• Ethical and Secure: Scrapeless demonstrates a strong commitment to data privacy, GDPR compliance, and the ethical use of web scraping technology, providing a reliable and trustworthy service.
Scrapeless operates on a flexible freemium and usage-based pricing model, designed to accommodate a wide range of users, from individual developers to large enterprises.
• Free Trial: New users can sign up without a credit card to receive a free trial. This trial provides a generous number of credits to fully test the entire suite of tools, including the Universal API and SERP API.
• Pay-As-You-Go: This plan is ideal for smaller projects or users with intermittent scraping needs. You can purchase credits as needed and pay only for successful API calls. Different APIs may have varying credit costs based on their complexity.
• Subscription Plans (e.g., Starter, Pro, Business): For users with consistent, high-volume needs, Scrapeless offers monthly subscription plans. These plans provide a large volume of credits at a discounted rate compared to Pay-As-You-Go, along with additional benefits like higher concurrency limits, faster support, and advanced features.
• Enterprise Plan: For businesses with large-scale or unique data requirements, the Enterprise Plan offers a fully customized solution. This includes dedicated infrastructure, custom-built scrapers, data processing and cleaning, real-time data delivery pipelines, and a comprehensive Service Level Agreement (SLA) to guarantee performance and uptime.
Pricing is transparent, with costs often calculated per 1,000 successful requests (e.g., the Deep SerpApi is advertised at $0.1/1k queries), ensuring you can easily predict and manage your expenses.
Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.
Traffic is shown on the same scale so differences in market visibility are not visually understated.
Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.
| Country/region | Percentage | Estimated visits |
|---|---|---|
| 🇺🇸United States | 100% | 1.4K |
| Country/region | Percentage | Estimated visits |
|---|---|---|
| 🇻🇳Vietnam | 33.19% | 25.6K |
| 🇮🇳India | 20.82% | 16K |
| 🇺🇸United States | 18.39% | 14.2K |
| 🇳🇬Nigeria | 14.7% | 11.3K |
| 🇧🇷Brazil | 12.9% | 9.9K |
| Source type | Percentage | Estimated visits |
|---|---|---|
| Direct | 60.21% | 46.4K |
| Referral | 39.79% | 30.6K |
Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.
This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.