ToolMage
Sign in

AI TOOL COMPARISON

Crawly vs Simplescraper

What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.

Jump to key differences

Product overview

Crawly Product overview

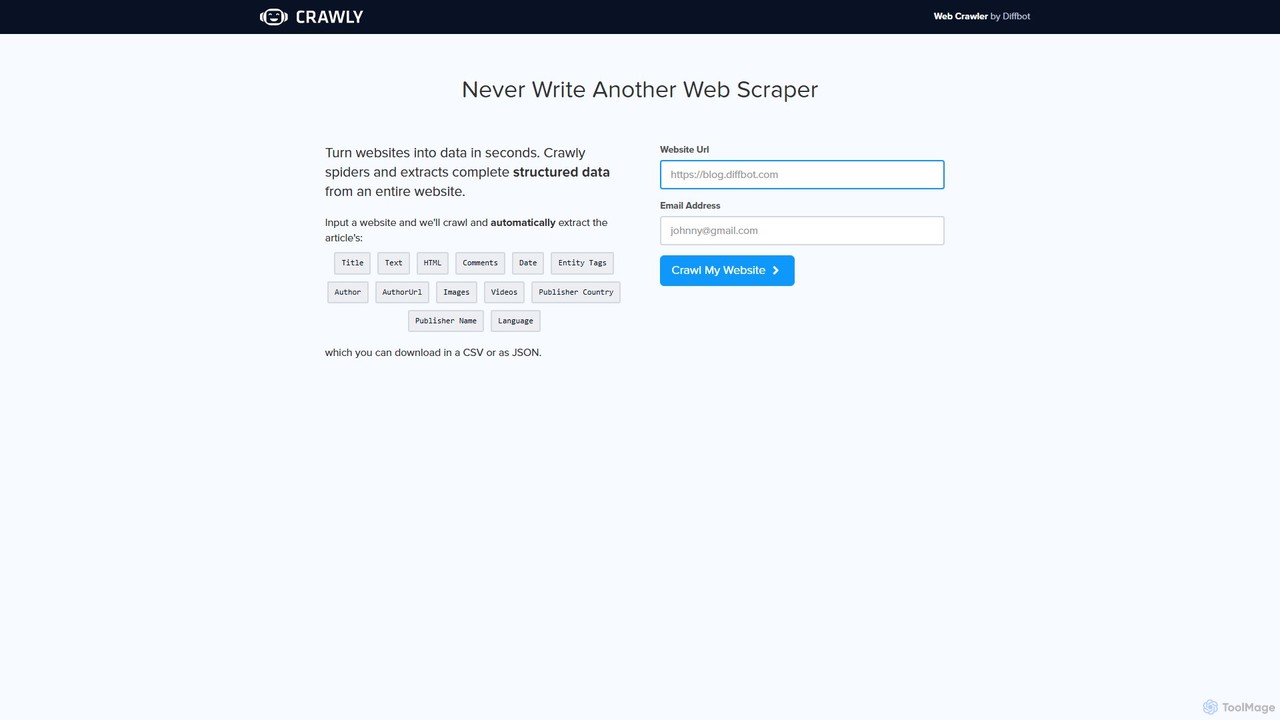
Crawly is an AI-powered web crawler by Diffbot that automatically extracts structured data from entire websites. Simply input a URL, and Crawly spiders the site to pull key information like articles, products, and discussions, converting it into clean JSON or CSV data without any coding required.

Preview

Simplescraper Product overview

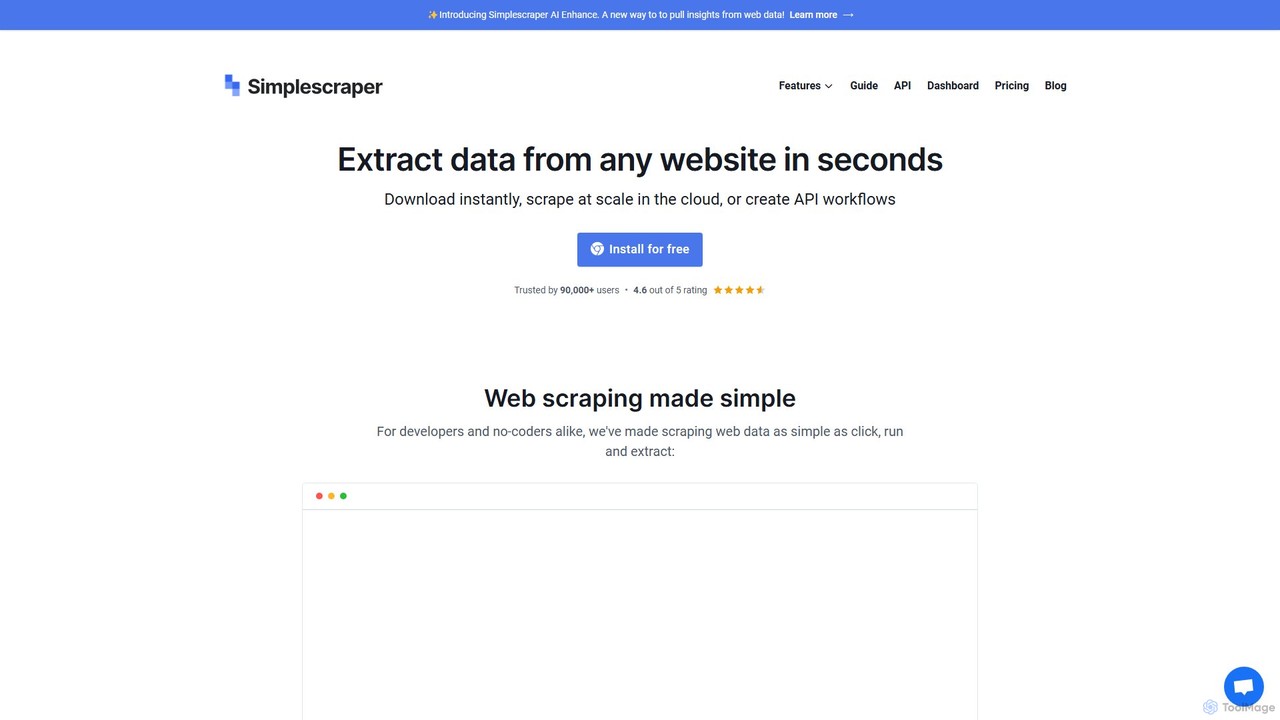
Simplescraper is a powerful web scraping tool that extracts data from any website in seconds. It offers a user-friendly Chrome extension for no-code data selection, cloud-based automation for large-scale scraping, and an innovative AI Enhance feature to pull insights using simple prompts. Turn websites into structured data (CSV, JSON) or instant APIs, and integrate with tools like Google Sheets and Airtable.

Preview

Quick facts

Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.

Crawly VS Simplescraper — Quick facts
Quick factsCrawlySimplescraper
Pricing modelFreemiumFreemium
Product typeWebWeb
Primary focusWeb ScrapingWeb Scraping
Audience and rolesNo data availableNo data available
CategoriesWeb Scraping · Api · Market Research · AutomationWeb Scraping · Api · Lead Generation · Automation
AddedAug 10, 2025Aug 17, 2025
UpdatedNov 19, 2026Nov 19, 2026

Features, usage and use cases

Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.

Crawly

Crawly is a powerful and intelligent web crawler developed by Diffbot, a leader in AI-powered data extraction. It is designed to completely eliminate the manual and technical challenges of web scraping. Instead of writing complex code or using fragile selectors that break with website updates, Crawly leverages advanced artificial intelligence, including computer vision and natural language processing, to understand and interpret web pages like a human. This allows it to automatically identify and extract complete, structured data from an entire website with just a single URL as input.

The core promise of Crawly is to 'turn websites into data in seconds.' It navigates through a website, following links and analyzing the structure of each page to differentiate between various content types such as articles, products, discussions, and image galleries. The extracted data is then organized into a clean, structured format, ready for immediate use in applications, data analysis, or machine learning models.

How to use Crawly

Using Crawly is designed to be incredibly simple and accessible to everyone, regardless of technical skill. The process involves just a few steps:

  1. Input URL: Navigate to the Crawly website. In the provided input field, enter the full URL of the website you wish to crawl.
  2. Provide Email: Enter your email address. This is used to notify you and deliver the results once the crawl is complete.
  3. Initiate Crawl: Click the 'Crawl My Website' button. Crawly's AI engine will then begin to spider the entire site, analyzing pages and extracting information.
  4. Download Data: Once the process is finished, you will receive the extracted data. You can download it in convenient, structured formats like JSON or CSV, making it easy to import into databases, spreadsheets, or other software.

Core Features of Crawly

  • AI-Powered Automatic Extraction: Utilizes Diffbot's advanced AI to automatically recognize and extract data from articles, products, discussions, and more without any manual configuration.
  • Comprehensive Data Fields: Extracts a rich set of data points, including Title, Text, HTML, Comments, Date, Author, Author URL, Images, Videos, Publisher Information (Country, Name), and Language.
  • Entity Recognition: Automatically identifies and tags entities within the text, such as people, organizations, and locations, adding another layer of valuable metadata.
  • Full Site Crawling: Unlike single-page scrapers, Crawly navigates an entire website to gather data comprehensively.
  • Structured Data Output: Delivers clean, well-structured data in JSON or CSV formats, eliminating the need for post-processing and data cleaning.
  • No-Code Solution: Requires no programming skills or knowledge of web scraping technologies, making it accessible to marketers, researchers, and business analysts.
  • Robust and Resilient: Because it understands the content's semantic structure, it is not easily broken by website layout changes, a common problem with traditional scrapers.

Use Cases for Crawly

Crawly is a versatile tool suitable for a wide range of applications:

  • Market Research: Automatically gather competitor product information, pricing, customer reviews, and news mentions to gain a competitive edge.
  • Lead Generation: Extract contact details, company information, and key personnel from corporate websites and online directories.
  • Content Aggregation: Build a custom news feed or content platform by aggregating articles, blog posts, and videos from multiple sources.
  • Data for Machine Learning: Create large, high-quality datasets for training machine learning models, such as sentiment analysis on product reviews or trend analysis from news articles.
  • Brand Monitoring: Keep track of how your brand, products, or executives are mentioned across the web in real-time.

Advantages of Crawly

The primary advantage of Crawly is its simplicity and power. It democratizes web data extraction, allowing non-developers to perform tasks that would typically require a team of engineers. It saves immense amounts of time and resources by automating the entire scraping process. Furthermore, its AI-driven approach ensures higher accuracy and greater resilience than traditional methods, providing a reliable stream of high-quality data. By being a product of Diffbot, it is backed by enterprise-grade technology trusted by major corporations worldwide.

Pricing and Plans

Crawly offers a free trial crawl directly from its homepage, allowing users to test its capabilities by entering a URL and an email address. This is designed to provide a sample of the structured data that the tool can produce. For more extensive needs, such as large-scale crawling, frequent data extraction, or API access for programmatic use, users would typically subscribe to the full suite of tools offered by its parent company, Diffbot. Diffbot's pricing is tiered, with plans available for startups, businesses, and large enterprises, offering different levels of API calls and features.

Simplescraper

Simplescraper is a comprehensive web scraping service designed to make data extraction accessible to everyone, from no-coders to experienced developers. Trusted by over 90,000 users, it transforms any website into a source of structured, actionable data. With its intuitive Chrome extension, you can simply click on the data you need, and with its cloud platform, you can run large-scale, automated scraping tasks on a schedule. The standout feature, Simplescraper AI Enhance, allows you to use natural language prompts to extract, summarize, and analyze web content, eliminating the need for complex configurations or CSS selectors.

How to use Simplescraper

Getting started with Simplescraper is straightforward and offers multiple pathways depending on your needs:

  1. Using the Chrome Extension (Recommended): Install the free extension from the Chrome Store. Navigate to the website you want to scrape, click the extension icon, and start selecting the data elements (like text, links, or images) you wish to extract. You can immediately view the results and download them as a CSV or JSON file.
  2. Saving a Recipe for Cloud Scraping: For recurring or large-scale tasks, save your selections as a 'recipe'. This recipe can then be run in the cloud, allowing you to scrape thousands of pages, handle pagination and infinite scroll, and schedule scrapes to run automatically.
  3. Using Smart Extract: For an even simpler AI-driven approach, go to the Smart Extract feature on the dashboard. Just provide a URL and describe the data you need (e.g., "product name, price, and customer rating"). The AI will analyze the page and automatically generate a reusable scrape recipe for you.
  4. Leveraging AI Enhance: After running a scrape, go to the 'AI Enhance' tab for that recipe. You can apply pre-defined or custom prompts to your scraped data to perform tasks like sentiment analysis on reviews, summarizing articles, or formatting addresses.
  5. API Integration: Every scrape recipe you create instantly becomes an API endpoint. You can call this API to get fresh data on demand, making it perfect for dynamic applications and workflows.

Core Features of Simplescraper

  • AI-Powered Extraction: Utilizes AI through 'Smart Extract' to identify data based on simple descriptions and 'AI Enhance' to process and analyze scraped content using natural language prompts.
  • No-Code Interface & Chrome Extension: An intuitive point-and-click interface that makes it easy for anyone to select and extract data without writing a single line of code.
  • Scalable Cloud Scraping: Run unlimited scraping tasks of any size. The platform handles complex scenarios like JavaScript-powered websites (Single Page Apps), pagination, infinite scroll, and login walls.
  • Instant API Generation: Automatically turns any website you scrape into a structured API, allowing for programmatic access to fresh data.
  • Comprehensive Integrations: Seamlessly send your data to Google Sheets, Airtable, Zapier, or any other application using webhooks, enabling automated workflows.
  • Advanced Scraping Toolkit: Features include proxy rotation to avoid blocks, reCaptcha solving, deep scraping (crawling links to extract data from subsequent pages), and the ability to scrape only unique entries to avoid duplicates.
  • Scheduled Scraping: Set your scrapes to run at any interval you choose, from every minute to once a month, ensuring your data is always up-to-date.

Use Cases for Simplescraper

Simplescraper is versatile and can be applied across various industries for numerous purposes:

  • E-commerce: Track competitor pricing, monitor product availability, aggregate customer reviews, and collect product catalog data.
  • Real Estate: Scrape property listings from sites like Zillow to gather data on prices, locations, square footage, and agent details for market analysis.
  • Lead Generation: Extract contact information from online directories, professional networks, and corporate websites to build sales lead lists.
  • Market Research: Gather data on market trends, analyze public sentiment from social media or forums, and collect data for academic or business research.
  • Financial Services: Collect stock market data, financial news, and economic indicators from various online sources.
  • Recruitment: Aggregate job postings from multiple job boards to find talent or analyze the job market.

Advantages of Simplescraper

Simplescraper stands out for its combination of simplicity and power. Its primary advantage is its user-friendly design, which democratizes web scraping for non-technical users. The AI features significantly lower the barrier to entry, as users no longer need to understand HTML structure or CSS selectors. For developers, it offers a robust, scalable backend and a powerful API that saves hundreds of hours of development time. The reliability of the cloud infrastructure, complete with proxy rotation and CAPTCHA solving, ensures high success rates for scraping tasks.

Pricing and Plans

Simplescraper offers a freemium model with plans designed to scale with your needs:

  • Free: Includes use of the browser extension for manual scraping and 100 free starter credits for automated cloud scraping.
  • Plus Plan: $39/month for 6,000 credits, scheduling, Google Sheet & Airtable integration, webhooks, and access to AI Enhance.
  • Pro Plan: $70/month for 15,000 credits, including all Plus features plus SERP (Search Engine Results Page) scraping capabilities.
  • Premium Plan: $150/month for 40,000 credits and all Pro features.
  • Scale Plan: $249/month for 100,000 credits, which also includes a recipe setup service and live data feeds.

All paid plans come with dedicated one-on-one support. Credits are used for cloud scraping tasks, with a standard page costing 1 credit and a JavaScript-heavy page costing 2 credits. AI Enhance usage is billed separately at 1 credit per 800 words processed.

Positioning

Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.

Categories

Shared
Web ScrapingApiAutomation
Only Crawly
Market Research
Only Simplescraper
Lead Generation

Tags

Shared
APIautomationdata extractionlead generationmarket researchno-codeweb scraping
Only Crawly
DiffbotJSONstructured dataweb crawler
Only Simplescraper
AI data extractiondata miningprice tracking

Audience and roles

Shared
No listed items
Only Crawly
No listed items
Only Simplescraper
No listed items

Traffic comparison

Traffic is shown on the same scale so differences in market visibility are not visually understated.

How to interpret the traffic data

Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.

Crawly monthly traffic:

Latest traffic · 2026-05

Monthly visits
1.8K
Avg. visit duration
0:31
Pages per visit
1.15
Bounce rate
93.85%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 2.6K
  • 2026-01: 784
  • 2026-02: 640
  • 2026-03: 1K
  • 2026-04: 475
  • 2026-05: 1.8K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇳🇬Nigeria82.43%1.5K
🇩🇪Germany9.9%177
🇨🇦Canada7.67%137

Search keywords

crawl urlcrawlyonline web crawlerwebsite crawlerwebsite crawler online

Simplescraper monthly traffic:

Latest traffic · 2026-05

Monthly visits
104.7K
Avg. visit duration
0:28
Pages per visit
1.75
Bounce rate
48.21%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 93.6K
  • 2026-01: 112.3K
  • 2026-02: 106.1K
  • 2026-03: 101.8K
  • 2026-04: 116.8K
  • 2026-05: 104.7K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇺🇸United States47.86%50.1K
🇮🇳India28.08%29.4K
🇧🇷Brazil8.48%8.9K
🇬🇧United Kingdom8.15%8.5K
🇫🇷France7.43%7.8K

Traffic sources

Source typePercentageEstimated visits
Direct88.2%92.4K
Referral11.73%12.3K
Email0.07%73

Search keywords

extract urllink extractorsimplescraperurl extractorwebsite url extractor

Community signals

Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.

Crawly

Rating
No data available
Comments
0
Favorites
162
Likes
160

Simplescraper

Rating
No data available
Comments
0
Favorites
172
Likes
172

Crawly vs Simplescraper · Comparison FAQ

What do Crawly and Simplescraper have in common?
Both tools are listed under Web Scraping、Api、Automation. These categories indicate overlapping use cases; compare their detailed descriptions for workflows, capabilities and limitations.
Are Crawly and Simplescraper free?
Listed pricing models: Crawly — Freemium; Simplescraper — Freemium. Missing pricing is not proof of a free plan, and freemium does not mean every feature is free. Check official sites for current plans, limits and trials.
How should I choose between Crawly and Simplescraper?
The primary listed category is Web Scraping for Crawly, and Web Scraping for Simplescraper. Compare features, steps and use cases, then verify pricing, data permissions and deployment needs. This page does not include hands-on testing and does not declare a winner from traffic or tags.

Sources and comparison methodology

This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.

  • Feature and plan descriptions reflect information in the listings, not real-time guarantees. Verify pricing, quotas, availability and privacy terms on the official sites.
  • Traffic uses the reporting months shown. Missing statistics do not mean zero visits, and different periods do not establish growth or superiority. Regional and source visit counts are estimates based on shares.
  • Different tags indicate differences in the listings, not proof that the other product lacks a capability. Ratings, favorites and visits are not used to declare a winner.

Related comparisons