

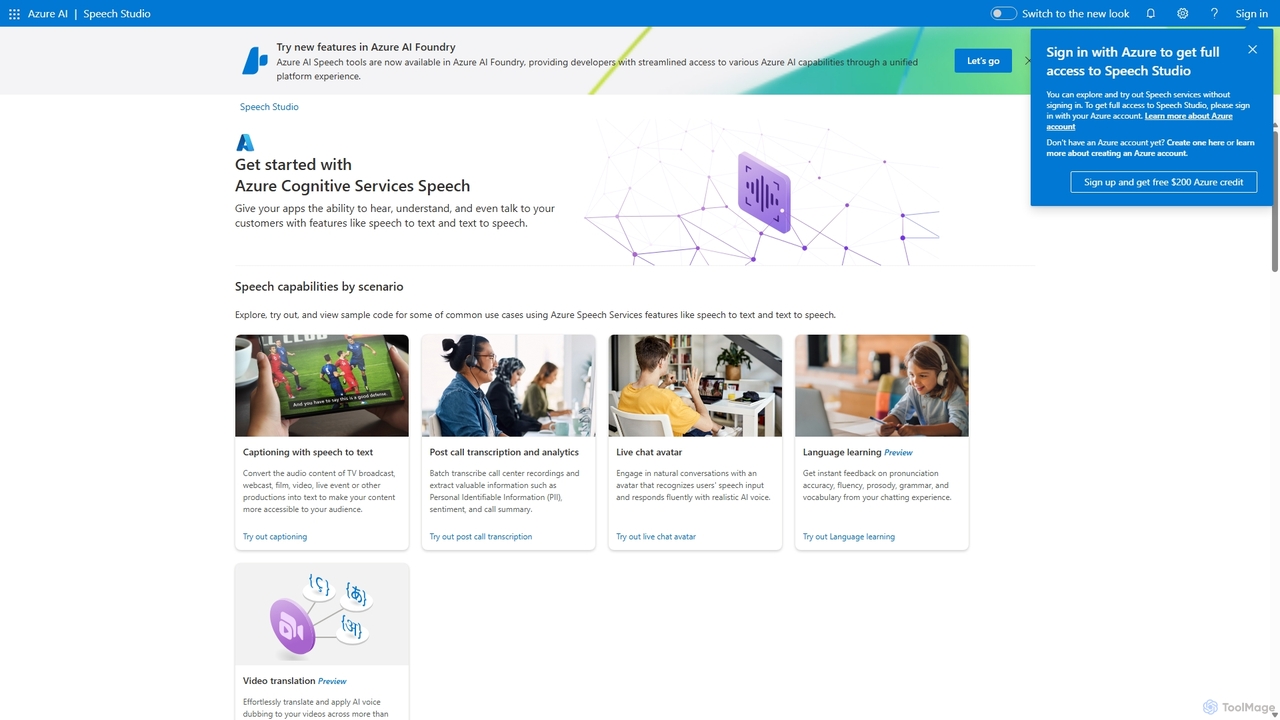
Speech Studio Overview
Speech Studio, part of Microsoft Azure AI Services, is a unified platform that provides developers with all the necessary tools to integrate sophisticated speech processing capabilities into their applications. It empowers applications to hear, understand, and speak to users with remarkable accuracy and naturalness. The platform is designed for both simple integrations and complex, customized solutions, catering to a wide array of industries and use cases.
How to use Speech Studio
Getting started with Speech Studio involves a few key steps. First, users need an Azure account and must create a Speech resource within the Azure portal. Once set up, you can access the Speech Studio web portal. Here, you can explore and test various features without writing any code, such as real-time speech-to-text, browsing the voice gallery, or creating audio content. For application integration, developers can use the comprehensive Speech SDK (available for languages like Python, C#, Java, and JavaScript) or the REST API. For advanced customization, you can upload your own datasets to train custom models, such as a Custom Speech model for specific terminology or a Custom Neural Voice for a unique brand identity.
Core Features of Speech Studio
- Speech-to-Text (STT): Accurately transcribe audio from various sources in over 100 languages and dialects. It supports real-time and batch transcription, and includes features like the Whisper model for enhanced accuracy and Pronunciation Assessment for language learning scenarios.
- Custom Speech: Improve transcription accuracy for domain-specific vocabulary, accents, or noisy environments by training a model with your own audio and text data.
- Text-to-Speech (TTS): Convert text into lifelike speech using a vast library of over 400 neural voices across more than 150 languages. It supports various speaking styles and emotions.
- Custom Voice: Create a unique, high-quality voice for your brand. Options include Professional Voice (requiring studio recordings) and Personal Voice (created from a small sample of speech).
- Speech Translation: Perform real-time speech-to-speech and speech-to-text translation across numerous languages with low latency, breaking down communication barriers.
- Voice Assistant: Build fully-featured conversational interfaces. This includes creating custom keywords (wake words) to activate devices and experiences.
- Text-to-Speech Avatar: Generate photorealistic talking avatars that sync with synthesized speech, creating highly engaging and interactive user experiences.
- Video Translation: Effortlessly translate and apply AI voice dubbing to videos, making content globally accessible.
Use Cases for Speech Studio
Speech Studio's versatility allows it to be applied in numerous scenarios. In contact centers, it's used for post-call transcription and analytics to gauge sentiment and extract key information. Media companies use it for real-time captioning of live events and for dubbing videos into multiple languages. In the education sector, it powers language learning apps with instant pronunciation feedback. For accessibility, it provides voice control for applications and real-time transcription for the hearing-impaired. Retail and service industries can create branded voice assistants and interactive avatars to enhance customer engagement.
Advantages of Speech Studio
The primary advantage of Speech Studio is its integration within the robust and scalable Microsoft Azure ecosystem. It offers state-of-the-art accuracy in both recognition and synthesis. The platform's extensive customization options allow businesses to create truly unique and brand-aligned voice experiences. With support for a vast number of languages and dialects, it provides global reach. Furthermore, Microsoft emphasizes Responsible AI, providing guidelines and tools to ensure the ethical and fair use of these powerful speech technologies.
Pricing and Plans
Speech Studio operates on a pay-as-you-go pricing model, which is typical for Azure services. It includes a generous free tier that allows for a certain amount of usage per month at no cost (e.g., a set number of audio hours for speech-to-text). Beyond the free limits, pricing is based on usage, such as per audio hour for transcription or per million characters for text-to-speech. The cost can vary depending on the specific feature used (e.g., standard vs. custom models). For detailed and up-to-date pricing information, users should consult the official Azure Speech services pricing page.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 209.6K
- 2026-1: 189.6K
- 2026-2: 108.3K
- 2026-3: 183.4K
- 2026-4: 151.9K
- 2026-5: 241.3K
Geography
Top 5 countries / regions
- 🇨🇳China25.7%
- 🇺🇸United States24.8%
- 🇰🇷South Korea23.2%
- 🇯🇵Japan13.4%
- 🇭🇰Hong Kong SAR China12.9%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 76.8% |
Referral | 22.8% |
Email | 0.5% |
Top keywords
| Keyword | Cost per click |
|---|---|
| azure speech studio | $2.83 |
| microsoft azure speech studio | $0.00 |
| microsoft text to speech | $1.68 |
| speech | $1.86 |
| 微软 ai 语音在线 | $0.00 |
Speech Studio Alternatives
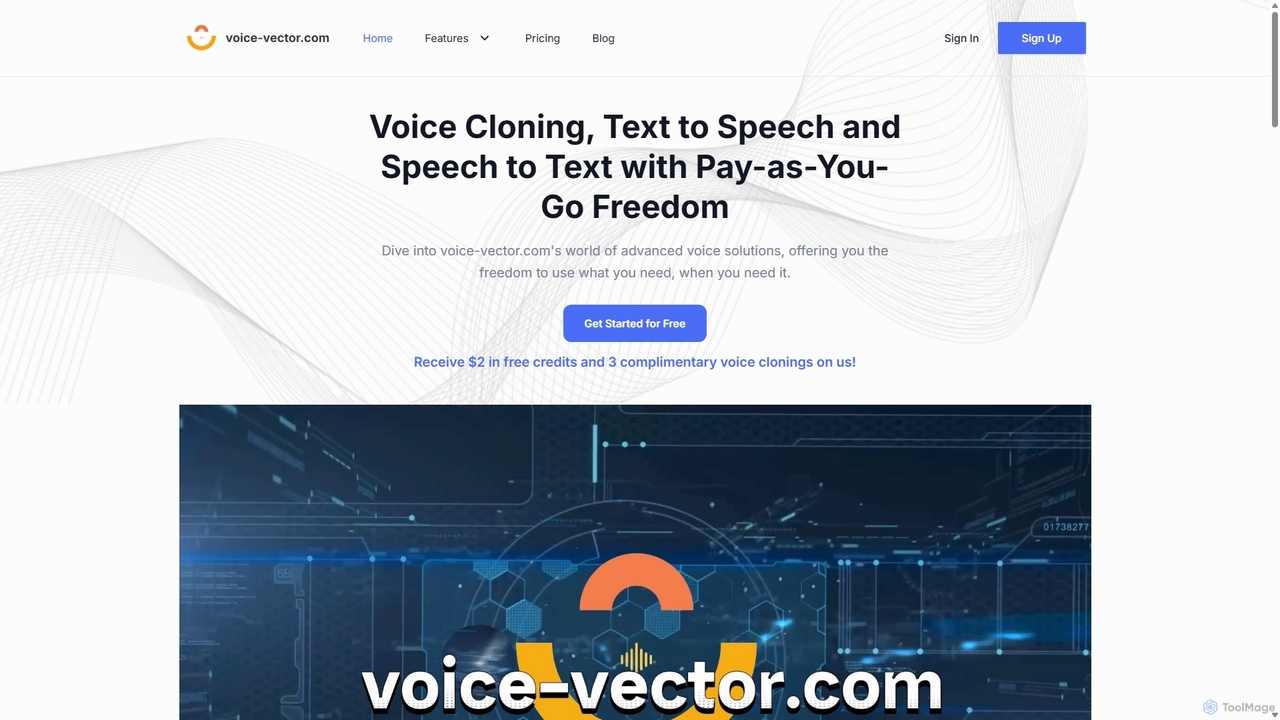
voice_vector
voice_vector is a powerful AI voice platform offering high-fidelity voice cloning, expressive text-to-speech (TTS), and accurate speech recognition. With a unique pay-as-you-go and subscription hybrid model, it provides a flexible, cost-effective solution for content creators, developers, and businesses. Create unlimited private cloned voices and integrate advanced voice capabilities into your projects via a robust API.
Text To Speech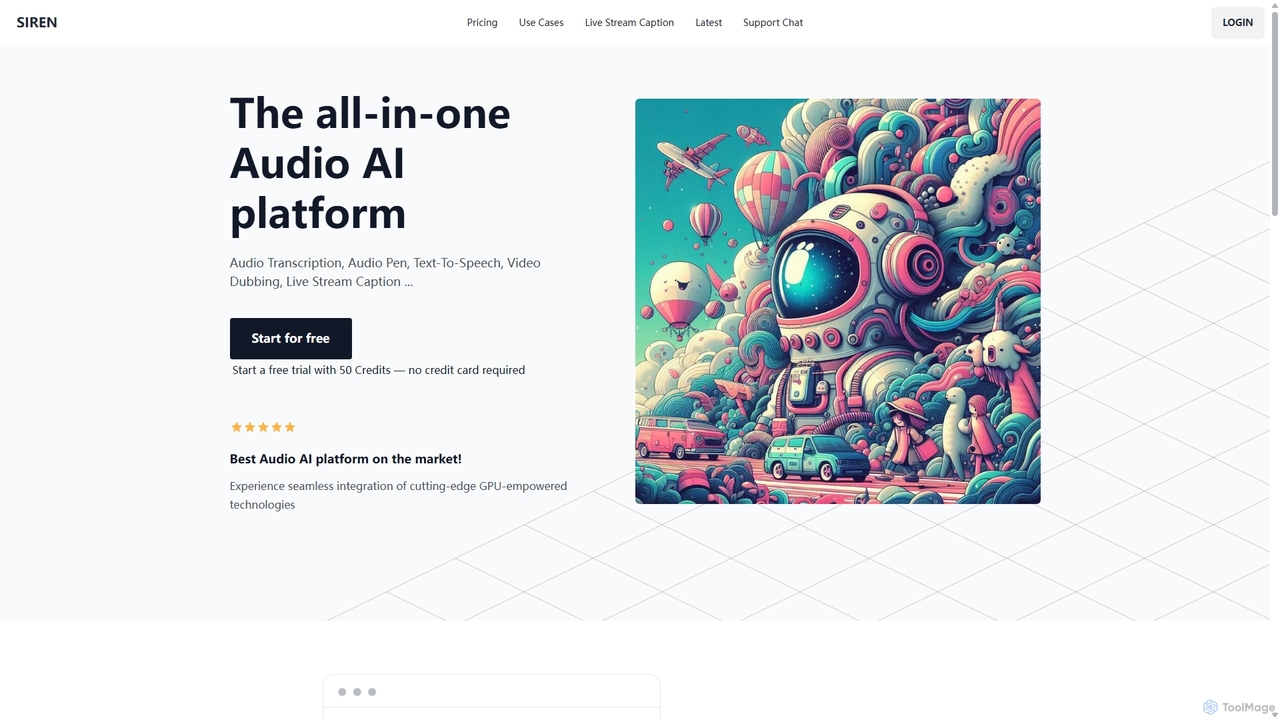
SIREN
SIREN is an all-in-one, GPU-accelerated AI audio platform. It offers high-accuracy audio transcription, natural text-to-speech with 420+ voices, seamless video dubbing in over 100 languages, and real-time live stream captioning. Designed for creators, marketers, and businesses, SIREN simplifies complex audio tasks into a single, efficient workflow.
Text To Speech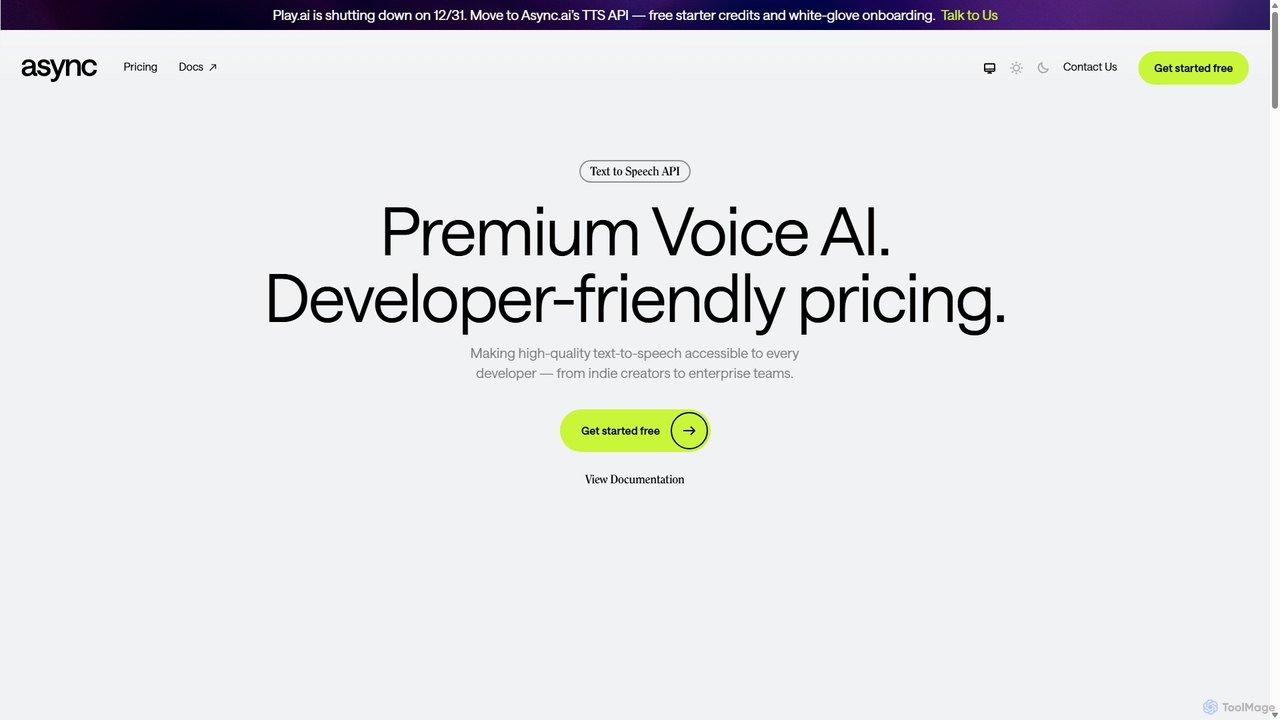
Async
Async is a developer-focused AI platform offering a fast, realistic Text-to-Speech (TTS) and instant voice cloning API. It provides high-quality, expressive voices in over 20 languages, designed for easy integration into any application, from prototypes to enterprise-level products. With competitive pricing and a generous free tier, Async makes premium voice AI accessible to all developers.
Voice Generation
Play.ht
Play.ht is a leading AI voice generator and text-to-speech platform that creates ultra-realistic, human-like voices. With a library of over 800 AI voices in more than 40 languages, it's perfect for creating professional voiceovers, audiobooks, podcasts, and e-learning content. The platform supports advanced features like voice cloning, multi-speaker dialogues, and detailed emotional tuning.
Text To Speech
Narration Box
Narration Box is an advanced AI voice generator and text-to-speech platform offering over 700+ ultra-realistic voices in more than 80 languages and 140 accents. It features instant voice cloning, an intuitive studio editor, and emotional fine-tuning, making it ideal for creating professional-grade audio for audiobooks, podcasts, e-learning, and marketing content.
Text To SpeechSpeech Studio Categories
Speech Studio Jobs
Speech Studio Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
voice_vector
voice_vector is a powerful AI voice platform offering high-fidelity voice cloning, expressive text-to-speech (TTS), and accurate speech recognition. With a unique pay-as-you-go and subscription hybrid model, it provides a flexible, cost-effective solution for content creators, developers, and businesses. Create unlimited private cloned voices and integrate advanced voice capabilities into your projects via a robust API.
Text To SpeechAsync
Async is a developer-focused AI platform offering a fast, realistic Text-to-Speech (TTS) and instant voice cloning API. It provides high-quality, expressive voices in over 20 languages, designed for easy integration into any application, from prototypes to enterprise-level products. With competitive pricing and a generous free tier, Async makes premium voice AI accessible to all developers.
Voice GenerationPlay.ht
Play.ht is a leading AI voice generator and text-to-speech platform that creates ultra-realistic, human-like voices. With a library of over 800 AI voices in more than 40 languages, it's perfect for creating professional voiceovers, audiobooks, podcasts, and e-learning content. The platform supports advanced features like voice cloning, multi-speaker dialogues, and detailed emotional tuning.
Text To SpeechNarration Box
Narration Box is an advanced AI voice generator and text-to-speech platform offering over 700+ ultra-realistic voices in more than 80 languages and 140 accents. It features instant voice cloning, an intuitive studio editor, and emotional fine-tuning, making it ideal for creating professional-grade audio for audiobooks, podcasts, e-learning, and marketing content.
Text To Speech
Voiser
Voiser is an advanced AI platform offering high-quality text-to-speech (TTS), accurate speech-to-text (transcription), and innovative voice cloning services. Supporting over 75 languages with 550+ voices, it provides a comprehensive suite of tools for content creators, businesses, and developers, including talking avatars, YouTube dubbing, and API integration.
Text To Speech
Noiz
Noiz is an advanced AI voice platform for text-to-speech, voice cloning, and instant video dubbing. Create lifelike voices, clone any voice from a 3-10 second audio clip, and translate your content into multiple languages while preserving the original vocal characteristics. Ideal for content creators, marketers, and developers.
Voice Synthesis
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
All Voice Lab
All Voice Lab is an advanced AI audio platform offering high-fidelity voice cloning, emotionally expressive text-to-speech (TTS), and a professional voice changer. Powered by its proprietary MaskGCT model, it enables creators and businesses to produce realistic, multilingual audio content for audiobooks, video dubbing, e-learning, and more, with a strong focus on security and ease of use.
Voice Synthesis
Voisi
Voisi is a comprehensive AI audio toolkit that enables users to create realistic voice content. It features text-to-speech, voice cloning, translation, transcription, and AI music generation. With over 450 voices in hundreds of languages, it's designed for content creators, marketers, and developers to produce high-quality narrations, podcasts, and voice-overs effortlessly. The platform integrates multiple top-tier AI engines to ensure the best possible output quality.
Voice Generation
Cartesia
Cartesia is a high-performance voice AI platform for developers, offering the fastest, ultra-realistic Text-to-Speech (TTS), real-time Voice Cloning, and low-latency Speech-to-Text (STT). Powered by proprietary State Space Model technology, it's designed for building interactive and immersive voice applications with seamless integration and enterprise-grade security.
Voice SynthesisSIREN
SIREN is an all-in-one, GPU-accelerated AI audio platform. It offers high-accuracy audio transcription, natural text-to-speech with 420+ voices, seamless video dubbing in over 100 languages, and real-time live stream captioning. Designed for creators, marketers, and businesses, SIREN simplifies complex audio tasks into a single, efficient workflow.
Text To Speech
Voice.ai
Voice.ai is a versatile AI voice platform offering a free real-time voice changer, realistic text-to-speech, and precise voice cloning. Designed for gamers, streamers, content creators, and businesses, it features a vast library of user-generated voices, enabling seamless voice transformation across popular apps and games.
Text To Speech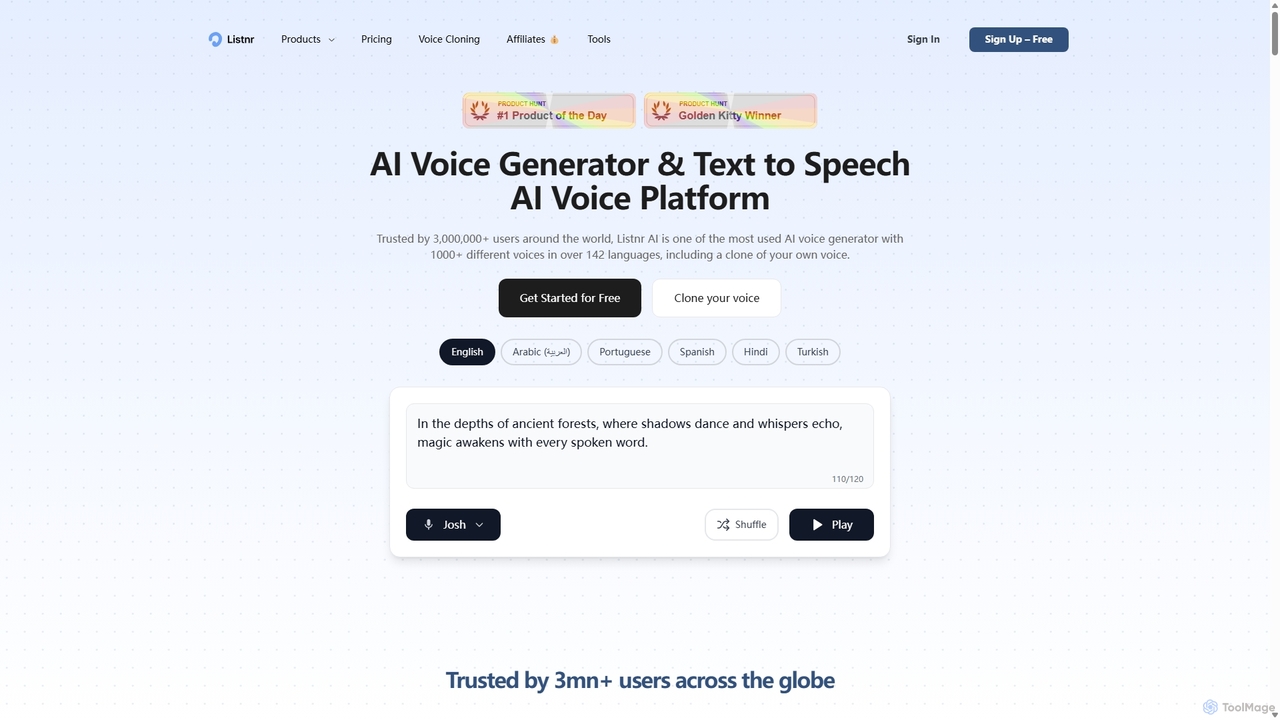
Listnr
Listnr is a leading AI voice generator offering ultra-realistic text-to-speech, voice cloning, and AI voiceovers. With over 1000 voices in 142+ languages, it's an all-in-one platform for creating podcasts, video voiceovers, audiobooks, and social media content. It also includes tools for AI video generation and podcast hosting, making it a comprehensive solution for content creators.
Text To Speech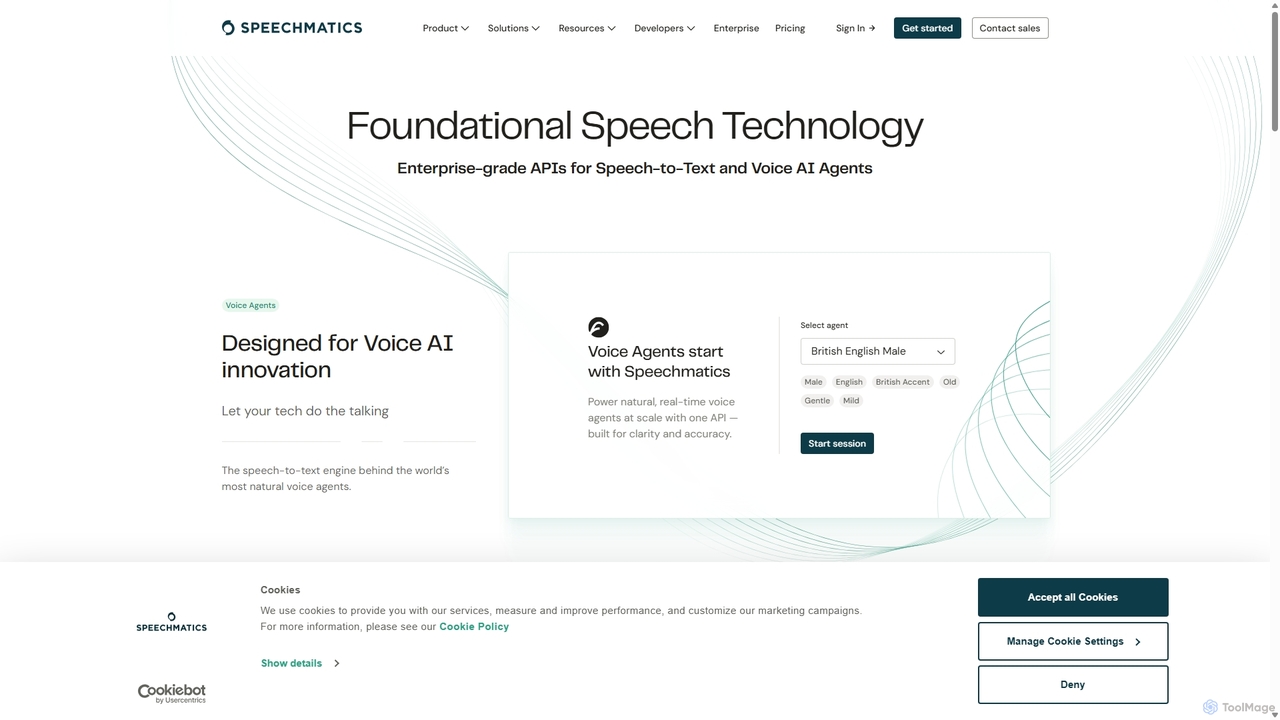
Speechmatics
Speechmatics is a leading AI-powered speech-to-text API, providing highly accurate and scalable transcription services for businesses. It supports over 50 languages in real-time and batch modes, offering flexible deployment options including cloud and on-premises solutions. Designed for developers, it enables the integration of advanced voice recognition into any application, from contact centers to media captioning.
Speech To Text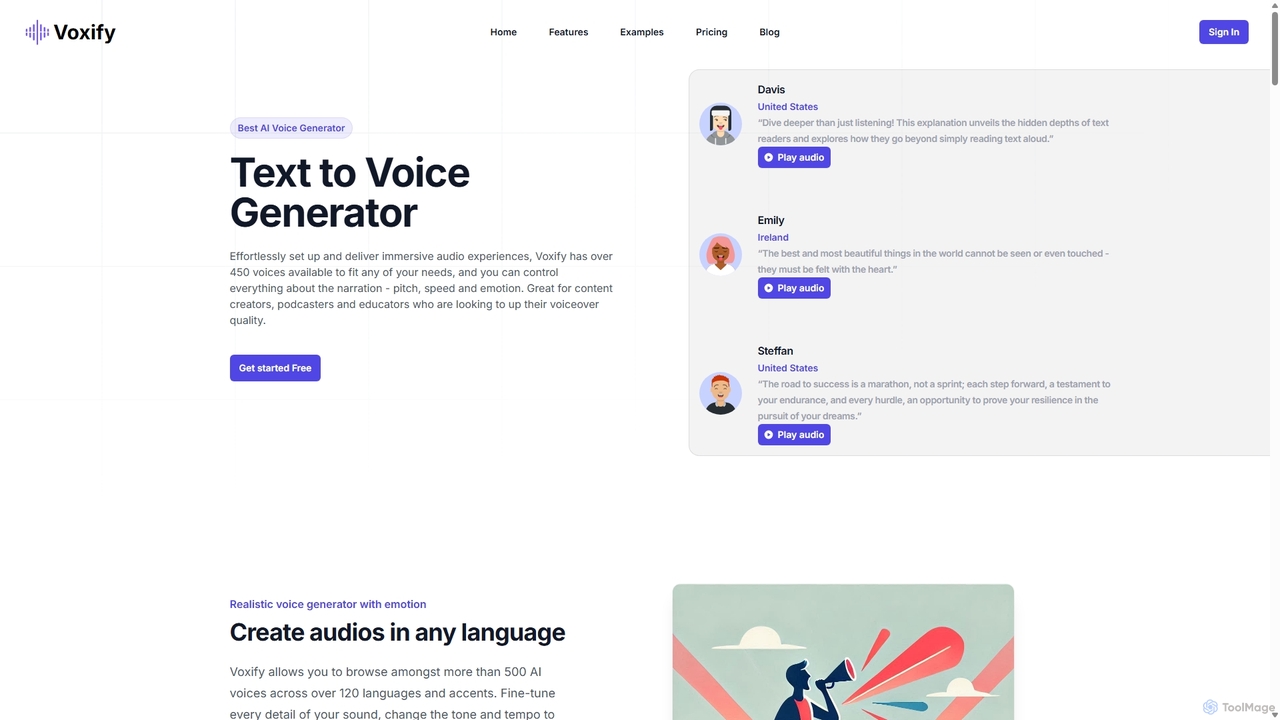
Voxify
Voxify is a powerful AI voice generator that converts text to speech with remarkable realism. It offers over 450 voices across 140+ languages and accents, allowing users to customize pitch, speed, and emotion. Ideal for content creators, podcasters, and educators seeking high-quality, customizable voiceovers.
Text To Speech
Speech Studio Comments (0)
Sign in to comment.
Sign inNo comments yet.