ToolMage
Sign in

AI TOOL COMPARISON

Diffbot vs Hyperbrowser

What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.

Jump to key differences

Product overview

Diffbot Product overview

Diffbot is an AI-powered platform that transforms the unstructured web into a massive, structured Knowledge Graph. It offers APIs for web data extraction, crawling, and natural language processing, enabling businesses to access clean, organized data on organizations, news, products, and more for applications in finance, market intelligence, and risk management.

Preview

Hyperbrowser Product overview

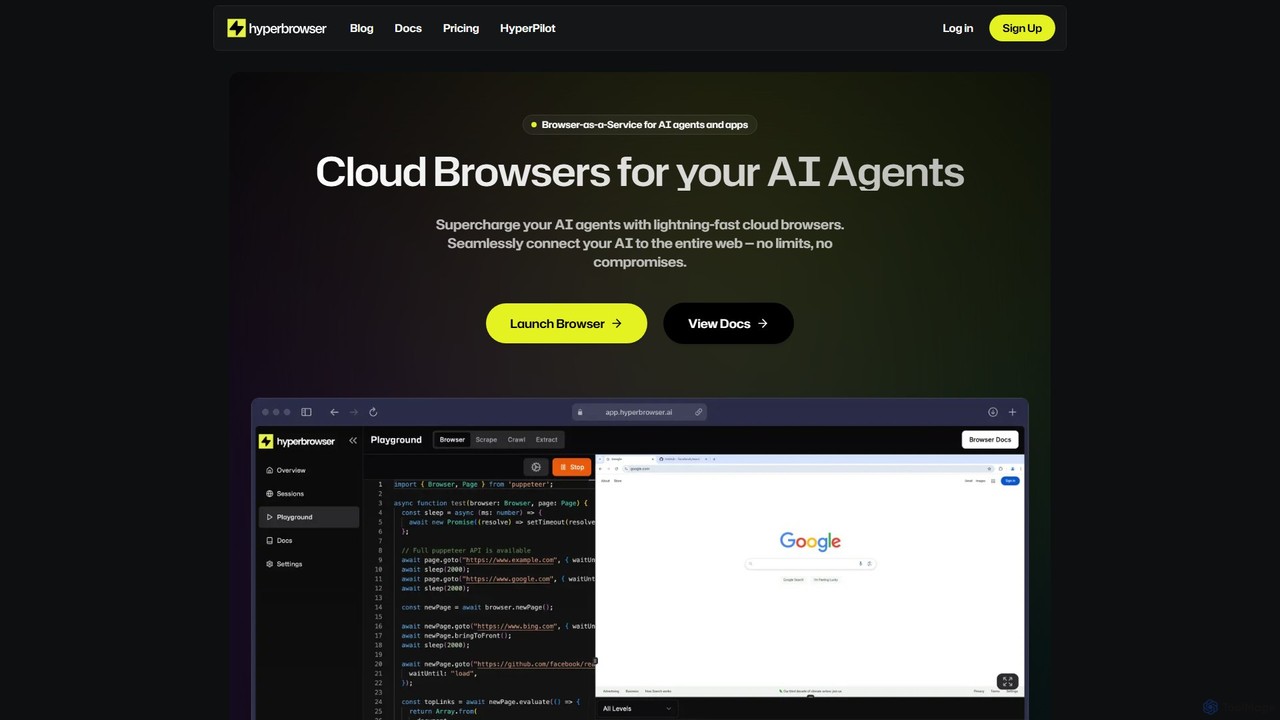
Hyperbrowser is a Browser-as-a-Service platform designed for AI agents and developers. It provides scalable, lightning-fast cloud browsers to automate web tasks, extract data, and enable AI-driven web interactions. With features like stealth browsing, automatic captcha solving, and developer-friendly APIs, it empowers complex workflows without limits.

Preview

Quick facts

Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.

Diffbot VS Hyperbrowser — Quick facts
Quick factsDiffbotHyperbrowser
Pricing modelFreemiumFreemium
Product typeWebWeb
Primary focusMarket IntelligenceWeb Scraping
Audience and rolesNo data availableNo data available
CategoriesMarket Intelligence · Web Scraping · Api · AutomationWeb Scraping · Api · Automation
AddedAug 9, 2025Aug 5, 2025
UpdatedNov 19, 2026Nov 19, 2026

Features, usage and use cases

Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.

Diffbot

Diffbot provides a suite of AI-powered tools designed to understand and structure the content of the public web, effectively turning it into the world's largest, most comprehensive database. At its core is the Diffbot Knowledge Graph, a massive, interconnected repository of data about organizations, people, articles, products, and more. Unlike traditional web scrapers that require manual rules for each website, Diffbot uses computer vision and natural language processing to automatically interpret web pages like a human, extracting structured data without site-specific configurations.

This technology allows developers and businesses to stop wrestling with the noisy, chaotic nature of web data and instead access it as if it were a clean, structured database. Whether you need to monitor news, enrich customer profiles, conduct market research, or power a machine learning model, Diffbot provides the clean, reliable data feeds required to build intelligent applications.

How to use Diffbot

Getting started with Diffbot is designed to be straightforward for developers and data teams. The primary interaction is through its powerful APIs.

  1. Sign Up: Begin by creating an account. Diffbot offers a free plan with 10,000 credits and full API access, allowing you to test the platform's capabilities without a credit card.
  2. Get Your API Token: Once registered, you'll receive an API token from your dashboard. This token is used to authenticate all your requests to the Diffbot APIs.
  3. Choose the Right API: Diffbot offers several distinct APIs for different tasks:
    • Extract API: Point it at any URL (like an article, product page, or forum discussion), and it will automatically return structured JSON data. No rules needed.
    • Crawl API: Provide a starting URL, and Diffbot will systematically crawl the entire site, using the Extract API to turn every relevant page into structured data. This is ideal for building a database from a specific website.
    • Knowledge Graph Search API: Query the pre-built Knowledge Graph to find information on over 246 million organizations, 1.6 billion articles, and more. You can search for entities and build precise data feeds.
    • Knowledge Graph Enhance API: Provide your own data (e.g., a company name), and Diffbot will enrich it with comprehensive data from the Knowledge Graph, such as revenue, employee count, social profiles, and recent news.
    • Natural Language API: Submit raw text to infer entities, relationships between them, and perform sentiment analysis.
  4. Integrate and Build: Use the API responses (in JSON format) to power your applications, populate your databases, or feed your analytics dashboards. For real-time needs, you can set up webhooks for instant notifications, such as new articles mentioning a specific company.

Core Features of Diffbot

  • Knowledge Graph: A massive, pre-crawled, and continuously updated graph of the web, containing structured information on organizations, people, products, articles, and their relationships.
  • Automatic Extraction: AI-driven technology that automatically identifies and extracts key information from various page types (articles, products, discussions, etc.) without requiring manual setup or rules.
  • Crawlbot: An intelligent web crawler that can turn an entire website into a structured database, automatically identifying and extracting content from relevant pages.
  • Natural Language Processing (NLP): Advanced NLP capabilities to understand text in over 20 languages, perform entity recognition (distinguishing 'Apple' the company from 'apple' the fruit), and conduct sentiment analysis at the topic level.
  • Data Enrichment (Enhance API): The ability to take a minimal piece of information, like a company name or email, and enrich it with dozens of data points from the Knowledge Graph.
  • Real-time Monitoring: Build custom, noise-free feeds for news and brand mentions with real-time alerts via email or webhooks.

Use Cases for Diffbot

Diffbot's structured data is valuable across numerous industries and functions:

  • Market Intelligence: Track competitors, monitor industry trends, and analyze market movements by tapping into global news, company filings, and product data.
  • Risk & Compliance: Perform due diligence on companies and individuals, monitor supply chains for risk signals, and stay ahead of regulatory changes.
  • Sales & Marketing: Enrich lead data in CRMs, identify new prospects based on specific criteria (e.g., companies in a certain industry that just received funding), and personalize outreach.
  • News & Media Monitoring: Create highly specific, real-time news feeds that track mentions of brands, people, or topics with precise entity matching and sentiment analysis.
  • Recruiting: Build databases of potential candidates, identify talent, and enrich professional profiles with data from across the web.
  • Machine Learning: Use the Knowledge Graph as a source of high-quality, structured training data for various AI and machine learning models.

Advantages of Diffbot

The primary advantage of Diffbot is its ability to treat the entire web as a single, queryable database. It abstracts away the complexity of web scraping and data cleaning. Key benefits include accuracy, scale, and efficiency. Instead of building and maintaining fragile, site-specific scrapers, users can rely on a single, robust API. The entity-aware NLP ensures data quality and relevance, while the pre-built Knowledge Graph provides immediate access to a vast dataset that would take years to build in-house.

Pricing and Plans

Diffbot offers a tiered pricing structure to accommodate different levels of usage, from hobby projects to large enterprises.

  • Free Plan: $0/month. Includes 10,000 credits, full API access, and is free forever. Ideal for testing and small projects.
  • Startup Plan: $299/month. Includes 250,000 credits and is designed for small teams needing plug-and-play scraping and Knowledge Graph access.
  • Plus Plan: $899/month. Includes 1,000,000 credits, access to the Crawl product, and higher API call rates. Suitable for growing businesses with more significant data needs.
  • Enterprise Plan: Custom pricing. Offers bespoke plans with custom credit allotments, the highest API call rates, premium SLA support, and managed solutions for large-scale data operations.

Credits are consumed based on the type and complexity of the API call. A detailed breakdown is available on their website.

Hyperbrowser

Hyperbrowser is a powerful Browser-as-a-Service (BaaS) platform engineered to connect AI agents and applications to the entire web. It provides developers with access to a fleet of high-speed, secure, and scalable cloud browsers, eliminating the complexities of managing local browser instances. This service is specifically designed for demanding tasks such as large-scale web scraping, browser automation, and enabling sophisticated AI agents to interact with websites as a human would. By offering headless browsers in isolated containers, Hyperbrowser ensures reliability, security, and peak performance for any project, from simple data extraction to complex, mission-critical automated workflows.

How to use Hyperbrowser

Getting started with Hyperbrowser is a straightforward process designed for developers. First, you sign up on the website to create an account and obtain your unique API key. You can start with the generous free plan which requires no credit card. Once you have your key, you can integrate Hyperbrowser into your application using its developer-friendly SDKs for Python and NodeJS, or by making direct cURL requests to its API. The platform provides clear documentation and code examples, including integrations with popular AI frameworks like OpenAI Tools and Anthropic Tools. For instance, you can launch a browser session, assign a task to an AI agent (e.g., 'Order Garlic Noodles from Burma Love on Doordash'), and have Hyperbrowser manage the entire web interaction, returning the structured result.

Core Features of Hyperbrowser

  • Scalable Cloud Browsers: Run over 1,000 concurrent browsers with zero performance degradation, launching in under 500ms for instant scaling.
  • Advanced Browser Automation: Automate any browser-based task, including complex web scraping, automated testing, and filling out forms across multiple sites.
  • AI Agent Integration: Seamlessly connect with AI agents from frameworks like OpenAI and Anthropic, enabling them to browse the web, collect data, and interact with web applications to complete tasks.
  • Automatic Captcha Solving: Integrated captcha handling automatically solves various types of captchas (including reCAPTCHA) to ensure your automation workflows run uninterrupted.
  • Stealth Browsing: Operate in advanced stealth mode to bypass sophisticated bot detection systems, ensuring high success rates for data collection and automation.
  • Robust Session Management: Manage browser sessions with features like logging, debugging, secure resource isolation, and the ability to reuse user profiles to avoid repeated logins.
  • Developer-Friendly API: A simple and powerful API with official SDKs for Python and NodeJS, making integration into your existing tech stack smooth and efficient.

Use Cases for Hyperbrowser

Hyperbrowser is versatile and can be applied to a wide range of scenarios. Its primary use cases include: Large-Scale Web Scraping, where users can extract and structure data from millions of pages, such as scraping Google search results or e-commerce sites like Shopify without getting blocked. Another key application is powering AI Web Agents, enabling them to perform complex actions like booking appointments, making purchases, or conducting detailed competitive analysis. It is also invaluable for Automated Software Testing, allowing developers to run end-to-end tests in real browser environments at scale. Furthermore, businesses use it for Market Research and Competitive Analysis by automating the collection of data on competitors' pricing, products, and marketing strategies.

Advantages of Hyperbrowser

The main advantage of Hyperbrowser is its ability to provide scalable, reliable, and undetectable browser automation. The platform guarantees 99.9% uptime, making it suitable for mission-critical applications. Its lightning-fast, sub-second browser launch times allow for rapid scaling on demand. The built-in fault tolerance and auto-recovery mechanisms ensure that workflows are resilient and reliable. Most importantly, its advanced stealth capabilities and automatic captcha solving significantly increase the success rate of web automation tasks that would otherwise be blocked by anti-bot measures.

Pricing and Plans

Hyperbrowser offers a flexible, transparent pricing structure with a freemium model to suit different needs.
Free Plan: $0/month, includes 1,000 credits, 1 concurrent browser, 7 days of data retention, and basic stealth mode.
Startup Plan: $30/month (plus usage), includes 30,000 credits, 25 concurrent browsers, 30 days of data retention, auto captcha solving, and basic stealth mode.
Scale Plan: $100/month (plus usage), includes 100,000 credits, 100 concurrent browsers, 30 days of data retention, auto captcha solving, and advanced stealth mode.
Enterprise Plan: Custom pricing for high-volume needs, offering 250+ concurrent browsers, 180+ days of data retention, premium support, and compliance options like HIPAA/SOC 2.
Usage is billed at $0.001 per credit, $0.10 per browser hour, and $10 per GB of proxy data.

Positioning

Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.

Categories

Shared
Web ScrapingApiAutomation
Only Diffbot
Market Intelligence
Only Hyperbrowser
No listed items

Tags

Shared
APIdata extractiondeveloper toolsweb scraping
Only Diffbot
business intelligencedata enrichmentknowledge graphmarket intelligencenatural language processingnews monitoringweb crawling
Only Hyperbrowser
AI agentbrowser automationcaptcha solvingheadless browserstealth browsing

Audience and roles

Shared
No listed items
Only Diffbot
No listed items
Only Hyperbrowser
No listed items

Traffic comparison

Traffic is shown on the same scale so differences in market visibility are not visually understated.

How to interpret the traffic data

Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.

Diffbot monthly traffic:

Latest traffic · 2026-05

Monthly visits
47.2K
Avg. visit duration
0:36
Pages per visit
2.02
Bounce rate
38.73%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 65.5K
  • 2026-01: 49.6K
  • 2026-02: 69.2K
  • 2026-03: 61.7K
  • 2026-04: 44.6K
  • 2026-05: 47.2K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇺🇸United States31.36%14.8K
🇳🇬Nigeria28.45%13.4K
🇮🇳India20.17%9.5K
🇬🇧United Kingdom11.29%5.3K
🇵🇰Pakistan8.73%4.1K

Traffic sources

Source typePercentageEstimated visits
Direct89.5%42.2K
Referral8.3%3.9K
Email2.2%1K

Search keywords

crawlydifbotdiffbotdiffbot apiwebsite content extractor

Hyperbrowser monthly traffic:

Latest traffic · 2026-05

Monthly visits
71.4K
Avg. visit duration
0:38
Pages per visit
2.21
Bounce rate
40.26%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 34.5K
  • 2026-01: 71.4K
  • 2026-02: 66.8K
  • 2026-03: 67.3K
  • 2026-04: 56.7K
  • 2026-05: 71.4K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇺🇸United States43.97%31.4K
🇮🇳India28.23%20.2K
🇻🇳Vietnam12.18%8.7K
🇧🇷Brazil8.2%5.9K
🇩🇪Germany7.42%5.3K

Traffic sources

Source typePercentageEstimated visits
Direct91.73%65.5K
Referral7.22%5.2K
Email1.05%750

Search keywords

hyper agenthyperagenthyper browserhyperbrowserhyperbrowser ai

Community signals

Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.

Diffbot

Rating
No data available
Comments
0
Favorites
196
Likes
188

Hyperbrowser

Rating
No data available
Comments
0
Favorites
153
Likes
162

Diffbot vs Hyperbrowser · Comparison FAQ

What do Diffbot and Hyperbrowser have in common?
Both tools are listed under Web Scraping、Api、Automation. These categories indicate overlapping use cases; compare their detailed descriptions for workflows, capabilities and limitations.
Are Diffbot and Hyperbrowser free?
Listed pricing models: Diffbot — Freemium; Hyperbrowser — Freemium. Missing pricing is not proof of a free plan, and freemium does not mean every feature is free. Check official sites for current plans, limits and trials.
How should I choose between Diffbot and Hyperbrowser?
The primary listed category is Market Intelligence for Diffbot, and Web Scraping for Hyperbrowser. Compare features, steps and use cases, then verify pricing, data permissions and deployment needs. This page does not include hands-on testing and does not declare a winner from traffic or tags.

Sources and comparison methodology

This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.

  • Feature and plan descriptions reflect information in the listings, not real-time guarantees. Verify pricing, quotas, availability and privacy terms on the official sites.
  • Traffic uses the reporting months shown. Missing statistics do not mean zero visits, and different periods do not establish growth or superiority. Regional and source visit counts are estimates based on shares.
  • Different tags indicate differences in the listings, not proof that the other product lacks a capability. Ratings, favorites and visits are not used to declare a winner.

Related comparisons