

Diffbot Overview
Diffbot provides a suite of AI-powered tools designed to understand and structure the content of the public web, effectively turning it into the world's largest, most comprehensive database. At its core is the Diffbot Knowledge Graph, a massive, interconnected repository of data about organizations, people, articles, products, and more. Unlike traditional web scrapers that require manual rules for each website, Diffbot uses computer vision and natural language processing to automatically interpret web pages like a human, extracting structured data without site-specific configurations.
This technology allows developers and businesses to stop wrestling with the noisy, chaotic nature of web data and instead access it as if it were a clean, structured database. Whether you need to monitor news, enrich customer profiles, conduct market research, or power a machine learning model, Diffbot provides the clean, reliable data feeds required to build intelligent applications.
How to use Diffbot
Getting started with Diffbot is designed to be straightforward for developers and data teams. The primary interaction is through its powerful APIs.
- Sign Up: Begin by creating an account. Diffbot offers a free plan with 10,000 credits and full API access, allowing you to test the platform's capabilities without a credit card.
- Get Your API Token: Once registered, you'll receive an API token from your dashboard. This token is used to authenticate all your requests to the Diffbot APIs.
- Choose the Right API: Diffbot offers several distinct APIs for different tasks:
- Extract API: Point it at any URL (like an article, product page, or forum discussion), and it will automatically return structured JSON data. No rules needed.
- Crawl API: Provide a starting URL, and Diffbot will systematically crawl the entire site, using the Extract API to turn every relevant page into structured data. This is ideal for building a database from a specific website.
- Knowledge Graph Search API: Query the pre-built Knowledge Graph to find information on over 246 million organizations, 1.6 billion articles, and more. You can search for entities and build precise data feeds.
- Knowledge Graph Enhance API: Provide your own data (e.g., a company name), and Diffbot will enrich it with comprehensive data from the Knowledge Graph, such as revenue, employee count, social profiles, and recent news.
- Natural Language API: Submit raw text to infer entities, relationships between them, and perform sentiment analysis.
- Integrate and Build: Use the API responses (in JSON format) to power your applications, populate your databases, or feed your analytics dashboards. For real-time needs, you can set up webhooks for instant notifications, such as new articles mentioning a specific company.
Core Features of Diffbot
- Knowledge Graph: A massive, pre-crawled, and continuously updated graph of the web, containing structured information on organizations, people, products, articles, and their relationships.
- Automatic Extraction: AI-driven technology that automatically identifies and extracts key information from various page types (articles, products, discussions, etc.) without requiring manual setup or rules.
- Crawlbot: An intelligent web crawler that can turn an entire website into a structured database, automatically identifying and extracting content from relevant pages.
- Natural Language Processing (NLP): Advanced NLP capabilities to understand text in over 20 languages, perform entity recognition (distinguishing 'Apple' the company from 'apple' the fruit), and conduct sentiment analysis at the topic level.
- Data Enrichment (Enhance API): The ability to take a minimal piece of information, like a company name or email, and enrich it with dozens of data points from the Knowledge Graph.
- Real-time Monitoring: Build custom, noise-free feeds for news and brand mentions with real-time alerts via email or webhooks.
Use Cases for Diffbot
Diffbot's structured data is valuable across numerous industries and functions:
- Market Intelligence: Track competitors, monitor industry trends, and analyze market movements by tapping into global news, company filings, and product data.
- Risk & Compliance: Perform due diligence on companies and individuals, monitor supply chains for risk signals, and stay ahead of regulatory changes.
- Sales & Marketing: Enrich lead data in CRMs, identify new prospects based on specific criteria (e.g., companies in a certain industry that just received funding), and personalize outreach.
- News & Media Monitoring: Create highly specific, real-time news feeds that track mentions of brands, people, or topics with precise entity matching and sentiment analysis.
- Recruiting: Build databases of potential candidates, identify talent, and enrich professional profiles with data from across the web.
- Machine Learning: Use the Knowledge Graph as a source of high-quality, structured training data for various AI and machine learning models.
Advantages of Diffbot
The primary advantage of Diffbot is its ability to treat the entire web as a single, queryable database. It abstracts away the complexity of web scraping and data cleaning. Key benefits include accuracy, scale, and efficiency. Instead of building and maintaining fragile, site-specific scrapers, users can rely on a single, robust API. The entity-aware NLP ensures data quality and relevance, while the pre-built Knowledge Graph provides immediate access to a vast dataset that would take years to build in-house.
Pricing and Plans
Diffbot offers a tiered pricing structure to accommodate different levels of usage, from hobby projects to large enterprises.
- Free Plan: $0/month. Includes 10,000 credits, full API access, and is free forever. Ideal for testing and small projects.
- Startup Plan: $299/month. Includes 250,000 credits and is designed for small teams needing plug-and-play scraping and Knowledge Graph access.
- Plus Plan: $899/month. Includes 1,000,000 credits, access to the Crawl product, and higher API call rates. Suitable for growing businesses with more significant data needs.
- Enterprise Plan: Custom pricing. Offers bespoke plans with custom credit allotments, the highest API call rates, premium SLA support, and managed solutions for large-scale data operations.
Credits are consumed based on the type and complexity of the API call. A detailed breakdown is available on their website.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 65.5K
- 2026-1: 49.6K
- 2026-2: 69.2K
- 2026-3: 61.7K
- 2026-4: 44.6K
- 2026-5: 47.2K
Geography
Top 5 countries / regions
- 🇺🇸United States31.4%
- 🇳🇬Nigeria28.4%
- 🇮🇳India20.2%
- 🇬🇧United Kingdom11.3%
- 🇵🇰Pakistan8.7%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 89.5% |
Referral | 8.3% |
Email | 2.2% |
Top keywords
| Keyword | Cost per click |
|---|---|
| crawly | $0.00 |
| difbot | $0.00 |
| diffbot | $5.10 |
| diffbot api | $0.00 |
| website content extractor | $0.49 |
Diffbot Alternatives
Oxylabs
Oxylabs is a leading provider of premium proxy services and enterprise-level web data gathering solutions. Leveraging a massive, ethically-sourced proxy network of over 177 million IPs, it offers AI-powered Scraper APIs, a Web Unblocker, and the new AI Studio for natural language data extraction. It enables businesses to collect public web data at scale for e-commerce, cybersecurity, brand protection, and market research without getting blocked.
Market Intelligence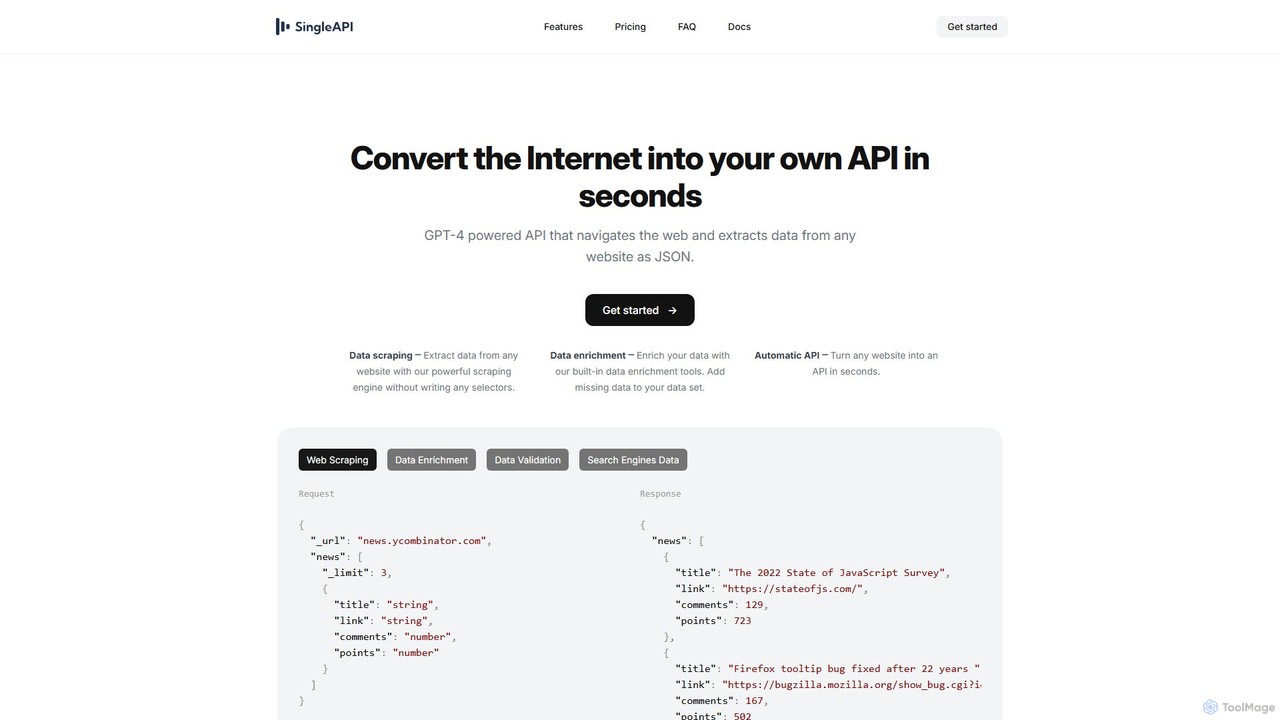
SingleAPI
SingleAPI is a GPT-4 powered tool that instantly converts any website into a structured JSON API. It simplifies web scraping, data extraction, and data enrichment without writing any code or selectors, allowing users to effortlessly access web data for various applications.
Web Scraping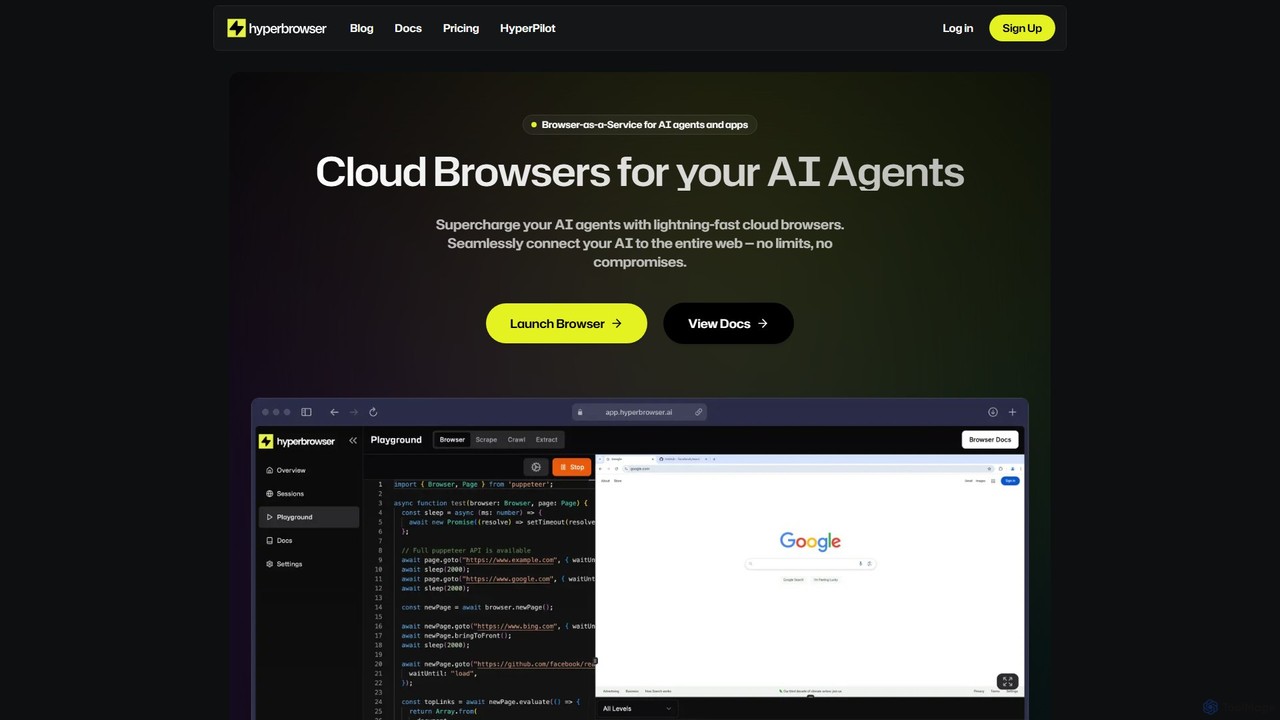
Hyperbrowser
Hyperbrowser is a Browser-as-a-Service platform designed for AI agents and developers. It provides scalable, lightning-fast cloud browsers to automate web tasks, extract data, and enable AI-driven web interactions. With features like stealth browsing, automatic captcha solving, and developer-friendly APIs, it empowers complex workflows without limits.
Web Scraping
Import.io
Import.io is an enterprise-grade web data extraction platform that provides high-quality, structured data from any website. It offers both a fully managed service and a self-service solution to power e-commerce market intelligence, brand monitoring, and data-driven business decisions, overcoming complex anti-scraping technologies.
Market Intelligence
Simplescraper
Simplescraper is a powerful web scraping tool that extracts data from any website in seconds. It offers a user-friendly Chrome extension for no-code data selection, cloud-based automation for large-scale scraping, and an innovative AI Enhance feature to pull insights using simple prompts. Turn websites into structured data (CSV, JSON) or instant APIs, and integrate with tools like Google Sheets and Airtable.
Web ScrapingDiffbot Categories
Diffbot Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
SingleAPI
SingleAPI is a GPT-4 powered tool that instantly converts any website into a structured JSON API. It simplifies web scraping, data extraction, and data enrichment without writing any code or selectors, allowing users to effortlessly access web data for various applications.
Web Scraping
Zyte
Zyte is a comprehensive web scraping platform offering a full-stack API and data extraction services. It simplifies data acquisition by managing proxies, headless browsers, and advanced anti-blocking systems. Powered by AI, Zyte delivers reliable, structured web data at scale for businesses in e-commerce, market research, and more.
Market IntelligenceHyperbrowser
Hyperbrowser is a Browser-as-a-Service platform designed for AI agents and developers. It provides scalable, lightning-fast cloud browsers to automate web tasks, extract data, and enable AI-driven web interactions. With features like stealth browsing, automatic captcha solving, and developer-friendly APIs, it empowers complex workflows without limits.
Web ScrapingImport.io
Import.io is an enterprise-grade web data extraction platform that provides high-quality, structured data from any website. It offers both a fully managed service and a self-service solution to power e-commerce market intelligence, brand monitoring, and data-driven business decisions, overcoming complex anti-scraping technologies.
Market Intelligence
Airtop
Airtop is a browser automation platform designed for AI agents. It allows developers to control and scrape any website using natural language prompts or SDKs (Python, TypeScript). Airtop manages the complex cloud browser infrastructure, handling logins, CAPTCHAs, and scaling, enabling powerful automations for data extraction, social media engagement, and market research.
Automation
SadCaptcha
SadCaptcha is a specialized API service for developers and businesses to bypass TikTok captchas. Using an advanced AI computer vision algorithm, it solves rotate, puzzle, and 3D image challenges with 99% accuracy and instant response times. It integrates seamlessly with any automation framework, enabling uninterrupted TikTok web scraping and automation tasks.
Social Media
UseScraper
UseScraper is a powerful web crawler and scraper API designed for developers and AI applications. It efficiently extracts data from any website, featuring full JavaScript rendering, auto-scaling infrastructure, and clean output formats like Markdown, ideal for feeding data into LLMs like ChatGPT.
Data Extraction
instantapi
instantapi is an AI-powered web scraping API designed for simplicity and speed. It allows users to extract structured data from any website with a single API call, eliminating the need for complex coding or manual setup. Ideal for developers, data analysts, and businesses who need fast, affordable, and reliable data extraction without the hassle of traditional web scrapers.
Data Extraction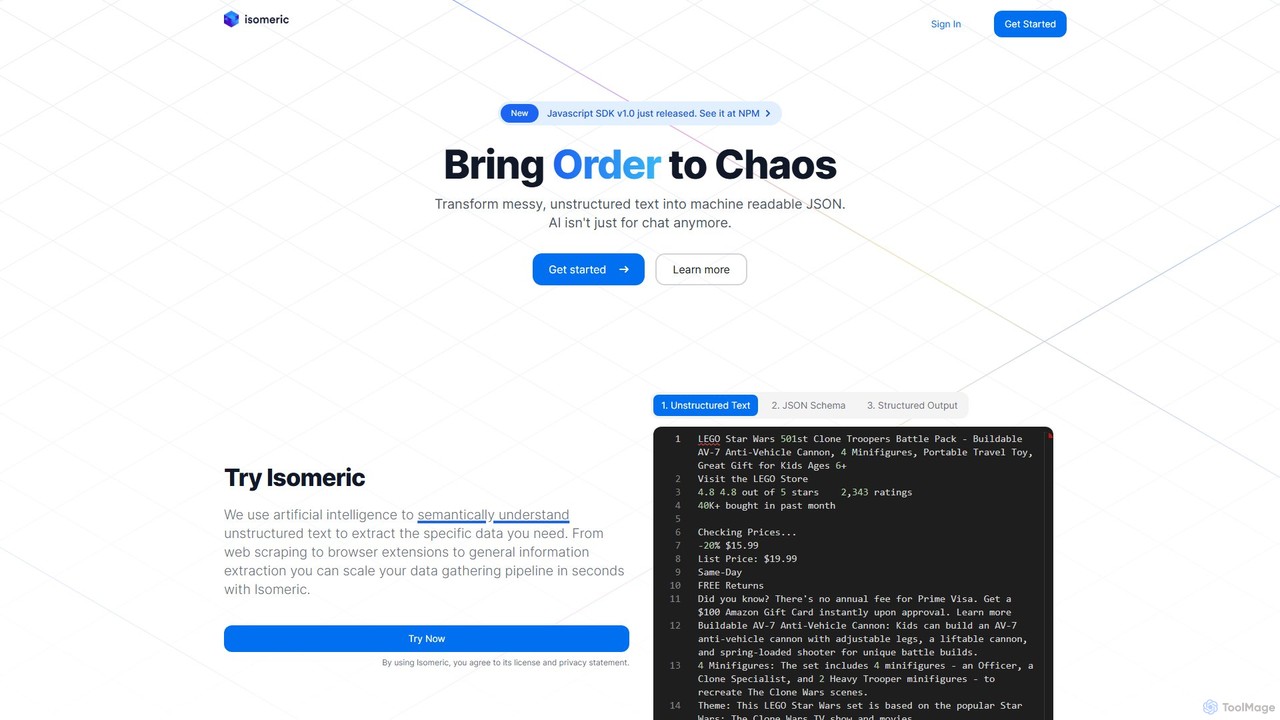
Isomeric
Isomeric is an AI-powered API that transforms messy, unstructured text from any source into clean, structured JSON data. By defining a simple JSON schema, you can automatically extract specific information from websites, legal documents, customer support transcripts, and more, streamlining data pipelines and automation.
Data Extraction
Textraction
Textraction is a powerful AI-powered API that transforms unstructured text into structured data. By simply describing the information you need in natural language, you can extract any entity from documents, emails, or web content. With seamless API and Zapier integration, it automates data extraction, converting messy text into clean, table-ready JSON format, supporting multiple languages and endless custom use cases.
Data Extraction
Curlent
Curlent is an AI-powered web scraping and data extraction platform that automates the collection of structured data from any website. It intelligently handles dynamic content, anti-bot measures, and complex layouts, providing clean, ready-to-use data via a powerful API.
Scraping
extractify
Extractify is an AI-powered platform for automated data extraction from websites, PDFs, and other documents. It intelligently captures and structures information, eliminating manual data entry and streamlining workflows for businesses and developers.
Data Analysis
Apify
Apify is a full-stack web scraping and automation platform that enables developers to build, deploy, and publish data extraction tools, known as 'Actors'. It offers a vast marketplace of pre-built scrapers for popular websites like Google Maps, Instagram, and TikTok, alongside a robust cloud infrastructure for creating custom solutions. With support for Python and JavaScript, open-source libraries, and seamless integrations, Apify simplifies collecting web data at any scale.
Data Collection
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
Firecrawl
Firecrawl is an open-source, developer-first API that turns any website into clean, LLM-ready data. It handles all the complexities of web scraping, including JavaScript rendering, proxy rotation, and rate limits, allowing you to power AI applications, agents, and RAG systems with reliable web content. It offers scraping, crawling, and search functionalities through a simple API.
Data Collection
Diffbot Comments (0)
Sign in to comment.
Sign inNo comments yet.