
Firecrawl Overview
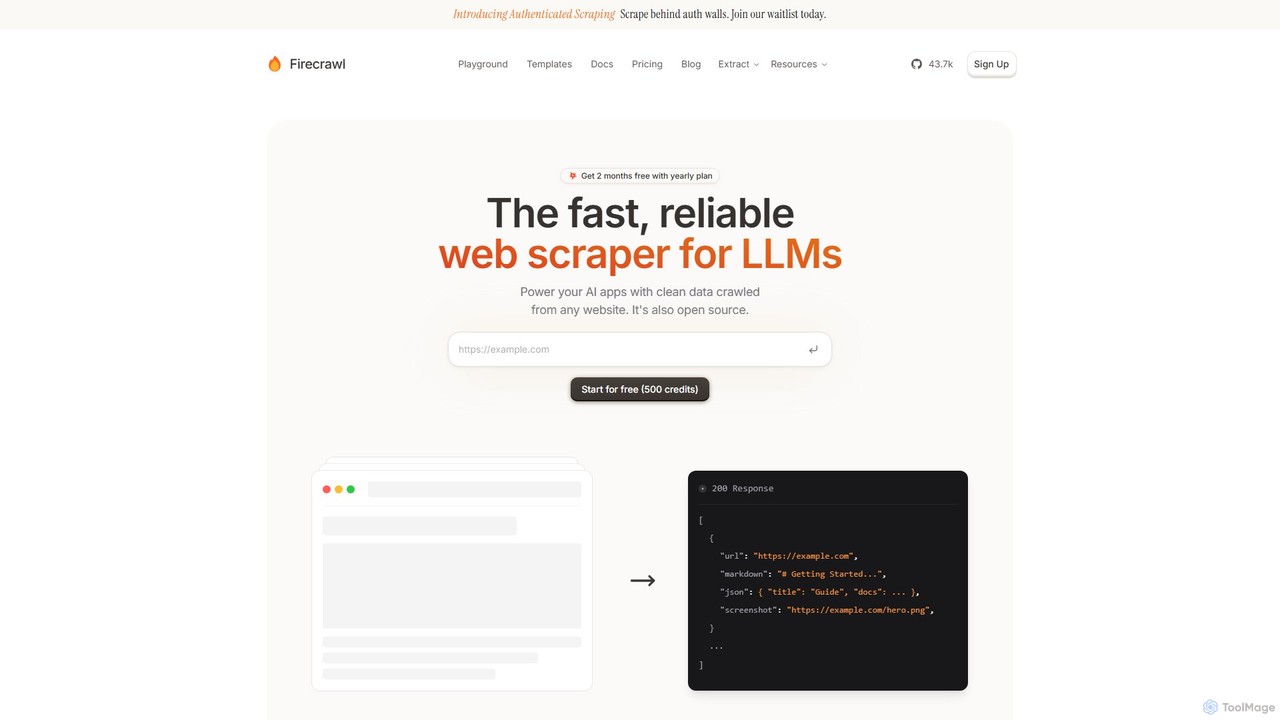
Firecrawl is a powerful, developer-centric platform designed to simplify the process of web data extraction for AI applications. It acts as an all-in-one API that can scrape, crawl, and search websites, transforming unstructured web content into clean, structured, and LLM-ready data formats like Markdown and JSON. As an open-source tool, it fosters transparency and community collaboration, while its hosted version provides robust, scalable infrastructure for production needs.
The core mission of Firecrawl is to eliminate the traditional complexities of web scraping. It automatically manages rotating proxies, handles JavaScript-heavy single-page applications (SPAs), bypasses blockers, and intelligently manages rate limits. This allows developers and AI engineers to focus on building their applications rather than managing a complex scraping infrastructure. Firecrawl is trusted by top companies and integrates seamlessly with popular AI frameworks and workflows.
How to use Firecrawl
Using Firecrawl is straightforward and designed for quick integration. Here's a typical workflow:
- Get an API Key: Sign up on the Firecrawl website to get a free API key. The free plan includes 500 credits to get started.
- Install the SDK: Firecrawl provides easy-to-use SDKs for popular languages. For example, in Node.js, you can install it via npm:
npm install @mendable/firecrawl-js. Python and Rust SDKs are also available. - Choose an Endpoint: Firecrawl offers several API endpoints for different tasks:
/scrape: To get the content of a single URL./crawl: To recursively crawl all accessible pages of a website./search: To perform a web search and get the full content of the results./extract: To pull structured data from a page using an AI-powered prompt.
- Make an API Call: Use the SDK or make a direct HTTP request to the desired endpoint. For instance, to scrape a URL:
await app.scrapeUrl('example.com'); - Process the Output: The API returns a clean JSON response containing the data in your specified format (e.g., Markdown), along with metadata and an optional screenshot.
- Integrate and Scale: Integrate the data into your AI application, such as a RAG pipeline, an AI agent, or a data enrichment workflow. You can easily scale your usage with their flexible pricing plans. The platform also features a Playground for testing API calls without writing any code.
Core Features of Firecrawl
- Comprehensive Scraping & Crawling: Scrapes single pages or crawls entire websites, even those without a sitemap.
- LLM-Ready Data: Converts messy HTML into clean Markdown, significantly reducing token counts and improving data quality for LLMs. It can also output structured JSON.
- Integrated Search API: A single API call to search the web and scrape the content of each result, perfect for AI agents and research tools.
- Zero Configuration Infrastructure: Automatically handles rotating proxies, browser management, rate limiting, and JavaScript rendering, so you don't have to.
- Authenticated Scraping: A new feature (currently on waitlist) to scrape content that is behind login walls.
- AI-Powered Extraction (`/extract`): Uses a simple prompt to extract structured data from web pages, turning websites into APIs.
- Media Parsing: Capable of parsing and extracting content from web-hosted files like PDFs and DOCX.
- Developer-First & Open Source: Provides SDKs for Node.js, Python, and Rust, extensive documentation, and a transparent, community-driven open-source repository.
Use Cases for Firecrawl
Firecrawl is versatile and powers a wide range of applications:
- AI Chatbots & Assistants: Companies like Zapier and Botpress use Firecrawl to feed their AI assistants with real-time, accurate web content for Retrieval-Augmented Generation (RAG).
- Deep Research & Analysis: AI agents can use the Search and Crawl APIs to conduct comprehensive research on any topic, gather market intelligence, or monitor competitors.
- Lead Enrichment & Sales Automation: Enhance sales data by automatically scraping company websites for up-to-date information, contacts, and business details.
- AI Platform Development: Enable customers of your platform to build their own AI applications with web data, as seen with Stack AI and Gamma.
- Website & Content Monitoring: Track changes on any website, get visual diffs, and receive AI-powered analysis of the updates.
- Building Custom Tools: Developers have built various tools, including job-matching apps, price monitoring systems, and startup idea validators using Firecrawl's data extraction capabilities.
Advantages of Firecrawl
- Reliability and Scalability: Built to handle large-scale data extraction projects, processing hundreds of thousands of requests per day with high reliability.
- Speed and Efficiency: Benchmarked to be significantly faster than many alternatives, providing quick access to web data.
- Cost-Effectiveness: By providing clean Markdown, it can save up to 2/3 of LLM token costs, allowing the use of more economical models without sacrificing quality.
- Simplicity: A single, unified API simplifies the development process, replacing the need for complex, multi-tool scraping setups.
- Seamless Integrations: Fully integrated with major tools and frameworks like LangChain, LangFlow, n8n, CrewAI, and more, fitting easily into existing workflows.
Pricing and Plans
Firecrawl offers a flexible, freemium pricing model designed to scale with your needs:
- Free Plan: $0 for a one-time grant of 500 credits. Perfect for testing and small projects. No credit card required.
- Hobby Plan: $19/month (or $16/month billed yearly) for 3,000 credits per month.
- Standard Plan: $99/month (or $83/month billed yearly) for 100,000 credits per month. This is their most popular plan.
- Growth Plan: $399/month (or $333/month billed yearly) for 500,000 credits per month, with priority support.
- Enterprise Plan: Custom pricing for unlimited credits, custom rate limits, SLAs, and advanced security features.
Credits System: Credits are consumed per API call. For example, a standard /scrape or /crawl call costs 1 credit per page. The /search endpoint costs 1 credit per result. Add-ons like Credit Packs and Auto Recharge are available for paid plans.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 675.7K
- 2026-1: 892.8K
- 2026-2: 902.3K
- 2026-3: 1.3M
- 2026-4: 1.5M
- 2026-5: 1.5M
Geography
Top 5 countries / regions
- 🇺🇸United States52.4%
- 🇮🇳India20.0%
- 🇨🇳China12.6%
- 🇩🇪Germany8.2%
- 🇧🇷Brazil6.7%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 87.0% |
Referral | 10.3% |
Email | 2.7% |
Top keywords
| Keyword | Cost per click |
|---|---|
| apify | $0.89 |
| fire crawl | $4.05 |
| firecrawl | $2.34 |
| firecrawl api | $7.39 |
| firecrawl mcp | $3.93 |
Firecrawl Videos on YouTube
Vashishtha Kapoor

Kenil Barochia | AI & TECH


Grayson Ho | AI Builders Lab


Firecrawl Alternatives
NoCaptcha AI
NoCaptcha AI is an AI-powered CAPTCHA solving service that helps developers and businesses automate CAPTCHA bypass. It offers a fast, reliable, and scalable API solution to handle various CAPTCHA types, including reCAPTCHA, Geetest, and OCR, enhancing RPA efficiency and unlocking web access.
Web Scraping
NextCaptcha
NextCaptcha is an AI-powered CAPTCHA solving service designed for developers and businesses. It offers a fast, stable, and affordable solution to bypass various CAPTCHAs, including Google's reCAPTCHA V2, V3, and Enterprise, with a 99% success rate. The service provides a simple API for seamless integration, supporting high-concurrency tasks for web scraping, data extraction, and automation.
Web Scraping
Smithery
Smithery is a registry and protocol for AI agents, providing a gateway to thousands of community-built skills and extensions. It enables developers to easily integrate external tools like web browsers, databases, and APIs into their AI applications, enhancing their capabilities and context awareness.
Database
Browserbase
Browserbase provides a scalable cloud infrastructure for running and managing headless browsers. It's designed for developers to power AI agents, automate complex web workflows, and perform large-scale data scraping without managing the underlying infrastructure.
Web Scraping
supermemory
supermemory is a memory API and infrastructure for the AI era, designed for developers to build LLMs with long-term, persistent memory. It overcomes the finite context window limitation, enabling the creation of intelligent, context-aware AI agents, chatbots, and applications that remember past interactions and information across various platforms.
LlmFirecrawl Categories
Firecrawl Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Langflow
Langflow is an open-source, visual UI for building and deploying AI applications. It features a drag-and-drop interface to chain LLMs, agents, and tools, enabling rapid prototyping and deployment of complex workflows like RAG and multi-agent systems. It supports extensive integrations and offers both self-hosted and cloud options.
Low Code No Code
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
ScrapeGraphAI
ScrapeGraphAI is an AI-powered web scraping API that transforms unstructured websites into clean, structured JSON data using simple natural language prompts. Designed for developers, AI agents, and automated workflows, it simplifies data extraction without complex code.
Analytics
UseScraper
UseScraper is a powerful web crawler and scraper API designed for developers and AI applications. It efficiently extracts data from any website, featuring full JavaScript rendering, auto-scaling infrastructure, and clean output formats like Markdown, ideal for feeding data into LLMs like ChatGPT.
Data Extraction
Skrape
Skrape is an LLM-powered web scraping API designed to transform any website into clean, structured, and LLM-ready data. It simplifies data extraction by converting web pages into structured JSON or clean markdown, making it ideal for AI training, RAG systems, and data analysis. With features like dynamic content handling and smart crawling, Skrape provides a reliable solution for developers and businesses to automate their data collection pipelines.
ScrapingSmithery
Smithery is a registry and protocol for AI agents, providing a gateway to thousands of community-built skills and extensions. It enables developers to easily integrate external tools like web browsers, databases, and APIs into their AI applications, enhancing their capabilities and context awareness.
DatabaseBrowserbase
Browserbase provides a scalable cloud infrastructure for running and managing headless browsers. It's designed for developers to power AI agents, automate complex web workflows, and perform large-scale data scraping without managing the underlying infrastructure.
Web Scrapingsupermemory
supermemory is a memory API and infrastructure for the AI era, designed for developers to build LLMs with long-term, persistent memory. It overcomes the finite context window limitation, enabling the creation of intelligent, context-aware AI agents, chatbots, and applications that remember past interactions and information across various platforms.
Llm
Hyperbrowser
Hyperbrowser is a Browser-as-a-Service platform designed for AI agents and developers. It provides scalable, lightning-fast cloud browsers to automate web tasks, extract data, and enable AI-driven web interactions. With features like stealth browsing, automatic captcha solving, and developer-friendly APIs, it empowers complex workflows without limits.
Web Scraping
Crawlbase
Crawlbase is an AI-powered web scraping and crawling platform designed for developers and businesses. It simplifies data extraction by handling proxies, CAPTCHAs, and anti-bot systems, allowing you to anonymously crawl any website and retrieve clean, structured data at scale. It offers a suite of tools including a Crawling API, Smart Proxy, and Cloud Storage.
Data Collection
Apify
Apify is a full-stack web scraping and automation platform that enables developers to build, deploy, and publish data extraction tools, known as 'Actors'. It offers a vast marketplace of pre-built scrapers for popular websites like Google Maps, Instagram, and TikTok, alongside a robust cloud infrastructure for creating custom solutions. With support for Python and JavaScript, open-source libraries, and seamless integrations, Apify simplifies collecting web data at any scale.
Data Collection
Mastra
Mastra is an open-source TypeScript framework designed for developers to build, deploy, and manage sophisticated AI agents and complex workflows. It provides a developer-friendly SDK with features like persistent memory, tool calling, Retrieval-Augmented Generation (RAG), and deterministic workflow graphs. Built by the team behind Gatsby, Mastra simplifies creating production-ready AI applications within the JavaScript ecosystem.
Agent Builder
phidata
phidata is an open-source Python framework for building autonomous AI Assistants. It simplifies the integration of LLMs with memory, knowledge bases, and external tools, enabling developers to create powerful, stateful AI applications with ease.
Frameworks
Skyvern
Skyvern is an AI-powered browser automation platform that uses computer vision and natural language to automate complex web workflows. It can handle data extraction, form submissions, invoice retrieval, and more on any website, adapting dynamically to changes without traditional scripting.
Api
Linkup
Linkup is an advanced AI-powered search API designed to provide AI applications, agents, and LLMs with accurate, verifiable, and real-time data from trusted web sources. It enhances AI factuality and performance for various business and research use cases.
Sales
Firecrawl Comments (0)
Sign in to comment.
Sign inNo comments yet.