ToolMage
Sign in

AI TOOL COMPARISON

instantapi vs Webcrawlerapi

What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.

Jump to key differences

Product overview

instantapi Product overview

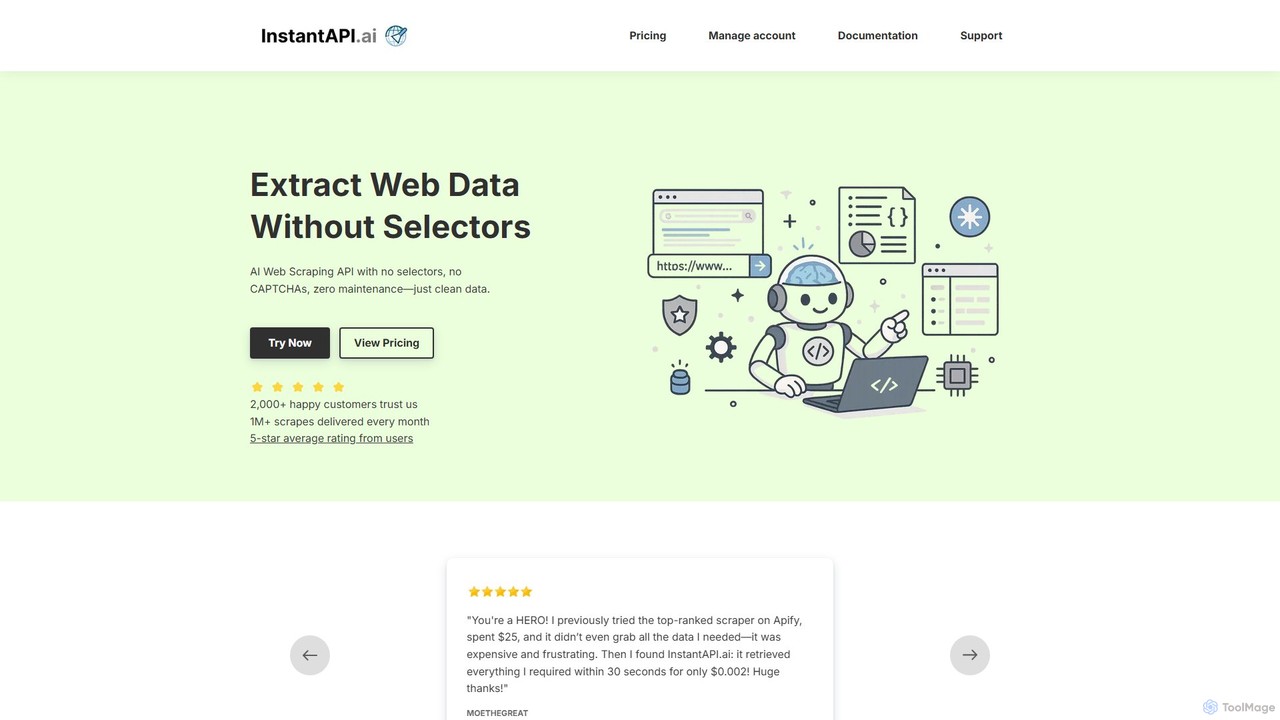
instantapi is an AI-powered web scraping API designed for simplicity and speed. It allows users to extract structured data from any website with a single API call, eliminating the need for complex coding or manual setup. Ideal for developers, data analysts, and businesses who need fast, affordable, and reliable data extraction without the hassle of traditional web scrapers.

Preview

Webcrawlerapi Product overview

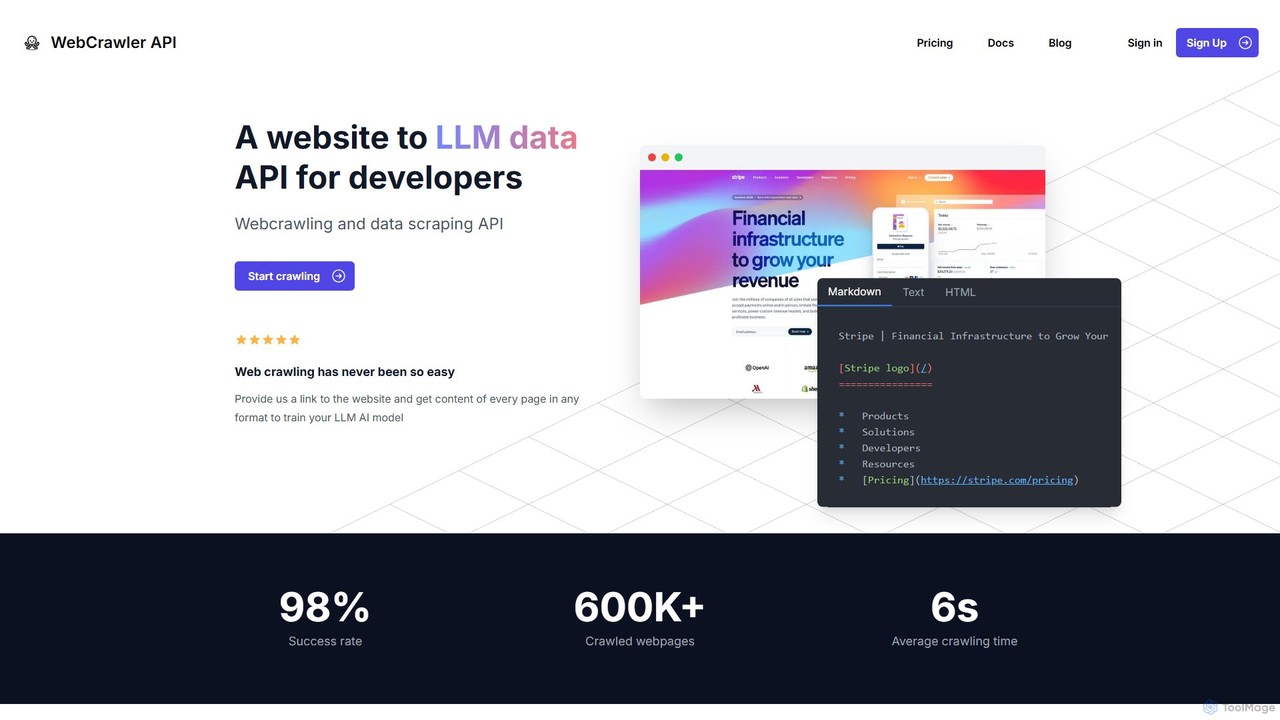
Webcrawlerapi is a powerful API for developers to effortlessly crawl websites and extract clean data. It simplifies web scraping by handling JavaScript rendering, anti-bot measures, and data parsing. Ideal for gathering structured content like Markdown or text to train LLM AI models or for Retrieval-Augmented Generation (RAG) systems, it offers a high success rate and a simple, pay-as-you-go pricing model.

Preview

Quick facts

Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.

instantapi VS Webcrawlerapi — Quick facts
Quick factsinstantapiWebcrawlerapi
Pricing modelFreemiumFreemium
Product typeWebWeb
Primary focusData ExtractionData Extraction
Audience and rolesNo data availableNo data available
CategoriesData Extraction · Api · Lead Generation · AutomationData Extraction · Api · Automation
AddedAug 14, 2025Aug 2, 2025
UpdatedNov 19, 2026Nov 19, 2026

Features, usage and use cases

Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.

instantapi

instantapi is a revolutionary AI-driven web scraping service designed for individuals and businesses who just want data, without the complexity. Frustrated with expensive, slow, and unreliable scrapers? instantapi offers a streamlined solution. By leveraging advanced artificial intelligence, it can understand the structure of a webpage and extract the desired information with a simple API request. This eliminates the need for writing and maintaining custom parsers, dealing with IP blocks, or solving CAPTCHAs, allowing you to focus on utilizing the data, not acquiring it.

The platform is built on a philosophy of simplicity, speed, and affordability. As highlighted by numerous users, instantapi stands out from competitors by being incredibly intuitive and cost-effective. It can perform complex data extraction tasks in seconds for a fraction of the cost of other services, making it a powerful tool for projects of any scale, from populating a small directory site to conducting large-scale market research.

How to use instantapi

Using instantapi is designed to be straightforward, even for those with minimal technical experience. The process typically involves these simple steps:

  1. Sign Up & Get API Key: Create an account on the instantapi website to access your personal dashboard and receive a unique API key.
  2. Formulate Your Request: Make a simple API call using your preferred programming language (like Python, JavaScript) or a tool like cURL. The request typically includes the target URL you want to scrape.
  3. Let AI Do the Work: Unlike traditional scrapers, you don't need to specify CSS selectors or XPath. The AI intelligently analyzes the webpage's structure to identify and extract key data points automatically.
  4. Receive Structured Data: The API processes the page, handles any anti-scraping measures in the background, and returns the extracted information in a clean, structured JSON format, ready for immediate use in your application, database, or analysis tool.

Core Features of instantapi

  • AI-Powered Data Extraction: The core of the service. The AI automatically identifies and extracts relevant data fields, such as product names, prices, descriptions, reviews, and contact information, without manual configuration.
  • Simple API Interface: A clean and easy-to-use API that requires only a target URL to start scraping.
  • Handles Dynamic Websites: Capable of scraping modern websites that rely heavily on JavaScript to load content, ensuring comprehensive data capture.
  • Built-in Proxy Rotation & CAPTCHA Solving: Automatically manages proxies and bypasses CAPTCHAs to ensure high success rates and prevent your IP from being blocked.
  • Structured JSON Output: Delivers clean, well-organized data in JSON format, making it easy to integrate into any workflow or application.
  • High Speed and Scalability: Engineered for performance, allowing you to scrape single pages in seconds or scale up to thousands of pages efficiently.

Use Cases for instantapi

The versatility of instantapi makes it suitable for a wide range of applications:

  • Market Research: Aggregate competitor pricing, product features, and customer reviews to gain a competitive edge.
  • Lead Generation: Extract contact details from online directories, professional networks, and corporate websites to build sales pipelines.
  • E-commerce: Monitor product prices, stock availability, and new arrivals across multiple e-commerce platforms.
  • Content Aggregation: Automatically populate directory websites, news aggregators, or job boards with fresh, relevant content.
  • Financial Data Analysis: Gather data from financial news sites, stock market portals, or real estate listings for analysis and modeling.

Advantages of instantapi

Based on user feedback and its design, instantapi offers significant advantages:

  • Unmatched Simplicity: Its intuitive nature allows users to get started immediately without a steep learning curve.
  • Extreme Cost-Effectiveness: A pay-as-you-go model with very low per-request costs makes it accessible for both small projects and large-scale operations.
  • Exceptional Speed: Delivers data in seconds, dramatically accelerating data collection workflows.
  • High Reliability: Successfully extracts complete data where other, more complex tools often fail.
  • Responsive Developer Support: Users consistently praise the fast, patient, and helpful support provided by the development team, often via Discord.

Pricing and Plans

instantapi operates on a highly competitive and transparent pricing model, primarily pay-as-you-go. This ensures you only pay for what you use, making it incredibly budget-friendly.

  • Free Trial/Credits: New users typically receive free credits to test the API's full capabilities without any commitment.
  • Pay-As-You-Go: The main pricing structure is based on a low cost per successful API call. As mentioned by users, a single scrape can cost as little as a fraction of a cent (e.g., $0.002), offering massive savings compared to competitors.
  • Volume Discounts: While specific plans are not detailed, services like this often offer tiered pricing or bulk credit purchases that provide lower per-call rates for high-volume users.

This flexible model makes instantapi an ideal choice for startups, developers, and businesses looking for a powerful scraping solution without the burden of fixed monthly subscriptions.

Webcrawlerapi

Webcrawlerapi is a specialized API designed to streamline the process of web crawling and data extraction for developers. In an era where data is crucial for training large language models (LLMs) and powering AI applications, traditional web scraping presents significant challenges. These include handling dynamic JavaScript-rendered content, bypassing sophisticated anti-bot systems, managing proxies, and cleaning messy HTML into usable formats. Webcrawlerapi abstracts away all these complexities, providing a simple yet powerful interface to turn any website into a structured data source.

With a reported 98% success rate and an average crawling time of just 6 seconds, the service is built for efficiency and reliability. It allows developers to focus on their core application logic instead of getting bogged down in the intricacies of building and maintaining a scalable crawling infrastructure. By providing a link, developers can receive clean, ready-to-use content in formats like Markdown, text, or raw HTML, making it perfect for feeding into AI model training pipelines or knowledge bases for RAG systems.

How to use Webcrawlerapi

Integrating Webcrawlerapi into your project is designed to be straightforward. The process typically involves just a few lines of code. First, you need to sign up on the Webcrawlerapi website to obtain your unique API access key. Then, you can use one of their provided client libraries for popular programming languages.

For example, in a NodeJS environment, you would start by installing the client library via npm: npm i webcrawlerapi-js. Then, in your code, you import the library, create a new client instance with your API key, and call the `crawl` method. This method takes parameters such as the target `url`, the desired `scrape_type` (e.g., 'markdown'), and optional limits like `items_limit`. The API then handles the entire crawling process in the background and returns a structured JSON response with the extracted data. Similar simple integration patterns are available for Python, PHP, and .NET, making it accessible to a wide range of developers.

Core Features of Webcrawlerapi

  • Automated Link Handling: The API intelligently discovers and manages all internal links on a website, ensuring comprehensive crawling while automatically handling duplicates and cleaning URLs.
  • Advanced JavaScript Rendering: It effectively renders dynamic, client-side content using a stable and robust system, overcoming the instability and memory issues often associated with tools like Puppeteer or Playwright.
  • Robust Anti-Bot Evasion: Webcrawlerapi comes with built-in mechanisms to deal with CAPTCHAs, IP blocks, rate limits, and other common anti-bot defenses, ensuring a high success rate.
  • Automatic Data Cleaning: It includes powerful parsing rules to convert raw, complex HTML into clean, structured formats like Markdown or plain text, saving developers significant post-processing time.
  • Scalable Infrastructure: The service manages a distributed infrastructure of crawlers and proxies, allowing you to scale your data extraction efforts from a few pages to millions without worrying about the underlying hardware or network management.
  • Developer-Friendly API & SDKs: Offers a simple API and official client libraries for major languages like NodeJS, Python, PHP, and .NET, complete with clear documentation.

Use Cases for Webcrawlerapi

Webcrawlerapi is versatile and can be applied to a variety of data-intensive tasks. Its primary use cases revolve around AI and data analysis.

  • LLM Training Data Collection: Systematically crawl websites, blogs, and forums to gather vast amounts of high-quality, domain-specific text data for training or fine-tuning custom large language models.
  • Retrieval-Augmented Generation (RAG): Build and maintain up-to-date knowledge bases for RAG systems. Crawl product documentation, help centers, or news sites to provide LLMs with accurate, real-time information to answer user queries.
  • Market Research and Competitive Analysis: Automatically extract product details, pricing information, customer reviews, and marketing content from competitor websites to gain strategic insights.
  • Content Aggregation: Power news aggregators, job boards, or real estate listing sites by regularly crawling multiple sources and consolidating the data into a unified platform.

Advantages of Webcrawlerapi

The main advantage of Webcrawlerapi is its simplicity and efficiency. It allows development teams to offload the entire web crawling infrastructure and maintenance burden. This means faster time-to-market for data-driven products. The high success rate (98%) and robust anti-bot features ensure data pipelines are reliable. Furthermore, its transparent, pay-as-you-go pricing model is highly cost-effective, as you only pay for successful requests, eliminating the risk and overhead associated with subscriptions or building an in-house solution.

Pricing and Plans

Webcrawlerapi employs a straightforward and transparent 'pay-for-usage' pricing model, completely avoiding subscriptions and hidden fees. Costs are calculated based on the number of pages you successfully crawl each month. The service includes unlimited crawl jobs, an unlimited and automatically managed proxy network, and email support in its pricing. For a clear cost estimation, the website provides a calculator. As an example, crawling 10,000 pages in a month would cost approximately $20. This model is ideal for projects of all sizes, from small-scale experiments to large-scale data operations, as costs scale directly with usage. The platform also allows users to try the service before making a purchase, likely through a free credit allocation for new accounts.

Positioning

Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.

Categories

Shared
Data ExtractionApiAutomation
Only instantapi
Lead Generation
Only Webcrawlerapi
No listed items

Tags

Shared
APIautomationdata extraction
Only instantapi
data miningdeveloper toolslead generationmarket researchno-codeweb scraping
Only Webcrawlerapi
data collectiondata scrapingdeveloper toolJavaScript renderingLLM trainingRAGweb crawling

Audience and roles

Shared
No listed items
Only instantapi
No listed items
Only Webcrawlerapi
No listed items

Traffic comparison

Traffic is shown on the same scale so differences in market visibility are not visually understated.

How to interpret the traffic data

Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.

instantapi

No data available

Webcrawlerapi monthly traffic:

Latest traffic · 2026-05

Monthly visits
5.4K
Avg. visit duration
0:46
Pages per visit
1.95
Bounce rate
41.65%
Data updated 2026-06-15

Monthly traffic trend

  • 2025-09: 5.1K
  • 2026-01: 4.5K
  • 2026-02: 4K
  • 2026-03: 4.3K
  • 2026-04: 5.6K
  • 2026-05: 5.4K

Top regions

Top 5 countries/regions
Country/regionPercentageEstimated visits
🇺🇸United States49.13%2.7K
🇩🇪Germany20.9%1.1K
🇮🇳India14.85%809
🇻🇳Vietnam12.23%666
🇦🇺Australia2.89%157

Search keywords

better to save as an html or md file packing more informationdata scraping law casesfirecrawl alternativesllms txt generator onlinesubmit website to chatgpt

Community signals

Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.

instantapi

Rating
No data available
Comments
0
Favorites
191
Likes
201

Webcrawlerapi

Rating
No data available
Comments
0
Favorites
182
Likes
179

instantapi vs Webcrawlerapi · Comparison FAQ

What do instantapi and Webcrawlerapi have in common?
Both tools are listed under Data Extraction、Api、Automation. These categories indicate overlapping use cases; compare their detailed descriptions for workflows, capabilities and limitations.
Are instantapi and Webcrawlerapi free?
Listed pricing models: instantapi — Freemium; Webcrawlerapi — Freemium. Missing pricing is not proof of a free plan, and freemium does not mean every feature is free. Check official sites for current plans, limits and trials.
How should I choose between instantapi and Webcrawlerapi?
The primary listed category is Data Extraction for instantapi, and Data Extraction for Webcrawlerapi. Compare features, steps and use cases, then verify pricing, data permissions and deployment needs. This page does not include hands-on testing and does not declare a winner from traffic or tags.

Sources and comparison methodology

This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.

  • Feature and plan descriptions reflect information in the listings, not real-time guarantees. Verify pricing, quotas, availability and privacy terms on the official sites.
  • Traffic uses the reporting months shown. Missing statistics do not mean zero visits, and different periods do not establish growth or superiority. Regional and source visit counts are estimates based on shares.
  • Different tags indicate differences in the listings, not proof that the other product lacks a capability. Ratings, favorites and visits are not used to declare a winner.

Related comparisons