UseScraper
Data Extraction
AI TOOL COMPARISON
What is the difference, and which fits your workflow? Compare features, usage, pricing models and traffic side by side.
Data Extraction
Data Extraction
UseScraper is a powerful web crawler and scraper API designed for developers and AI applications. It efficiently extracts data from any website, featuring full JavaScript rendering, auto-scaling infrastructure, and clean output formats like Markdown, ideal for feeding data into LLMs like ChatGPT.
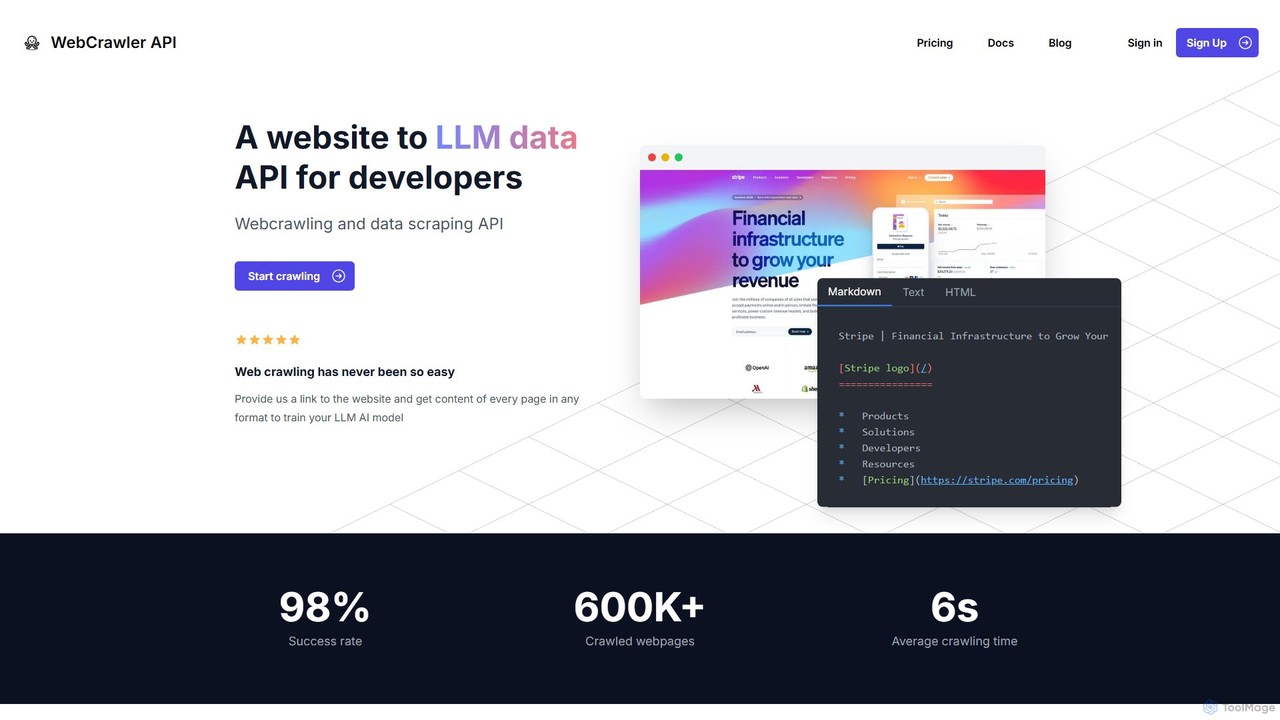
Webcrawlerapi is a powerful API for developers to effortlessly crawl websites and extract clean data. It simplifies web scraping by handling JavaScript rendering, anti-bot measures, and data parsing. Ideal for gathering structured content like Markdown or text to train LLM AI models or for Retrieval-Augmented Generation (RAG) systems, it offers a high success rate and a simple, pay-as-you-go pricing model.
Compare product focus, pricing models and audiences. Highlighted rows indicate different listed information; unknown pricing does not mean free.
| Quick facts | UseScraper | Webcrawlerapi |
|---|---|---|
| Pricing model | Freemium | Freemium |
| Product type | Web | Web |
| Primary focus | Data Extraction | Data Extraction |
| Audience and roles | No data available | No data available |
| Categories | Data Extraction · Api · Automation | Data Extraction · Api · Automation |
| Added | Aug 5, 2025 | Aug 2, 2025 |
| Updated | Nov 19, 2026 | Nov 19, 2026 |
Explore the listed product descriptions, features and workflows. Taxonomy labels alone are not feature evaluations.
UseScraper is a robust and scalable web scraping and crawling service provided through a simple yet powerful API. It is engineered from the ground up for speed and reliability, enabling users to extract data from any webpage in seconds or crawl entire websites in minutes. This tool is particularly valuable for developers, data scientists, and businesses who need to gather web data for market research, lead generation, price monitoring, or for training AI models.
The platform is designed to handle the complexities of the modern web. It utilizes a real Chrome browser for full JavaScript rendering, ensuring that content on dynamic, single-page applications (SPAs) is accurately captured. This capability makes it superior to many traditional scrapers that only fetch static HTML. The output can be delivered in several formats, including raw HTML, plain text, and, most notably, clean, well-structured Markdown, which is the ideal format for processing by AI systems and Large Language Models (LLMs).
Using UseScraper is straightforward for developers of all skill levels. The process involves a few simple steps:
UseScraper is versatile and can be applied to a wide range of data extraction tasks:
UseScraper stands out due to its focus on performance, modern web compatibility, and developer experience. Its key advantages include its ability to handle JavaScript-heavy sites effortlessly, the provision of clean Markdown output tailored for AI, and its scalable, high-speed architecture. The flexible pricing model, including a generous free tier, makes it accessible for projects of all sizes, from small scripts to large-scale enterprise data operations.
UseScraper offers a transparent and scalable pricing structure:
New users receive $25 in free credits upon signing up, providing a substantial starting point for testing and development.
Webcrawlerapi is a specialized API designed to streamline the process of web crawling and data extraction for developers. In an era where data is crucial for training large language models (LLMs) and powering AI applications, traditional web scraping presents significant challenges. These include handling dynamic JavaScript-rendered content, bypassing sophisticated anti-bot systems, managing proxies, and cleaning messy HTML into usable formats. Webcrawlerapi abstracts away all these complexities, providing a simple yet powerful interface to turn any website into a structured data source.
With a reported 98% success rate and an average crawling time of just 6 seconds, the service is built for efficiency and reliability. It allows developers to focus on their core application logic instead of getting bogged down in the intricacies of building and maintaining a scalable crawling infrastructure. By providing a link, developers can receive clean, ready-to-use content in formats like Markdown, text, or raw HTML, making it perfect for feeding into AI model training pipelines or knowledge bases for RAG systems.
Integrating Webcrawlerapi into your project is designed to be straightforward. The process typically involves just a few lines of code. First, you need to sign up on the Webcrawlerapi website to obtain your unique API access key. Then, you can use one of their provided client libraries for popular programming languages.
For example, in a NodeJS environment, you would start by installing the client library via npm: npm i webcrawlerapi-js. Then, in your code, you import the library, create a new client instance with your API key, and call the `crawl` method. This method takes parameters such as the target `url`, the desired `scrape_type` (e.g., 'markdown'), and optional limits like `items_limit`. The API then handles the entire crawling process in the background and returns a structured JSON response with the extracted data. Similar simple integration patterns are available for Python, PHP, and .NET, making it accessible to a wide range of developers.
Webcrawlerapi is versatile and can be applied to a variety of data-intensive tasks. Its primary use cases revolve around AI and data analysis.
The main advantage of Webcrawlerapi is its simplicity and efficiency. It allows development teams to offload the entire web crawling infrastructure and maintenance burden. This means faster time-to-market for data-driven products. The high success rate (98%) and robust anti-bot features ensure data pipelines are reliable. Furthermore, its transparent, pay-as-you-go pricing model is highly cost-effective, as you only pay for successful requests, eliminating the risk and overhead associated with subscriptions or building an in-house solution.
Webcrawlerapi employs a straightforward and transparent 'pay-for-usage' pricing model, completely avoiding subscriptions and hidden fees. Costs are calculated based on the number of pages you successfully crawl each month. The service includes unlimited crawl jobs, an unlimited and automatically managed proxy network, and email support in its pricing. For a clear cost estimation, the website provides a calculator. As an example, crawling 10,000 pages in a month would cost approximately $20. This model is ideal for projects of all sizes, from small-scale experiments to large-scale data operations, as costs scale directly with usage. The platform also allows users to try the service before making a purchase, likely through a free credit allocation for new accounts.
Their taxonomy shows where the products overlap and where each one has a more distinct focus. Unknown fields are shown explicitly and are never filled with assumptions.
Traffic is shown on the same scale so differences in market visibility are not visually understated.
Both charts share the same months and vertical scale. Each tool identifies its latest reporting month; missing months are left blank, not counted as zero. Regional and source visit counts are estimates calculated from the reported shares.
No data available
| Country/region | Percentage | Estimated visits |
|---|---|---|
| 🇺🇸United States | 49.13% | 2.7K |
| 🇩🇪Germany | 20.9% | 1.1K |
| 🇮🇳India | 14.85% | 809 |
| 🇻🇳Vietnam | 12.23% | 666 |
| 🇦🇺Australia | 2.89% | 157 |
Ratings, comments, favorites, and likes are community signals—not a substitute for product fit.
This page is assembled from ToolMage product listings, taxonomy, traffic statistics and on-site user feedback. It is not a hands-on test or an independent review.