

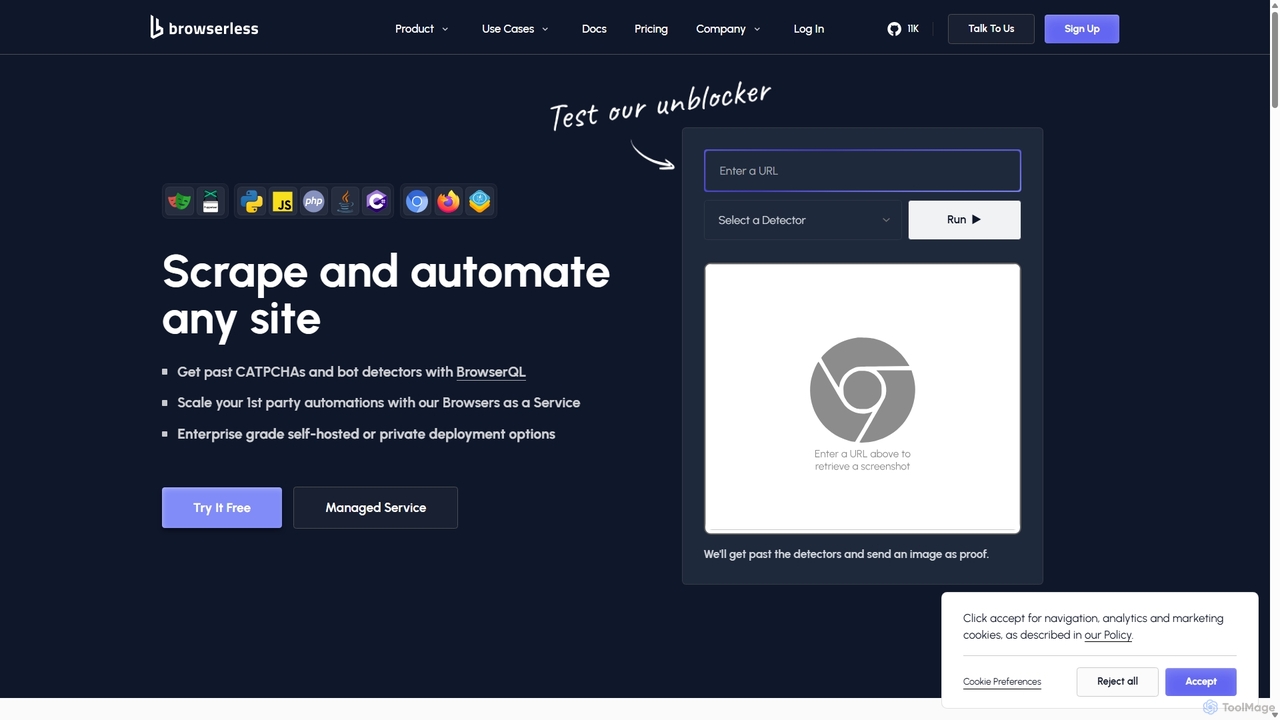
Browserless Overview
Browserless is a comprehensive cloud-based platform that provides headless browser instances for a wide range of web automation and data extraction tasks. It's built to solve the common challenges developers face when working with headless browsers at scale, such as infrastructure management, performance issues, and evading sophisticated bot detection systems. By offering a robust pool of managed browsers, Browserless allows developers and businesses to focus on their core logic rather than the complexities of deploying and maintaining browser automation systems.
The service is trusted by thousands of companies, from startups to large enterprises, for its reliability, scalability, and advanced features. It offers both managed cloud services and self-hosted enterprise solutions, providing flexibility for different security and compliance needs, including SOC 2 Type II compliance.
How to use Browserless
Browserless offers multiple ways to integrate its services into your workflow, making it accessible for various skill levels and project requirements:
- Connect with Puppeteer or Playwright: The easiest way to get started is by connecting your existing Puppeteer or Playwright scripts. Instead of launching a local browser instance, you simply change the connection method to point to a Browserless WebSocket endpoint. This requires minimal code changes and instantly scales your existing automations.
- Use REST APIs: For common tasks like generating PDFs, taking screenshots, or extracting HTML content, Browserless provides simple REST APIs. You can make a cURL request or use any HTTP client to perform these actions without writing complex browser automation scripts.
- Leverage BrowserQL: For advanced use cases, especially those involving bypassing tough bot detectors (like Cloudflare), Browserless offers BrowserQL. This is a next-generation automation language and IDE designed to leave minimal fingerprints. You can write concise queries to perform complex actions like clicking buttons, solving CAPTCHAs, and extracting structured data, all while appearing more human to detection systems.
- Hybrid Automations: Browserless supports hybrid workflows where you can stream a browser session to an iframe. This is useful for tasks that require manual intervention, such as solving a complex CAPTCHA, entering 2FA codes, or handling OAuth logins within an automated script.
Core Features of Browserless
- BrowserQL: A proprietary query language and IDE built from the ground up to bypass the most advanced bot detectors by minimizing browser fingerprints.
- Browser as a Service (BaaS): A scalable, managed pool of thousands of browsers, handling all infrastructure aspects like version updates, load balancing, and resource management.
- Bot Detection & CAPTCHA Evasion: Specialized technology to automatically solve CAPTCHAs (reCAPTCHA, hCaptcha) and get past bot-blocking services like Cloudflare.
- Puppeteer & Playwright Integration: Seamless compatibility with the two most popular browser automation libraries.
- REST APIs: Simple endpoints for common tasks such as PDF generation, screenshots, and content scraping.
- Session Management & Reconnects: The ability to keep browser sessions alive and reconnect to them, which significantly reduces proxy usage and avoids repetitive bot checks.
- Enterprise-Grade Solutions: Options for self-hosting, private cloud deployments, custom machine setups (including GPUs), SSO, dedicated support, and SOC 2 Type II compliance.
- Monitoring & Debugging: A user-friendly dashboard provides metrics on requests, worker health (CPU/memory), and a debugger to watch scripts run in real-time.
Use Cases for Browserless
Browserless is versatile and can be applied to numerous scenarios:
- Web Scraping & Data Extraction: Gathering data from dynamic, JavaScript-heavy websites, e-commerce platforms (e.g., Walmart, eBay), real estate listings (Zillow), and job boards (Indeed).
- Automated Software Testing: Running end-to-end tests for web applications at scale, integrating with frameworks like Laravel Dusk without the need to manage a complex Selenium Grid.
- AI & LLM Data Ingestion: Powering AI agents (e.g., using LangChain or CrewAI) with real-time web access to gather fresh data for training large language models or performing automated research.
- Report Generation: Automatically generating PDFs and screenshots of dashboards, analytics reports, or invoices from web applications.
- Price & Competitor Monitoring: Tracking product prices, inventory levels, and competitor strategies across various online retailers.
Advantages of Browserless
Using Browserless provides several key advantages:
- Reduced Operational Overhead: Eliminates the need for a dedicated team to build, deploy, and maintain a complex browser automation infrastructure.
- Enhanced Success Rates: Its advanced bot evasion techniques, particularly with BrowserQL, lead to higher success rates in scraping protected websites.
- Scalability on Demand: Effortlessly scales from a few concurrent sessions to thousands, handling traffic spikes without performance degradation.
- Cost Efficiency: Features like session reconnects can reduce proxy costs by up to 90%. The unit-based pricing model is predictable and cost-effective.
- Developer-Focused: Designed by developers for developers, with excellent documentation, SDKs, and responsive technical support.
Pricing and Plans
Browserless offers a flexible, unit-based pricing model to suit different needs:
- Free Plan: Includes 1,000 units per month, 1 max concurrent browser, and access to the BrowserQL editor. No credit card required.
- Prototyping Plan: Starts at $25/month (billed annually) for 20,000 units and 3 concurrent browsers. Ideal for small projects and testing.
- Starter Plan: Starts at $140/month (billed annually) for 180,000 units and 20 concurrent browsers, suitable for growing applications.
- Scale Plan: Starts at $350/month (billed annually) for 500,000 units and 50 concurrent browsers, designed for high-volume operations.
- Enterprise Plan: Custom pricing for users needing millions of units, private deployments, self-hosting, advanced features like GPU infrastructure, SSO, and a dedicated technical account manager.
A "Unit" corresponds to up to 30 seconds of browser time. Longer sessions consume additional units. Units are also used for residential proxies and successful CAPTCHA solves.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 126.9K
- 2026-1: 150.9K
- 2026-2: 150.8K
- 2026-3: 157.8K
- 2026-4: 148.9K
- 2026-5: 242.1K
Geography
Top 5 countries / regions
- 🇧🇷Brazil28.1%
- 🇺🇸United States26.6%
- 🇨🇭Switzerland23.8%
- 🇨🇦Canada11.6%
- 🇪🇸Spain10.0%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 81.8% |
Referral | 13.7% |
Email | 4.5% |
Top keywords
| Keyword | Cost per click |
|---|---|
| browserless | $3.04 |
| browserless api | $0.00 |
| browserless io | $5.97 |
| memory leak fix | $2.60 |
| playwright vs selenium | $2.37 |
Browserless Videos on YouTube

browserless
browserless


browserless


Latent Space TV (see @LatentSpacePod for Pod)
Browserless Alternatives
Scrappey
Scrappey is an advanced web scraping API designed for developers to effortlessly extract data from any website. It handles all complexities like rotating proxies, headless browsers, and bypassing anti-bot measures such as Cloudflare and CAPTCHAs. With a high success rate and a simple pay-as-you-go model, Scrappey streamlines data collection for various applications.
Data Extraction
Crawlbase
Crawlbase is an AI-powered web crawling and data scraping platform for developers and businesses. It provides a suite of tools, including a Crawling API and Smart Proxy, to anonymously extract data from any website at scale, bypassing blocks and CAPTCHAs with a high success rate. It simplifies data collection for SEO, market research, e-commerce intelligence, and training AI models.
Data Extraction
Foxscrape
FoxScrape is an AI-powered web scraping REST API for developers. It simplifies data extraction by converting any website into structured JSON data using features like AI-driven parsing from plain English, JavaScript rendering for dynamic sites, and automatic proxy rotation to prevent blocks.
Data Extraction
Apify
Apify is a full-stack web scraping and automation platform that enables developers to build, deploy, and publish data extraction tools, known as 'Actors'. It offers a vast marketplace of pre-built scrapers for popular websites like Google Maps, Instagram, and TikTok, alongside a robust cloud infrastructure for creating custom solutions. With support for Python and JavaScript, open-source libraries, and seamless integrations, Apify simplifies collecting web data at any scale.
Data Collection
FetchFox
FetchFox is an AI-powered web scraping tool that allows users to extract data from any website using simple text prompts. It eliminates the need for complex coding or CSS selectors, automatically handling anti-bot measures. Available as an API, JavaScript library, and Chrome extension, it's designed for both developers and non-technical users to automate data collection effortlessly.
Data ExtractionBrowserless Categories
Browserless Jobs
Browserless Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Scrappey
Scrappey is an advanced web scraping API designed for developers to effortlessly extract data from any website. It handles all complexities like rotating proxies, headless browsers, and bypassing anti-bot measures such as Cloudflare and CAPTCHAs. With a high success rate and a simple pay-as-you-go model, Scrappey streamlines data collection for various applications.
Data ExtractionCrawlbase
Crawlbase is an AI-powered web crawling and data scraping platform for developers and businesses. It provides a suite of tools, including a Crawling API and Smart Proxy, to anonymously extract data from any website at scale, bypassing blocks and CAPTCHAs with a high success rate. It simplifies data collection for SEO, market research, e-commerce intelligence, and training AI models.
Data Extraction
Zyte
Zyte is a comprehensive web scraping platform offering a full-stack API and data extraction services. It simplifies data acquisition by managing proxies, headless browsers, and advanced anti-blocking systems. Powered by AI, Zyte delivers reliable, structured web data at scale for businesses in e-commerce, market research, and more.
Market Intelligence
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
AutomationFoxscrape
FoxScrape is an AI-powered web scraping REST API for developers. It simplifies data extraction by converting any website into structured JSON data using features like AI-driven parsing from plain English, JavaScript rendering for dynamic sites, and automatic proxy rotation to prevent blocks.
Data Extraction
Browserman
Browserman is an advanced browser automation platform designed to empower AI assistants like Claude, ChatGPT, Gemini, and Grok to manage social media operations. It offers multi-platform and multi-account support, a robust REST API, and native Model Context Protocol (MCP) integration for seamless, scalable, and secure automation workflows.
Integration
Skyvern
Skyvern is an AI-powered browser automation platform that uses computer vision and natural language to automate complex web workflows. It can handle data extraction, form submissions, invoice retrieval, and more on any website, adapting dynamically to changes without traditional scripting.
Api
ManyPI
ManyPI is a modern data gathering platform that transforms any website into a type-safe API. It simplifies structured data extraction with built-in schema definition, data extraction, and record transformation, empowering developers and technical teams to reliably collect web data at scale.
3D
Hyperbrowser
Hyperbrowser is a Browser-as-a-Service platform designed for AI agents and developers. It provides scalable, lightning-fast cloud browsers to automate web tasks, extract data, and enable AI-driven web interactions. With features like stealth browsing, automatic captcha solving, and developer-friendly APIs, it empowers complex workflows without limits.
Web Scraping
Octoparse
Octoparse is a powerful no-code web scraping tool that allows anyone to extract data from websites without programming. It features a visual workflow designer, an AI-powered assistant for easy setup, and hundreds of pre-built templates for popular sites. With cloud-based automation, IP rotation, and CAPTCHA solving, Octoparse handles complex scraping tasks efficiently, turning web pages into structured data for lead generation, market research, and more.
Web Scraping
Crawlora
Crawlora is an AI-powered, no-code web scraping platform that enables users to effortlessly extract data from any website. Its intelligent point-and-click interface simplifies data extraction, allowing you to turn web pages into structured data (CSV, JSON) without writing a single line of code. Ideal for market research, lead generation, and price monitoring.
Data Extraction
BrowserBook
BrowserBook is an AI-powered integrated development environment (IDE) designed for building, deploying, and scaling deterministic browser automations. It simplifies complex web automation tasks, offering speed, stability, and cost savings by combining AI code generation with reliable scripted execution. Ideal for AI agents, web scraping, UI testing, and industry-specific workflows in healthcare and finance.
Ai Agent Development
Browserbase
Browserbase provides a scalable cloud infrastructure for running and managing headless browsers. It's designed for developers to power AI agents, automate complex web workflows, and perform large-scale data scraping without managing the underlying infrastructure.
Web Scraping
ScrapingBee
ScrapingBee is a powerful web scraping API that handles headless browsers and proxy rotation to prevent getting blocked. It features an innovative AI-powered extractor that lets you describe the data you need in plain English, eliminating the need for complex CSS selectors. Ideal for developers, marketers, and data analysts for tasks like price monitoring, lead generation, and SERP analysis.
Data Extraction
Rtrvr
Rtrvr is an advanced AI agent designed to automate complex web tasks using natural language. It navigates websites, extracts data, fills forms, and executes workflows, transforming tedious operations into simple conversations.
Web Automation
Browserless Comments (0)
Sign in to comment.
Sign inNo comments yet.