
Crawlbase Overview
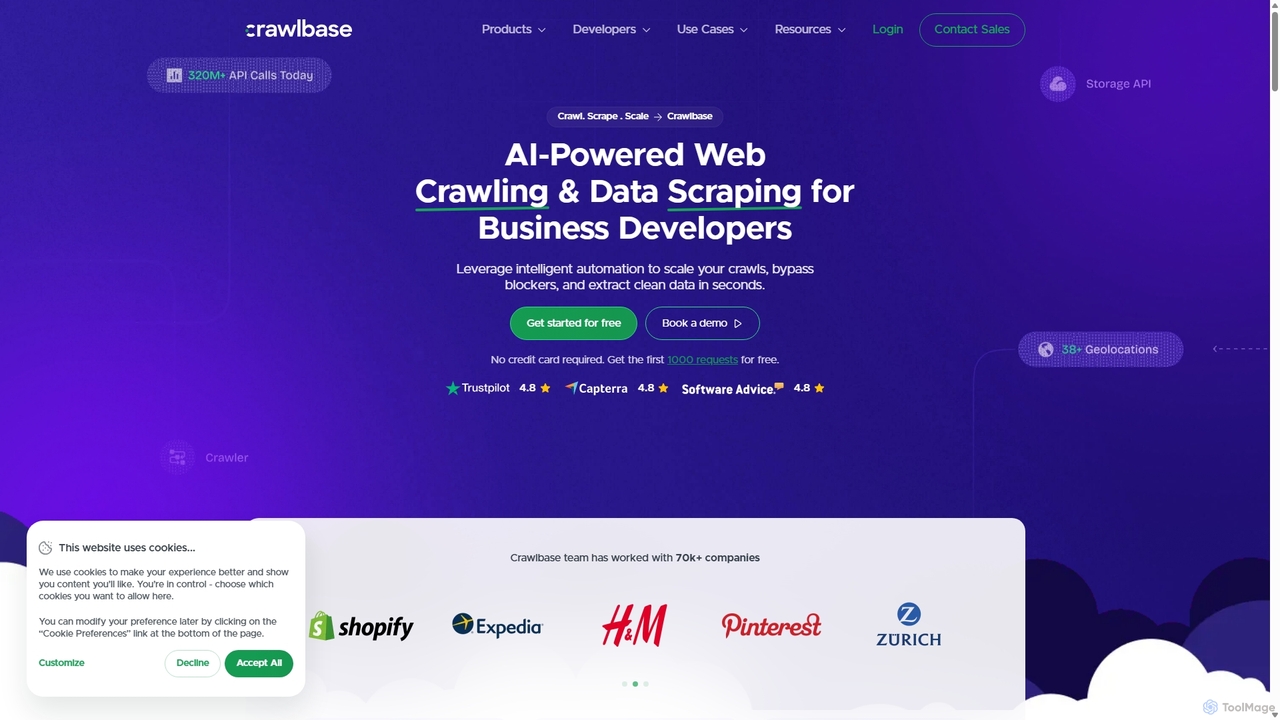
Crawlbase is a comprehensive, AI-driven platform designed to democratize access to web data. It empowers developers, data scientists, and businesses to crawl and scrape the internet at a massive scale, transforming unstructured web content into clean, structured data. By handling the complex infrastructure of proxies, browser automation, and anti-bot systems, Crawlbase allows users to focus solely on data utilization. The platform is built on a foundation of millions of rotating residential and datacenter proxies worldwide, ensuring anonymous and unrestricted access to websites like Amazon, LinkedIn, Google, and more, with a guaranteed 99.9% uptime.
How to use Crawlbase
Integrating Crawlbase into your workflow is designed to be straightforward and can be done in minutes:
- Create an Account: Sign up for a free Crawlbase account. You will receive an API token for authentication. The initial plan includes 1,000 free requests to test the service without any credit card requirement.
- Choose the Right Tool: Select the appropriate product for your needs. Use the Crawling API for real-time, synchronous data requests. For large-scale, ongoing projects, the asynchronous Crawler is more cost-effective. If you need a simple proxy gateway for your application, the Smart Proxy is the ideal choice.
- Make an API Request: Make a simple API call to the Crawlbase endpoint, passing your API token and the target URL you wish to scrape. You can include various parameters to enable JavaScript rendering, set geo-locations, or use specific data scrapers.
- Receive Data: Crawlbase processes the request, navigating through blocks, proxies, and CAPTCHAs. It then returns the full HTML content of the page or, if using a specific scraper (like the Amazon scraper), provides the data in a structured JSON format.
Core Features of Crawlbase
- Crawling API: A powerful, easy-to-use API that fetches web page content in real-time. It supports JavaScript rendering for dynamic websites and includes built-in scrapers for popular sites like Amazon, providing structured data directly.
- The Crawler: An asynchronous crawling solution designed for massive data extraction projects. It uses callbacks to deliver data to your servers, saving costs, bandwidth, and retry attempts for large volumes of URLs.
- Smart Proxy: A rotating proxy solution that provides access to millions of datacenter and residential IPs. It can be easily integrated into any application or script that requires a reliable proxy to avoid getting blocked.
- AI-Powered Anti-Blocking: Sophisticated algorithms and machine learning models that automatically handle IP blocks, browser fingerprinting, CAPTCHAs, and other anti-scraping measures, ensuring a high success rate.
- Cloud Storage: A convenient feature that allows you to move your crawled and scraped data directly to Crawlbase's secure cloud storage, simplifying your data pipeline.
- Global Geolocation: Access web content from over 30 different countries, allowing you to perform localized searches and gather region-specific data.
Use Cases for Crawlbase
Crawlbase is versatile and supports a wide range of data-driven business activities:
- E-commerce & Retail: Monitor competitor pricing, track product availability, aggregate customer reviews, and analyze product data from platforms like Amazon, eBay, and Walmart to optimize sales strategies.
- Market Research: Gather vast amounts of data for market trend analysis, sentiment analysis from social media and forums, and identifying emerging business opportunities.
- Lead Generation: Automate the process of collecting contact information and business details from professional networks like LinkedIn, online directories, and corporate websites.
- AI and Machine Learning: Provide high-quality, structured datasets for training generative AI and large language models (LLMs). The API can efficiently gather the massive volumes of text and image data required.
- SEO Monitoring: Track keyword rankings across different search engines and locations, analyze competitor SEO strategies, and perform comprehensive site audits without getting blocked.
Advantages of Crawlbase
Crawlbase offers a significant competitive edge by abstracting the complexities of web scraping. Instead of building and maintaining a costly and fragile in-house infrastructure, users benefit from a reliable, scalable, and cost-effective solution. The platform's key advantages include its massive proxy network, high success rate (over 99%), 99.9% uptime guarantee, and 24/7 expert support. Its developer-first approach ensures easy integration and robust documentation, while its commitment to compliance (GDPR & CCPA) provides peace of mind for enterprises.
Pricing and Plans
Crawlbase operates on a flexible and transparent freemium model. New users can start with a free plan that includes 1,000 free requests, allowing them to fully test the platform's capabilities without providing a credit card. After the free trial, pricing is based on a pay-as-you-go system, where costs are determined by the number of requests made and the features used (e.g., standard requests vs. JavaScript-enabled requests). For businesses with high-volume data needs, Crawlbase offers tailored Enterprise plans that come with custom pricing, dedicated account management, and premium support to meet specific project requirements.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 82.1K
- 2026-1: 74.4K
- 2026-2: 50.0K
- 2026-3: 46.3K
- 2026-4: 35.7K
- 2026-5: 32.4K
Geography
Top 5 countries / regions
- 🇩🇪Germany26.0%
- 🇷🇺Russia22.6%
- 🇻🇳Vietnam18.4%
- 🇳🇬Nigeria17.5%
- 🇺🇸United States15.6%
Top keywords
| Keyword | Cost per click |
|---|---|
| apify | $0.89 |
| crawlbase | $2.99 |
| deviantart scraper | $0.00 |
| webscraping at scale | $0.00 |
| прокси в 2026 году бесплатно | $0.00 |
Crawlbase Alternatives
Scrappey
Scrappey is an advanced web scraping API designed for developers to effortlessly extract data from any website. It handles all complexities like rotating proxies, headless browsers, and bypassing anti-bot measures such as Cloudflare and CAPTCHAs. With a high success rate and a simple pay-as-you-go model, Scrappey streamlines data collection for various applications.
Data Extraction
Crawlora
Crawlora is an AI-powered, no-code web scraping platform that enables users to effortlessly extract data from any website. Its intelligent point-and-click interface simplifies data extraction, allowing you to turn web pages into structured data (CSV, JSON) without writing a single line of code. Ideal for market research, lead generation, and price monitoring.
Data Extraction
Octoparse
Octoparse is a powerful no-code web scraping tool that allows anyone to extract data from websites without programming. It features a visual workflow designer, an AI-powered assistant for easy setup, and hundreds of pre-built templates for popular sites. With cloud-based automation, IP rotation, and CAPTCHA solving, Octoparse handles complex scraping tasks efficiently, turning web pages into structured data for lead generation, market research, and more.
Web Scraping
Browserless
Browserless is a powerful Browser-as-a-Service (BaaS) platform designed for scalable web scraping and browser automation. It helps developers bypass CAPTCHAs and bot detectors effortlessly using Puppeteer, Playwright, or its proprietary BrowserQL language. The service manages browser infrastructure, allowing users to focus on building automation scripts without worrying about updates, memory leaks, or scaling.
Data Extraction
FetchFox
FetchFox is an AI-powered web scraping tool that allows users to extract data from any website using simple text prompts. It eliminates the need for complex coding or CSS selectors, automatically handling anti-bot measures. Available as an API, JavaScript library, and Chrome extension, it's designed for both developers and non-technical users to automate data collection effortlessly.
Data ExtractionCrawlbase Categories
Crawlbase Jobs
Crawlbase Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Scrappey
Scrappey is an advanced web scraping API designed for developers to effortlessly extract data from any website. It handles all complexities like rotating proxies, headless browsers, and bypassing anti-bot measures such as Cloudflare and CAPTCHAs. With a high success rate and a simple pay-as-you-go model, Scrappey streamlines data collection for various applications.
Data Extraction
Zyte
Zyte is a comprehensive web scraping platform offering a full-stack API and data extraction services. It simplifies data acquisition by managing proxies, headless browsers, and advanced anti-blocking systems. Powered by AI, Zyte delivers reliable, structured web data at scale for businesses in e-commerce, market research, and more.
Market IntelligenceOctoparse
Octoparse is a powerful no-code web scraping tool that allows anyone to extract data from websites without programming. It features a visual workflow designer, an AI-powered assistant for easy setup, and hundreds of pre-built templates for popular sites. With cloud-based automation, IP rotation, and CAPTCHA solving, Octoparse handles complex scraping tasks efficiently, turning web pages into structured data for lead generation, market research, and more.
Web ScrapingCrawlora
Crawlora is an AI-powered, no-code web scraping platform that enables users to effortlessly extract data from any website. Its intelligent point-and-click interface simplifies data extraction, allowing you to turn web pages into structured data (CSV, JSON) without writing a single line of code. Ideal for market research, lead generation, and price monitoring.
Data ExtractionBrowserless
Browserless is a powerful Browser-as-a-Service (BaaS) platform designed for scalable web scraping and browser automation. It helps developers bypass CAPTCHAs and bot detectors effortlessly using Puppeteer, Playwright, or its proprietary BrowserQL language. The service manages browser infrastructure, allowing users to focus on building automation scripts without worrying about updates, memory leaks, or scaling.
Data Extraction
Kadabra
Kadabra is an AI-powered platform that transforms plain English descriptions into functional, deployable business and data automations. It allows users to build, test, and deploy complex workflows visually in minutes, integrating with a wide range of popular tools to streamline operations and enhance productivity.
Operations Management
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
Thordata
Thordata is a high-performance proxy service provider designed for large-scale web data scraping and AI applications. It offers a global network of over 60 million residential, mobile, ISP, and datacenter proxies with high uptime and low latency. Thordata also provides powerful Scraper APIs and a Data Marketplace to simplify data acquisition for tasks like AI model training, e-commerce monitoring, SEO analysis, and brand protection, ensuring reliable and scalable access to public web data.
Data Collection
Serpex
Serpex is a fast, affordable, and reliable search API designed for AI and data projects. It provides real-time, structured web search results from multiple major search engines, overcoming common challenges like CAPTCHAs and geo-blocks.
Data SourceFetchFox
FetchFox is an AI-powered web scraping tool that allows users to extract data from any website using simple text prompts. It eliminates the need for complex coding or CSS selectors, automatically handling anti-bot measures. Available as an API, JavaScript library, and Chrome extension, it's designed for both developers and non-technical users to automate data collection effortlessly.
Data Extraction
Foxscrape
FoxScrape is an AI-powered web scraping REST API for developers. It simplifies data extraction by converting any website into structured JSON data using features like AI-driven parsing from plain English, JavaScript rendering for dynamic sites, and automatic proxy rotation to prevent blocks.
Data Extraction
PandaExtract
PandaExtract is the ultimate no-code web scraping Chrome extension. It allows professionals to extract data from any website with a single click. Ideal for market research, lead generation, price monitoring, and competitor analysis, it requires no programming skills.
Web Scraping
Bright Data
Bright Data is the world's leading web data platform, offering a comprehensive suite of tools including proxy networks, AI-powered web scrapers, and ready-to-use datasets. It enables businesses to collect vast amounts of public web data for AI training, market research, and competitive intelligence.
Business Intelligence
Apify
Apify is a full-stack web scraping and automation platform that enables developers to build, deploy, and publish data extraction tools, known as 'Actors'. It offers a vast marketplace of pre-built scrapers for popular websites like Google Maps, Instagram, and TikTok, alongside a robust cloud infrastructure for creating custom solutions. With support for Python and JavaScript, open-source libraries, and seamless integrations, Apify simplifies collecting web data at any scale.
Data Collection
Skyvern
Skyvern is an AI-powered browser automation platform that uses computer vision and natural language to automate complex web workflows. It can handle data extraction, form submissions, invoice retrieval, and more on any website, adapting dynamically to changes without traditional scripting.
Api
Crawlbase Comments (0)
Sign in to comment.
Sign inNo comments yet.