
Hopsworks Overview
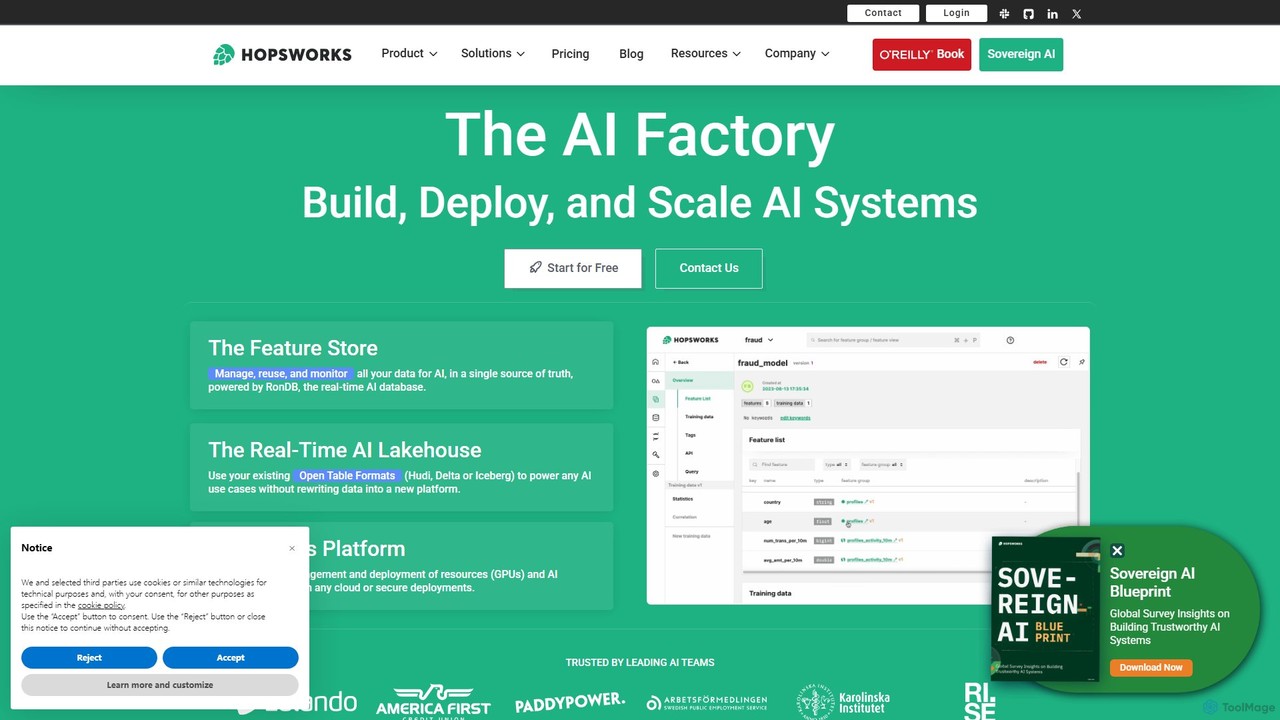
Hopsworks is a comprehensive, real-time AI Lakehouse platform designed to streamline the entire machine learning lifecycle, from data preparation to model deployment and monitoring. It serves as a central hub for data scientists, data engineers, and ML engineers, providing a unified environment to manage data, features, models, and compute resources. At its core, Hopsworks integrates a powerful Feature Store with a scalable data infrastructure, enabling organizations to build and operate high-performance, real-time AI applications with unprecedented efficiency and governance.
The platform is built on a modular and open architecture, allowing seamless integration with existing data ecosystems. It unifies your data lake, data warehouse, and databases into a cohesive AI Lakehouse, supporting popular data formats like Delta Lake, Apache Hudi, and Apache Iceberg. This unification eliminates data silos and simplifies data access for ML workloads. Powered by RonDB, a high-performance, open-source key-value store, Hopsworks delivers sub-millisecond latency for real-time feature serving, a critical requirement for use cases like fraud detection, recommendation systems, and personalized user experiences.
How to use Hopsworks
Using Hopsworks involves a streamlined workflow that accelerates the path from data to production-ready models. The process is designed to be Python-first and developer-friendly:
- Connect and Ingest Data: Begin by connecting to your Hopsworks project using the Python client. You can ingest data from any source, including data lakes, databases, or streaming platforms, using frameworks like Spark, Flink, or Pandas.
- Feature Engineering: Transform your raw data into ML-ready features. Hopsworks supports feature engineering in various frameworks, allowing you to build both batch and real-time streaming feature pipelines.
- Create Feature Groups: Organize your features into 'Feature Groups' within the Hopsworks Feature Store. You define the schema, primary keys, and whether the features should be available for online (real-time) or offline (batch) access.
- Generate Training Data: Use the Feature Store to create point-in-time correct training datasets. This crucial feature prevents data leakage by ensuring that you only use feature values that were available at the time of the event you are trying to predict.
- Train and Version Models: Train your models using any ML framework (e.g., TensorFlow, PyTorch, Scikit-learn). Hopsworks provides integrated GPU management to scale training for large models like LLMs. All models and their associated features can be versioned and tracked in the Model Registry.
- Deploy and Serve: Deploy your trained models as inference services. For real-time applications, the model can fetch features with millisecond latency from the online Feature Store, ensuring fresh and relevant data for every prediction.
Core Features of Hopsworks
- AI Lakehouse: Unifies data lakes, data warehouses, and databases, providing a single source of truth for all AI data.
- Advanced Feature Store: The most advanced unified feature store for managing, storing, discovering, and serving features for both real-time and batch use cases. Includes feature versioning, data validation, and lineage tracking.
- Real-Time Feature Serving: Delivers features with sub-millisecond latency and millisecond freshness, powered by RonDB, making it ideal for demanding real-time AI systems.
- Integrated Vector Index: A built-in vector index in the online feature store to support LLM and generative AI applications, such as RAG (Retrieval-Augmented Generation).
- Sovereign AI and Multi-Cloud: Deployable on any cloud (AWS, Azure, GCP), on-premises, or in a hybrid setup using Kubernetes, giving you full control over your data and infrastructure.
- Integrated GPU Management: Efficiently orchestrates GPU resources for training and inference of large-scale models, including LLMs.
- End-to-End MLOps: A single platform to manage the entire ML lifecycle, including feature engineering, model training, deployment, and monitoring, with strong governance and collaboration features.
- Point-in-Time Correctness: Automatically generates time-travel queries to create historically accurate training data, preventing common pitfalls in model development.
Use Cases for Hopsworks
Hopsworks is versatile and can be applied to a wide range of AI and ML applications across various industries:
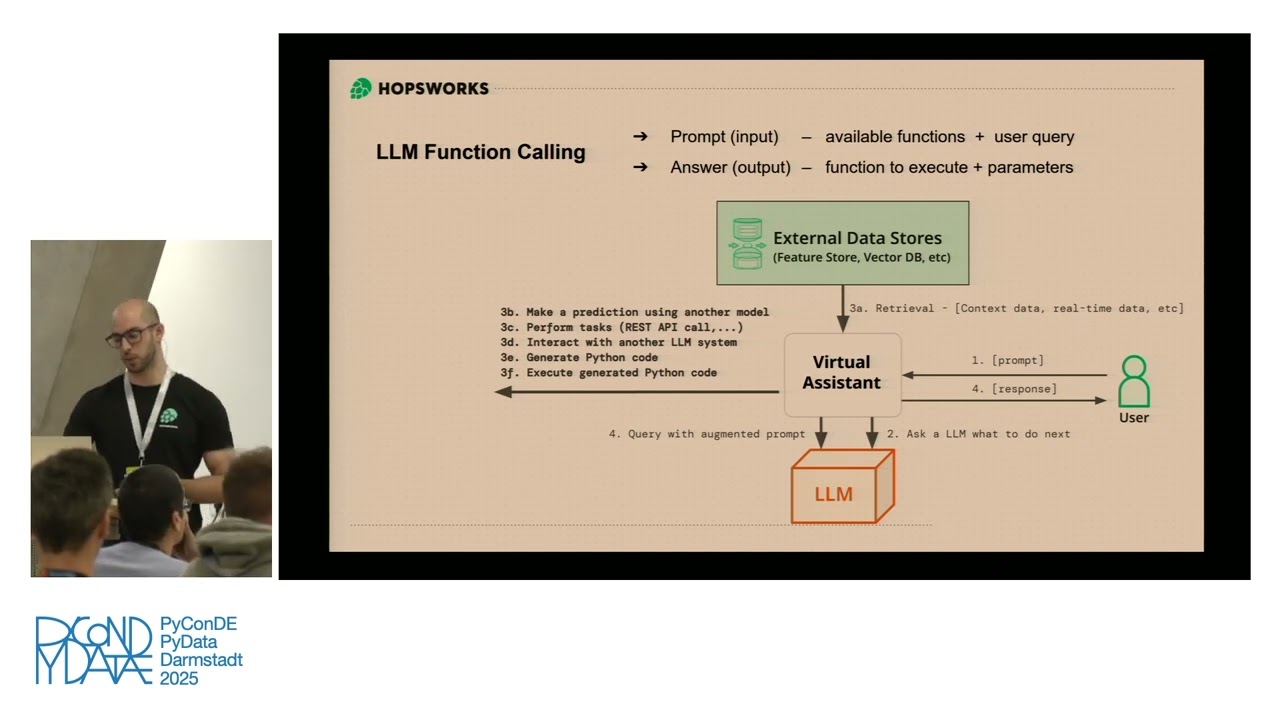
- LLMs & Agents: Building and deploying Retrieval-Augmented Generation (RAG) pipelines and other LLM-based agents that require low-latency access to contextual data from the integrated vector database.
- Predictive Analytics: Developing models for demand forecasting, churn prediction, and predictive maintenance where timely data is crucial.
- Real-Time Recommendation Systems: Powering personalized content and product recommendations by serving user features in real-time based on their latest interactions.
- Customer 360: Creating a unified, real-time view of customers by combining batch and streaming data to drive personalization and targeted marketing.
- Fraud and Anomaly Detection: Identifying fraudulent transactions or security threats in real-time by analyzing streaming data against historical patterns.
Advantages of Hopsworks
Hopsworks offers significant competitive advantages for organizations looking to scale their AI initiatives:
- Accelerated Time-to-Market: By streamlining the MLOps workflow and enabling feature reuse, Hopsworks can get models into production up to 5 times faster.
- Significant Cost Reduction: Centralizing features prevents redundant data processing and storage, leading to cost savings of up to 80%.
- Unmatched Performance: Achieves up to 10x faster ML pipelines and sub-millisecond latency for feature serving, enabling a new class of real-time AI applications.
- Enhanced Governance and Compliance: Provides 100% audit coverage, data lineage, and role-based access control, ensuring that AI systems are reliable, transparent, and compliant.
- Flexibility and No Lock-In: Its open, modular architecture supports any ML framework, data source, and deployment environment, preventing vendor lock-in.
Pricing and Plans
Hopsworks offers a flexible pricing model to suit different needs. There is a Serverless Feature Store available for free, which allows individuals and small teams to get started without any cloud infrastructure requirements. For larger organizations and enterprise use cases, Hopsworks provides managed services on major cloud platforms (AWS, Azure, GCP) and on-premises deployment options. These enterprise plans come with dedicated support, advanced security features, and custom scalability. For detailed pricing on enterprise and managed plans, it is recommended to contact the Hopsworks sales team directly for a custom quote.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 63.2K
- 2026-1: 67.6K
- 2026-2: 45.7K
- 2026-3: 40.6K
- 2026-4: 37.0K
- 2026-5: 36.8K
Geography
Top 5 countries / regions
- 🇺🇸United States35.0%
- 🇮🇳India24.9%
- 🇻🇳Vietnam16.1%
- 🇩🇪Germany12.6%
- 🇸🇪Sweden11.4%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 56.1% |
Referral | 39.9% |
Email | 3.9% |
Top keywords
| Keyword | Cost per click |
|---|---|
| flash attention | $0.00 |
| hopswork | $0.00 |
| hopsworks | $0.00 |
| two tower model | $0.00 |
| what is a lakehouse in ai | $0.00 |
Hopsworks Videos on YouTube


PyData
In Conversation with Joyce J. Shen


Hopsworks Alternatives
Tensorfuse
Tensorfuse is a serverless GPU platform that allows developers to fine-tune, deploy, and auto-scale generative AI models on their own AWS cloud. It simplifies infrastructure management, offering features like serverless inference, job queues, and dev containers to accelerate development, reduce costs, and eliminate DevOps overhead.
Deployment
Nebius
Nebius is a high-performance cloud platform specifically engineered for AI and machine learning. It provides access to the latest NVIDIA GPUs, scalable clusters with InfiniBand networking, and fully managed services like Kubernetes and Slurm, enabling seamless AI model training, fine-tuning, and inference at any scale.
Machine Learning
Arize
Arize is an AI & Agent Engineering Platform designed for development, observability, and evaluation. It provides a unified solution for teams to build, monitor, debug, and improve LLM and ML models faster. By closing the loop between development and production, Arize helps ensure AI systems are reliable, trustworthy, and high-performing at scale.
Mlops
Gmi Cloud
Gmi Cloud is a high-performance GPU cloud platform designed for scalable AI training and inference. It provides on-demand access to top-tier NVIDIA GPUs, an optimized inference engine for low latency, and a cluster engine for streamlined MLOps, enabling developers and enterprises to build, deploy, and scale AI applications efficiently and cost-effectively.
Mlops
Metaflow
A human-centric Python framework, originally from Netflix, for building and managing real-life data science, ML, and AI projects. It simplifies workflow orchestration, data management, and model deployment, enabling rapid prototyping and scalable production pipelines.
MlopsHopsworks Categories
Hopsworks Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Flyte
Flyte is an open-source, cloud-native workflow orchestration platform designed for building, deploying, and managing production-grade data, machine learning, and analytics pipelines. It emphasizes scalability, reproducibility, and ease of use, enabling teams to move from local development to large-scale production seamlessly. With a Python-first SDK and support for multiple languages, Flyte empowers data scientists and engineers to create complex, versioned, and maintainable workflows.
Mlops
ProjectPro
ProjectPro is a project-based learning platform designed to help data professionals accelerate their careers. It offers a vast library of over 250 end-to-end, industry-grade projects in Data Science, Big Data, AI, and MLOps. Each project includes verified solution code, detailed explainer videos, a cloud lab environment, and expert support, enabling users to gain practical, hands-on experience with real-world business problems and cutting-edge technologies.
Data Science
H2O.ai
H2O.ai is an end-to-end AI Cloud platform for enterprises, combining predictive and generative AI. It enables businesses to build, deploy, and manage secure, high-performance AI models and applications in any environment, from cloud to on-premise. The platform features AutoML, a Feature Store, Document AI, and robust Model Risk Management.
Enterprise Solutions
Anyscale
Anyscale is a fully-managed compute platform for scaling AI and Python workloads. Built on the open-source Ray framework by its original creators, it empowers developers to build, run, and scale distributed applications, from LLM training to data processing, with optimized performance and cost-efficiency on any cloud.
Mlops
fullstackdeeplearning
An educational platform offering courses, community, and resources for professionals building real-world AI products. It covers the entire development lifecycle, from model training and MLOps to deployment and user experience design.
Tech Community
AI News Hub
AI News Hub is a comprehensive platform providing real-time AI announcements, curated blog updates on agentic AI, RAG, and production tools. It offers a personalized feed, bookmarking capabilities, and a rich collection of learning resources, including roadmaps, courses, and videos, to keep developers and enthusiasts informed and skilled in the rapidly evolving AI landscape.
Aggregation
PloyD
PloyD is an enterprise AI operations platform designed to streamline the productionization of AI models and applications. It tackles common challenges like developer velocity bottlenecks, infrastructure complexity, team efficiency, and security compliance, enabling organizations to deploy, manage, and scale AI solutions with confidence and speed.
Rag Systems
Nexa SDK
Nexa SDK is a powerful toolkit enabling developers to deploy any AI model, including frontier and state-of-the-art models, to any device (mobile, PC, IoT, automotive) in minutes. It offers production-ready on-device inference with hardware acceleration across NPUs, GPUs, and CPUs, optimized for speed and energy efficiency.
Ai Development KitNebius
Nebius is a high-performance cloud platform specifically engineered for AI and machine learning. It provides access to the latest NVIDIA GPUs, scalable clusters with InfiniBand networking, and fully managed services like Kubernetes and Slurm, enabling seamless AI model training, fine-tuning, and inference at any scale.
Machine LearningArize
Arize is an AI & Agent Engineering Platform designed for development, observability, and evaluation. It provides a unified solution for teams to build, monitor, debug, and improve LLM and ML models faster. By closing the loop between development and production, Arize helps ensure AI systems are reliable, trustworthy, and high-performing at scale.
MlopsGmi Cloud
Gmi Cloud is a high-performance GPU cloud platform designed for scalable AI training and inference. It provides on-demand access to top-tier NVIDIA GPUs, an optimized inference engine for low latency, and a cluster engine for streamlined MLOps, enabling developers and enterprises to build, deploy, and scale AI applications efficiently and cost-effectively.
Mlops
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
AutomationMetaflow
A human-centric Python framework, originally from Netflix, for building and managing real-life data science, ML, and AI projects. It simplifies workflow orchestration, data management, and model deployment, enabling rapid prototyping and scalable production pipelines.
Mlops
UbiOps
UbiOps is a powerful MLOps platform for AI model serving, orchestration, and training. It enables data scientists and AI teams to seamlessly deploy, manage, and scale their models on any infrastructure—local, hybrid, or multi-cloud—without deep engineering expertise. The platform handles containerization, API creation, and auto-scaling, accelerating the path from development to production for various AI applications, including Generative AI and Computer Vision.
Platform As A Service (Paas)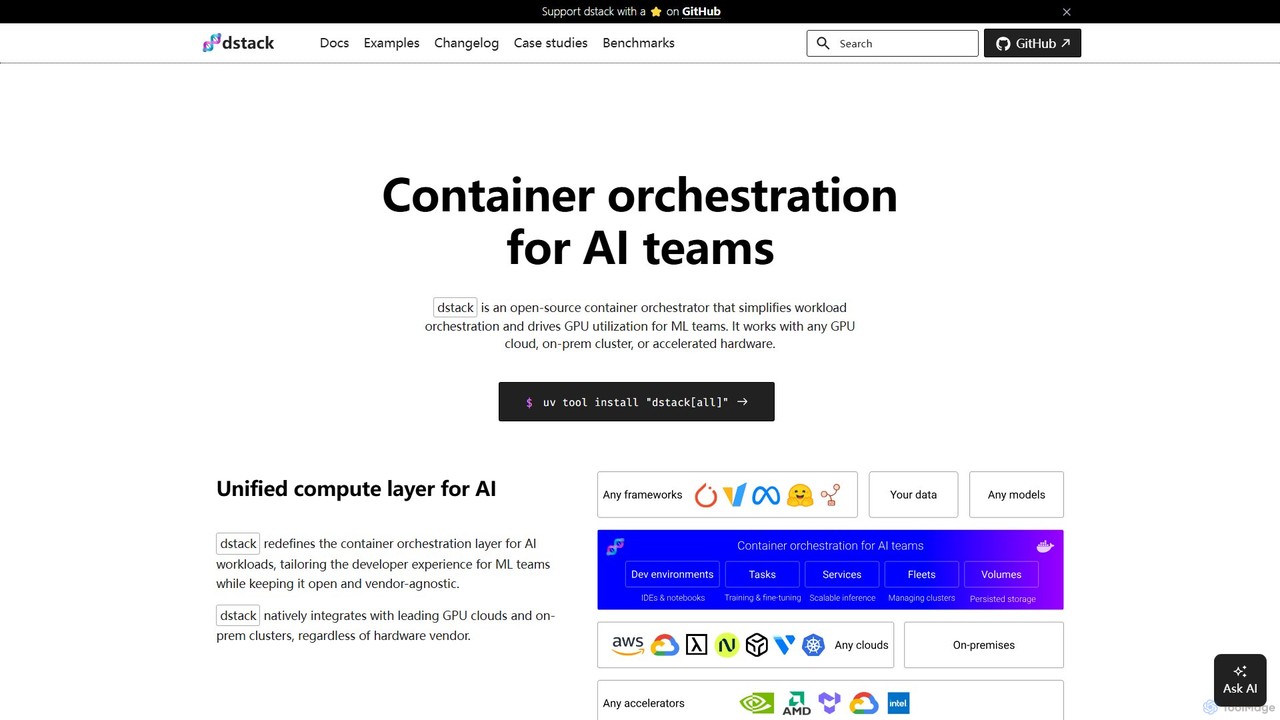
dstack
dstack is an open-source container orchestrator designed for AI and ML teams. It simplifies workload orchestration and maximizes GPU utilization across any cloud provider, on-premise cluster, or accelerated hardware. It provides a unified compute layer, streamlining development, training, and model deployment.
Orchestration
Hopsworks Comments (0)
Sign in to comment.
Sign inNo comments yet.