

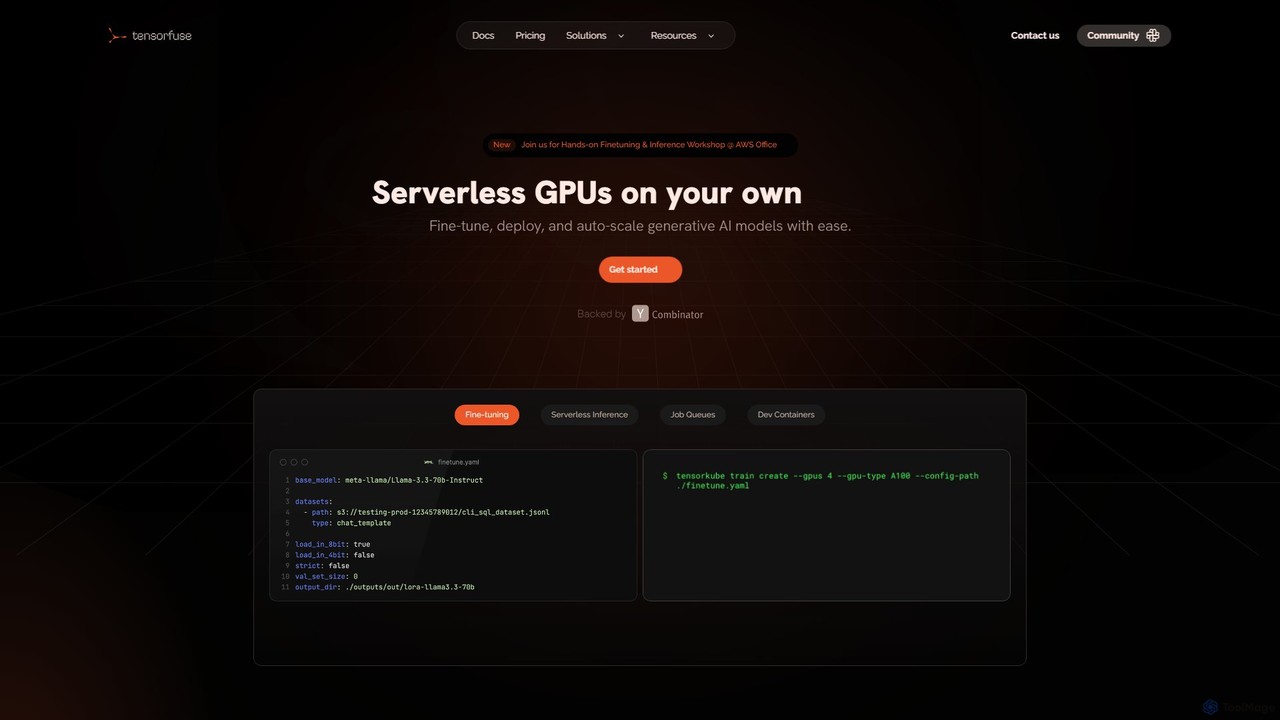
Tensorfuse Overview
Tensorfuse provides a powerful platform for developers and organizations to manage serverless GPUs directly on their own AWS cloud infrastructure. It is designed to streamline the entire lifecycle of generative AI models, from fine-tuning and experimentation to deployment and auto-scaling in production. By abstracting away the complexities of Kubernetes, Docker, and infrastructure provisioning, Tensorfuse allows teams to focus on building AI applications, significantly reducing time-to-market and operational costs.
The platform is built to offer the best of both worlds: the simplicity of a serverless architecture and the security and control of running on your private cloud. This means your proprietary data and model weights never leave your private S3 buckets, ensuring maximum security and compliance. Tensorfuse is engineered for efficiency, with an optimized container runtime that enables fast cold starts for heavy GPU workloads, allowing services to scale from zero in seconds.
How to use Tensorfuse
Getting started with Tensorfuse is designed to be a straightforward process:
- Sign Up & Connect AWS: Begin by signing up for a plan (including a free 'Hacker' tier) and connecting your AWS account. Tensorfuse will then set up the necessary resources within your cloud environment.
- Use Dev Containers for Experimentation: Connect your local IDE (like VS Code) directly to a cloud GPU using Tensorfuse's Dev Containers. This eliminates the need for SSH, code copying, and dependency management. Any changes to your local code are instantly synced, allowing for rapid real-time experimentation.
- Fine-tune Models: Utilize popular training libraries like Axolotl, Unsloth, or Hugging Face to fine-tune open-source models on your proprietary datasets. You can also write custom training loops. The platform handles the underlying GPU provisioning and management.
- Deploy for Inference: Deploy your trained or pre-trained models as serverless endpoints. These endpoints automatically scale based on incoming traffic, from zero to handle high concurrency, ensuring cost-efficiency and performance. Models can be exposed as OpenAI-compatible APIs.
- Manage with Job Queues: For asynchronous tasks like batch processing or offline inference, use the Job Queues feature. You can programmatically queue jobs, define minimum and maximum scaling parameters for efficient resource allocation, and monitor their status via a simple CLI command.
Core Features of Tensorfuse
- Serverless Inference: Automatically scales GPU deployments in response to traffic, with fast cold boots (starting containers in seconds) and the ability to scale down to zero to save costs.
- Efficient Fine-tuning: Securely fine-tune models on your private data using your cloud's S3. It offers flexible integration with popular frameworks like Axolotl and Huggingface.
- Job Queues: Deploy and queue jobs programmatically for batch processing, with efficient resource allocation and cost control through configurable scaling.
- Dev Containers: Connect local code to cloud GPUs without SSH for quick, iterative development and experimentation directly from your favorite IDE.
- Multi-LoRA Inference: Out-of-the-box support to train and hot-swap thousands of LoRA adapters on a single GPU, maximizing hardware utilization and reducing inference costs.
- Broad Hardware Support: Run workloads on a variety of hardware, including NVIDIA GPUs (A10G, A100, H100), AWS Trainium/Inferentia chips, TPUs, and FPGAs.
- Private Cloud Security: All data, datasets, and model weights remain within your private AWS S3 buckets, ensuring full control and security.
Use Cases for Tensorfuse
Tensorfuse is ideal for a wide range of AI/ML applications:
- Startups and Small Teams: Rapidly build and deploy AI-powered features without a dedicated DevOps team, moving from idea to production 20x faster.
- Large-Scale Inference: Serve generative AI models for applications with spiky or unpredictable traffic, paying only for the compute you use.
- Custom Model Fine-tuning: Companies can fine-tune base models like Llama or Mistral on their proprietary data to create specialized, high-performing models for specific business needs.
- Batch Processing Workloads: Efficiently run non-real-time tasks such as data analysis, report generation, or large-scale offline inference using the cost-effective job queue system.
- ML Research and Experimentation: Researchers and ML engineers can use Dev Containers to quickly iterate on models without waiting for infrastructure setup.
Advantages of Tensorfuse
Users choose Tensorfuse for its significant benefits, including a reported 30% reduction in cloud GPU spending and a 20x faster time to production. It eliminates the need for complex, self-managed DevOps solutions, freeing up engineering resources. The platform provides the performance and scalability of a managed service with the security and cost benefits of running on your own cloud. Testimonials highlight the exceptional and responsive support team, which assists with migration and ongoing issues, making the onboarding process smooth and efficient.
Pricing and Plans
Tensorfuse offers a tiered pricing structure to suit different needs:
- Hacker (Free): For indie developers and side projects. Includes 100 Managed GPU Hours (MGH), Serverless Inference, Dev Containers, and community support.
- Starter ($249/month): For small teams. Includes 2,000 MGH, all Hacker features, plus Fine-tuning, GitHub Actions, Custom Domains, and private Slack support. A 14-day free trial is available.
- Growth ($799/month): For scaling startups. Includes 5,000 MGH, all Starter features, plus Batch Jobs & Job Queues, Environments, Multi-LoRA inference, and premium support. A 14-day free trial is available.
- Enterprise (Custom): For large organizations needing advanced features. Includes custom MGH with volume discounts, all Growth features, plus Role-Based Access Control (RBAC), SSO, enterprise-grade security (SOC2, HIPAA), and dedicated engineering support.
- Startup Deal: Early-stage startups with less than $500K in funding may be eligible for 10,000 hours of free GPU compute management for 6 months.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 10.1K
- 2026-1: 5.4K
- 2026-2: 4.2K
- 2026-3: 4.9K
- 2026-4: 5.3K
- 2026-5: 6.7K
Geography
Top 5 countries / regions
- 🇺🇸United States38.2%
- 🇻🇳Vietnam36.6%
- 🇮🇳India25.2%
Top keywords
| Keyword | Cost per click |
|---|---|
| aws serverless gpu | $0.00 |
| brew install aws cli | $4.38 |
| llama.cpp serverless | $0.00 |
| llm inference servers compared: vllm vs tgi vs sglang vs triton | $0.00 |
| tensorfuse | $18.26 |
Tensorfuse Alternatives

Baseten
Baseten is a production-grade inference platform for deploying, scaling, and managing AI models. It offers high-performance runtimes, seamless developer workflows, and flexible deployment options (cloud, self-hosted, hybrid). Ideal for engineering and ML teams building mission-critical AI applications.
Deployment
Hopsworks
Hopsworks is a real-time AI Lakehouse and the industry's most advanced Feature Store. It's designed for MLOps, unifying data and compute to build and operate reliable, real-time AI systems. It supports any framework, cloud, or on-premises environment, enabling faster model development and significant cost reduction.
Database
Runpod
Runpod is a cloud platform designed for AI and machine learning, offering scalable GPU compute for deploying, training, and running AI models. It provides serverless GPUs, pre-built templates, and cost-effective pricing to simplify the entire AI development workflow, from idea to production.
Machine Learning
Nebius
Nebius is a high-performance cloud platform specifically engineered for AI and machine learning. It provides access to the latest NVIDIA GPUs, scalable clusters with InfiniBand networking, and fully managed services like Kubernetes and Slurm, enabling seamless AI model training, fine-tuning, and inference at any scale.
Machine Learning
dstack
dstack is an open-source container orchestrator designed for AI and ML teams. It simplifies workload orchestration and maximizes GPU utilization across any cloud provider, on-premise cluster, or accelerated hardware. It provides a unified compute layer, streamlining development, training, and model deployment.
OrchestrationTensorfuse Categories
Tensorfuse Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Baseten
Baseten is a production-grade inference platform for deploying, scaling, and managing AI models. It offers high-performance runtimes, seamless developer workflows, and flexible deployment options (cloud, self-hosted, hybrid). Ideal for engineering and ML teams building mission-critical AI applications.
DeploymentRunpod
Runpod is a cloud platform designed for AI and machine learning, offering scalable GPU compute for deploying, training, and running AI models. It provides serverless GPUs, pre-built templates, and cost-effective pricing to simplify the entire AI development workflow, from idea to production.
Machine LearningNebius
Nebius is a high-performance cloud platform specifically engineered for AI and machine learning. It provides access to the latest NVIDIA GPUs, scalable clusters with InfiniBand networking, and fully managed services like Kubernetes and Slurm, enabling seamless AI model training, fine-tuning, and inference at any scale.
Machine Learningdstack
dstack is an open-source container orchestrator designed for AI and ML teams. It simplifies workload orchestration and maximizes GPU utilization across any cloud provider, on-premise cluster, or accelerated hardware. It provides a unified compute layer, streamlining development, training, and model deployment.
Orchestration
GPUX
GPUX is a serverless, decentralized GPU cloud platform for fast and affordable AI model inference. It allows developers to run models via API and enables GPU owners to earn money by contributing their hardware to a P2P network.
Model Deployment
CircleCI
CircleCI is a leading continuous integration and continuous delivery (CI/CD) platform that automates the software development process. It enables engineering teams to build, test, and deploy code quickly, reliably, and at scale, increasing productivity and confidence in every release.
Infrastructure Management
Together AI
Together AI is a leading cloud platform for developers, providing fast, cost-effective infrastructure to run, fine-tune, and train open-source generative AI models. It offers an extensive library of over 200 models, serverless inference APIs, customizable fine-tuning, and dedicated GPU clusters, creating an end-to-end solution for building and scaling AI applications.
Gpu Infrastructure
ComfyOnline
A cloud-based platform for running ComfyUI workflows online without expensive hardware. It offers a serverless environment, one-click API deployment for AI applications, and pay-as-you-go access to high-performance GPUs like H100 and A100. It simplifies the entire process from workflow creation to scalable deployment.
Api & Infrastructure
Beam
Beam is a serverless cloud platform designed for developers to run, scale, and deploy AI/ML models and applications on GPUs with ease. It offers instant autoscaling, pay-per-second billing, and a streamlined workflow, allowing you to go from code to a scalable API in minutes without managing complex infrastructure.
Machine Learning
Addepto
Addepto is a leading AI development and Big Data consulting company that empowers businesses with custom AI solutions. They specialize in data science, machine learning, MLOps, and generative AI strategy, helping clients transform complex data into actionable insights and a competitive advantage. Addepto offers end-to-end services, from initial consultation and strategy to development, deployment, and ongoing support, ensuring tailored solutions that drive tangible business results.
Consulting
ComfyDeploy
ComfyDeploy is a cloud platform for teams to build, share, and scale ComfyUI workflows. It enables one-click deployment of production-ready APIs, provides auto-scaling GPU infrastructure, and offers simplified interfaces for non-technical users. Collaborate seamlessly, manage custom nodes and models, and turn complex creative processes into scalable applications without engineering overhead.
Model Deployment
Release.ai
Release.ai is an enterprise-grade platform for developers to easily deploy, manage, and scale high-performance AI models. It offers sub-100ms inference latency, seamless auto-scaling, robust security, and a vast library of pre-optimized models, enabling rapid integration into any development workflow with just a few lines of code.
Platform As A Service (Paas)
LastMile AI
LastMile AI is an enterprise-grade developer platform for testing, evaluating, and monitoring generative AI applications. It provides tools like AutoEval for custom evaluator fine-tuning, synthetic data generation, and real-time monitoring to ensure AI systems are reliable and production-ready.
Model Evaluation
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
MonsterAPI
MonsterAPI is a developer-centric platform that simplifies the fine-tuning and deployment of open-source generative AI models. It offers a no-code chat interface, MonsterGPT, to manage complex tasks, supporting models like Llama, SDXL, and Whisper. The platform provides scalable API endpoints and enterprise-grade GPU infrastructure at a fraction of the typical cost and time, making advanced AI accessible to all developers.
Platform As A Service (Paas)
Tensorfuse Comments (0)
Sign in to comment.
Sign inNo comments yet.