

Baseten Overview
Baseten is a comprehensive platform designed to deploy, serve, and scale AI models in production environments. It provides the necessary infrastructure, tooling, and expertise to bring AI products to market quickly and efficiently. Powered by the Baseten Inference Stack, it delivers performant model runtimes, cross-cloud high availability, and a developer-centric experience for mission-critical inference workloads.
How to use Baseten
1. Choose your deployment method: Utilize the Model APIs for instant access to pre-optimized models for prototyping, or create a Dedicated Deployment for custom, fine-tuned, or open-source models.
2. Package your model using Truss, Baseten's open-source standard, which supports any machine learning framework.
3. Deploy your model to your preferred environment: Baseten's fully-managed cloud, your own VPC for self-hosting, or a hybrid setup that combines both.
4. Scale your application automatically based on traffic, benefiting from features like fast cold starts and 99.99% uptime.
5. Optionally, leverage Baseten's inference-optimized infrastructure to train your models for the best possible production performance.
Core Features of Baseten
- Baseten Inference Stack: A high-performance engine with custom kernels, advanced caching, and the latest decoding techniques for lower latency and higher throughput.
- Flexible Deployment Options: Choose between Baseten Cloud (fully-managed), Self-hosted (in your VPC), and Hybrid deployments to meet security and performance needs.
- Broad Model Support: Deploy any custom, proprietary, or open-source model, including LLMs, image generation models (like ComfyUI workflows), transcription, and text-to-speech.
- Production-Ready Model APIs: Instantly access and evaluate a library of popular models like DeepSeek, Kimi, and Qwen with production-grade performance.
- Cloud-Native Infrastructure: Features auto-scaling, global region support across any cloud provider, blazing-fast cold starts, and a 99.99% uptime guarantee.
- Compound AI Chains: Enables granular hardware control and autoscaling for complex, multi-model AI workflows, improving GPU utilization and reducing latency.
- Expert Engineering Support: Access to forward-deployed engineers for hands-on assistance from prototype to production.
Use Cases for Baseten
Baseten is ideal for building demanding, real-time AI applications. Use cases include powering low-latency AI phone agents, developing generative AI products for image and text creation, serving high-throughput embedding models for search and retrieval, and deploying custom-built LLMs for specialized industries like finance and healthcare.
Advantages of Baseten
The primary advantages of Baseten are its exceptional performance, cost-efficiency, and scalability. By optimizing the entire inference stack, it significantly reduces latency and increases throughput, as demonstrated by helping clients like Bland AI achieve sub-400ms response times. Its pay-for-what-you-use model eliminates costs for idle time, while traffic-based autoscaling ensures reliability during rapid growth. The platform is also SOC 2 Type II certified and HIPAA compliant, ensuring enterprise-grade security.
Pricing and Plans
Baseten offers a tiered pricing structure designed for growth:
- Basic: A pay-as-you-go plan starting at $0 per month. It includes access to Dedicated Deployments, Model APIs, fast cold starts, and is SOC 2 Type II and HIPAA compliant.
- Pro: A custom-quoted plan that adds priority access to high-demand GPUs, dedicated compute, higher rate limits, and hands-on support via Slack and Zoom.
- Enterprise: A custom-quoted plan for full control, offering self-hosting in your VPC, custom SLAs, advanced security, and the ability to use existing cloud commitments.
Usage is billed based on two models:
- Model APIs: Priced per 1 million input and output tokens. For example, Kimi K2 costs $0.60/1M input tokens and $2.50/1M output tokens.
- Dedicated Deployments: Billed per minute of compute time. For instance, an A10G GPU instance is priced at $0.02012 per minute, and an H100 GPU is $0.10833 per minute.
Baseten FAQ
Traffic
Latest traffic
Status
Monthly traffic trend
- 2026-1: 197.3K
- 2026-2: 205.0K
- 2026-3: 246.2K
- 2026-4: 247.6K
- 2026-5: 265.6K
Geography
Top 5 countries / regions
- 🇺🇸United States71.0%
- 🇨🇦Canada8.1%
- 🇻🇳Vietnam7.9%
- 🇮🇳India7.0%
- 🇩🇪Germany6.0%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 85.6% |
Referral | 10.8% |
Email | 3.6% |
Top keywords
| Keyword | Cost per click |
|---|---|
| baseten | $4.41 |
| baseten careers | $0.29 |
| fireworks ai | $0.00 |
| kimi ai | $0.38 |
| together ai | $3.77 |
Baseten Videos on YouTube

Baseten


Vatsal Bajaj
No Priors: AI, Machine Learning, Tech, & Startups

Google Cloud
Baseten Alternatives
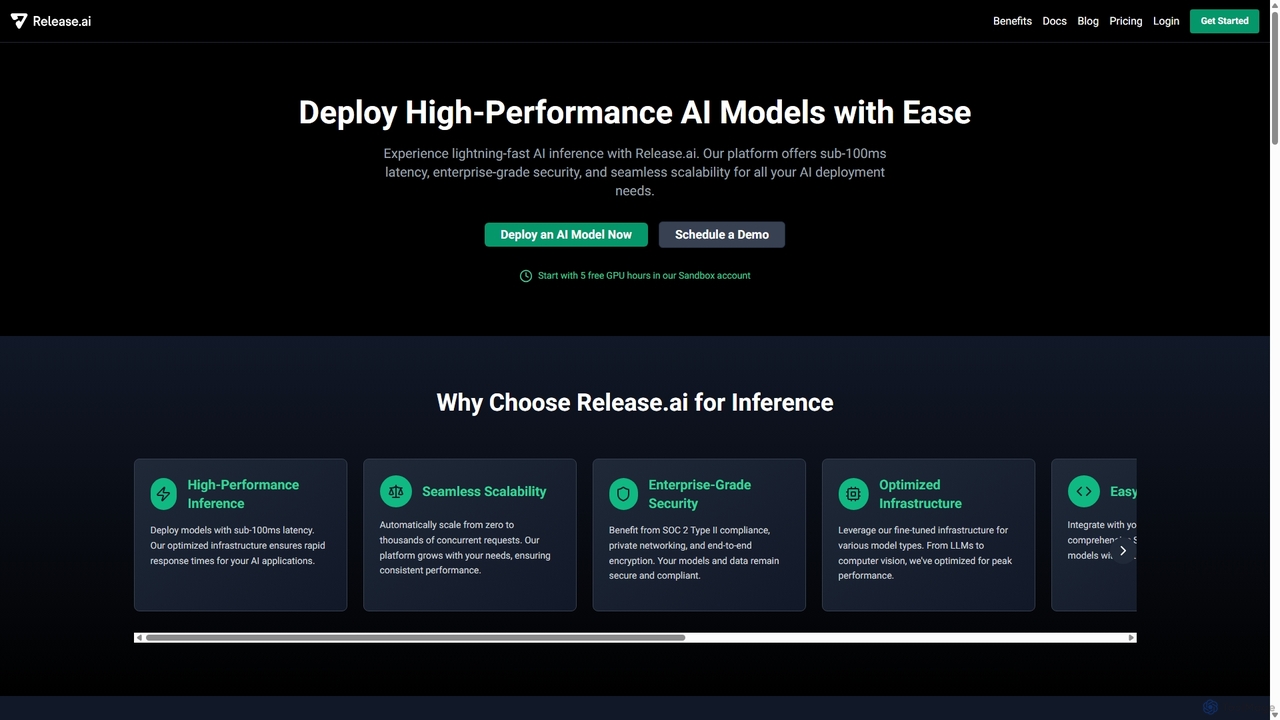
Release.ai
Release.ai is an enterprise-grade platform for developers to easily deploy, manage, and scale high-performance AI models. It offers sub-100ms inference latency, seamless auto-scaling, robust security, and a vast library of pre-optimized models, enabling rapid integration into any development workflow with just a few lines of code.
Platform As A Service (Paas)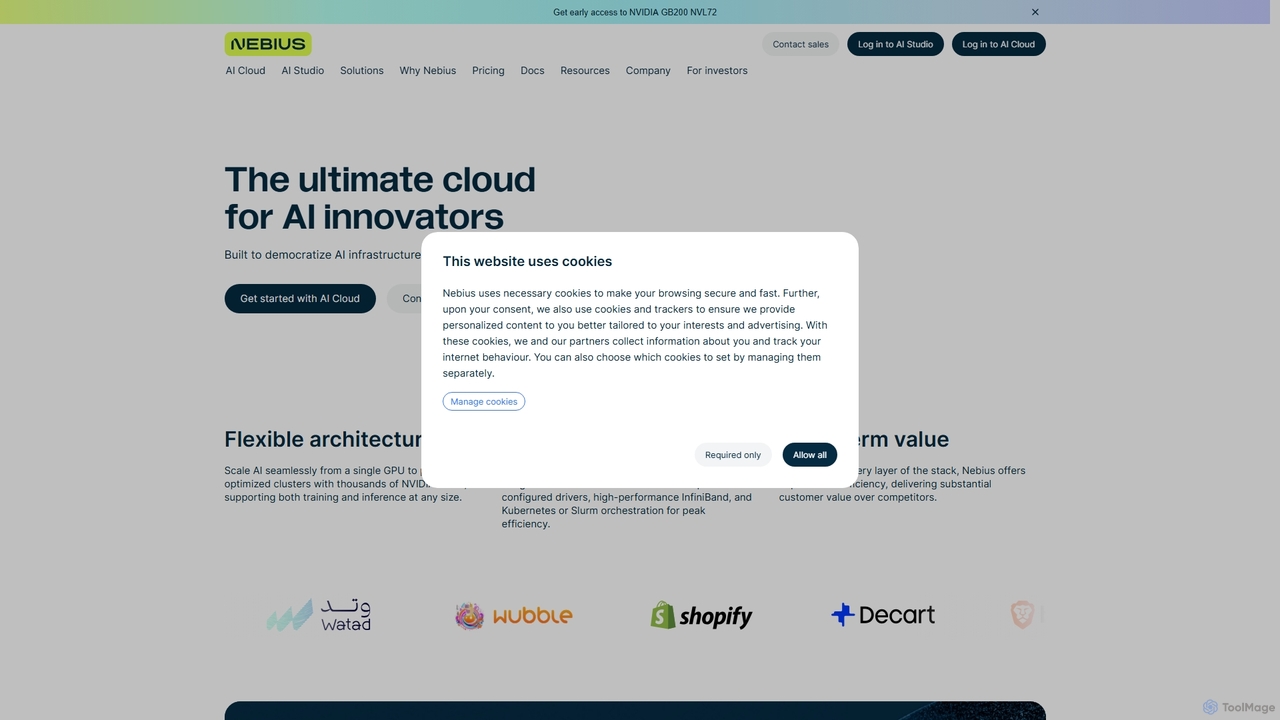
Nebius
Nebius is a high-performance cloud platform specifically engineered for demanding AI and Machine Learning workloads. It provides scalable access to the latest NVIDIA GPUs, from single instances to massive clusters, complemented by a suite of managed services and an integrated AI Studio to streamline the entire ML lifecycle from training to inference.
Gpu Cloud
Runpod
Runpod is a cloud platform designed for AI and machine learning, offering scalable GPU compute for deploying, training, and running AI models. It provides serverless GPUs, pre-built templates, and cost-effective pricing to simplify the entire AI development workflow, from idea to production.
Machine Learning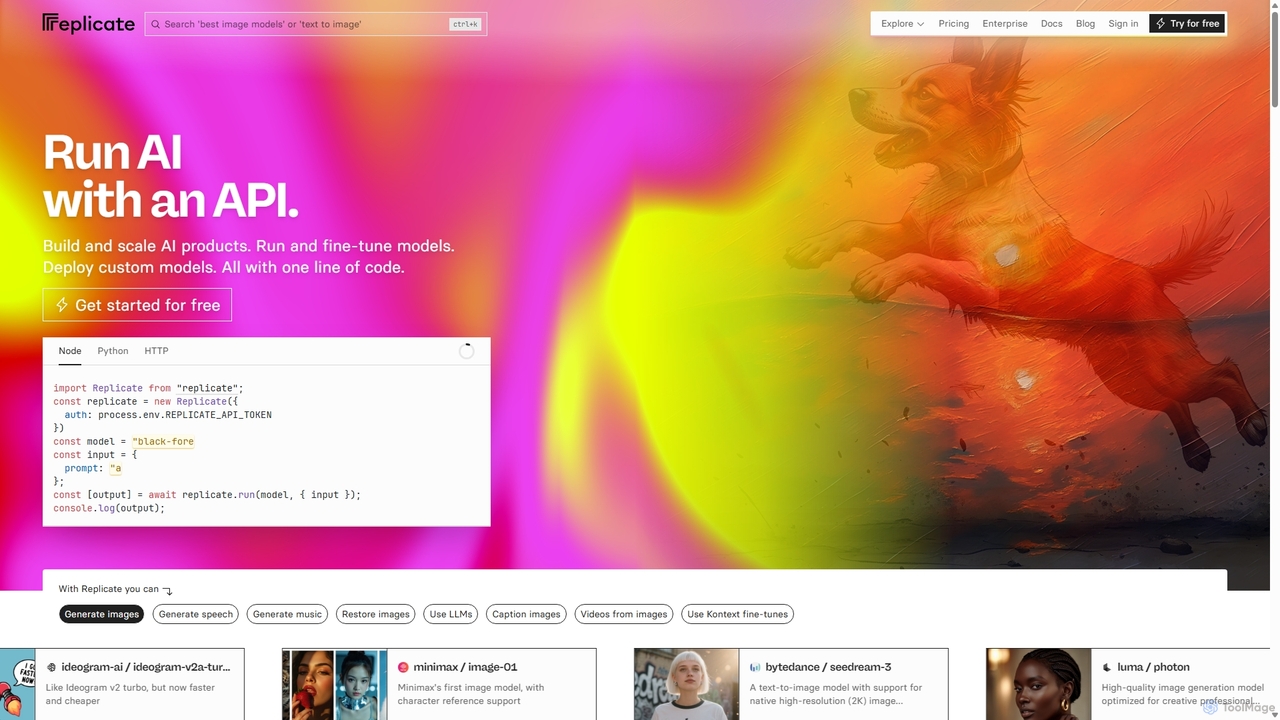
Replicate
Replicate is a cloud platform for developers to run, fine-tune, and deploy AI models via a simple API. It eliminates the need for managing complex infrastructure, offering access to thousands of models with pay-per-use pricing and automatic scaling.
Machine Learning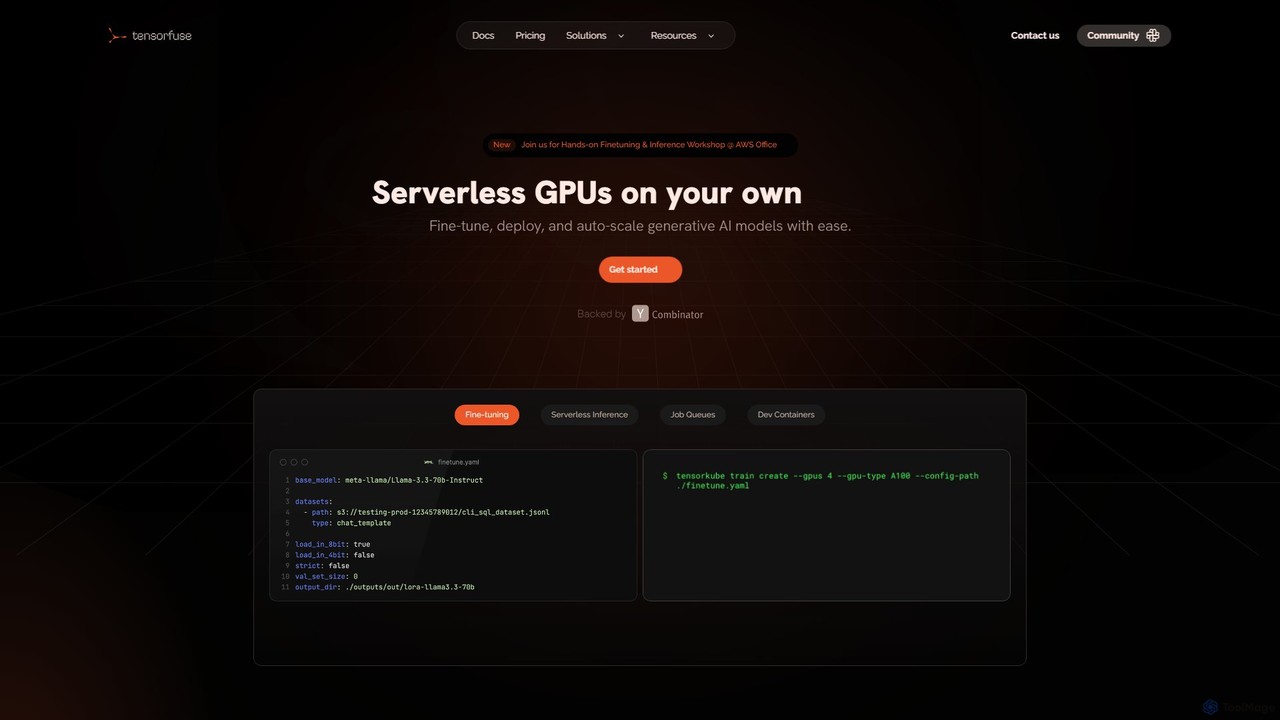
Tensorfuse
Tensorfuse is a serverless GPU platform that allows developers to fine-tune, deploy, and auto-scale generative AI models on their own AWS cloud. It simplifies infrastructure management, offering features like serverless inference, job queues, and dev containers to accelerate development, reduce costs, and eliminate DevOps overhead.
DeploymentBaseten Categories
Baseten Jobs
Baseten Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Release.ai
Release.ai is an enterprise-grade platform for developers to easily deploy, manage, and scale high-performance AI models. It offers sub-100ms inference latency, seamless auto-scaling, robust security, and a vast library of pre-optimized models, enabling rapid integration into any development workflow with just a few lines of code.
Platform As A Service (Paas)Nebius
Nebius is a high-performance cloud platform specifically engineered for demanding AI and Machine Learning workloads. It provides scalable access to the latest NVIDIA GPUs, from single instances to massive clusters, complemented by a suite of managed services and an integrated AI Studio to streamline the entire ML lifecycle from training to inference.
Gpu CloudReplicate
Replicate is a cloud platform for developers to run, fine-tune, and deploy AI models via a simple API. It eliminates the need for managing complex infrastructure, offering access to thousands of models with pay-per-use pricing and automatic scaling.
Machine Learning
LangDrive
LangDrive is a developer-centric platform offering a unified API to fine-tune, manage, and deploy open-source Large Language Models (LLMs). It simplifies the complex MLOps pipeline, enabling businesses to create powerful, custom AI models for specialized tasks with greater control over data and costs.
Api Management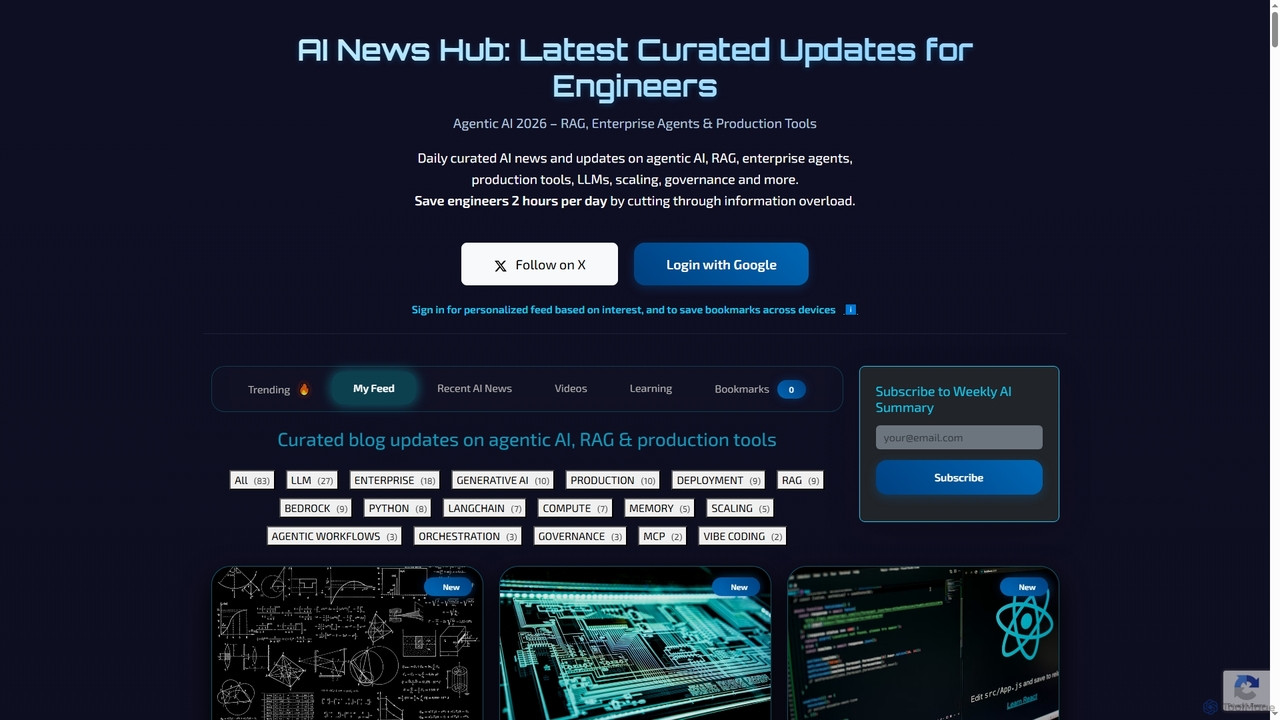
AI News Hub
AI News Hub is a comprehensive platform providing real-time AI announcements, curated blog updates on agentic AI, RAG, and production tools. It offers a personalized feed, bookmarking capabilities, and a rich collection of learning resources, including roadmaps, courses, and videos, to keep developers and enthusiasts informed and skilled in the rapidly evolving AI landscape.
Aggregation
Ollama
Ollama is a powerful open-source framework for running large language models (LLMs) like Llama 3, Mistral, and Gemma locally on your own hardware. Available for macOS, Windows, and Linux, it simplifies the setup and management of open-source models, enabling private, offline, and cost-effective AI development and usage.
Machine LearningRunpod
Runpod is a cloud platform designed for AI and machine learning, offering scalable GPU compute for deploying, training, and running AI models. It provides serverless GPUs, pre-built templates, and cost-effective pricing to simplify the entire AI development workflow, from idea to production.
Machine LearningTensorfuse
Tensorfuse is a serverless GPU platform that allows developers to fine-tune, deploy, and auto-scale generative AI models on their own AWS cloud. It simplifies infrastructure management, offering features like serverless inference, job queues, and dev containers to accelerate development, reduce costs, and eliminate DevOps overhead.
Deployment
Grably
Grably is a decentralized data ownership network (DeDON) providing high-quality, ethically sourced AI training data. It offers a vast collection of off-the-shelf datasets, custom data collection, curation, and annotation services to accelerate AI development while allowing users to monetize their data securely and transparently.
Data Labeling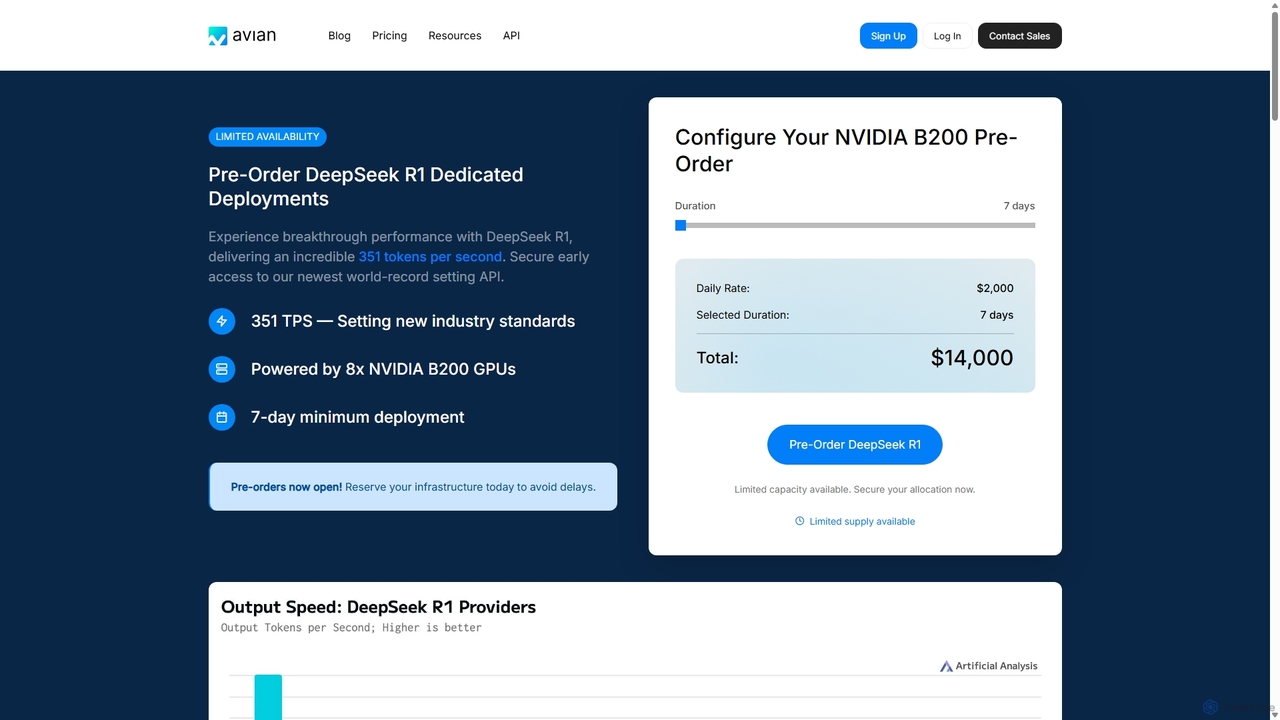
Avian
Avian is a high-performance AI inference platform offering world-record speeds for large language models (LLMs). It provides both a serverless API for popular models and dedicated GPU deployments for custom models from HuggingFace. Designed for scalability and production workloads, Avian delivers 3-10x faster inference speeds than the industry average, with enterprise-grade security and competitive pricing.
Model Deployment
UltiHash
UltiHash is a high-performance, Kubernetes-native object storage platform specifically built for AI and big data workloads. It offers lightning-fast data access, significant cost savings through advanced byte-level deduplication, and flexible deployment across cloud, on-premises, or hybrid environments. Its S3-compatible API ensures seamless integration with existing data stacks and AI workflows.
Machine Learning Operations
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
Shakespeare
Shakespeare is an open-source AI builder designed for developers to create custom AI applications. It provides a platform to select and utilize various AI models, enabling the rapid development and deployment of intelligent solutions.
Ai Development
Custom Vision
An AI service from Microsoft Azure that allows you to build, deploy, and improve your own custom image classifiers and object detectors. Easily create state-of-the-art computer vision models tailored to your specific needs with a user-friendly interface and a powerful REST API, no deep machine learning expertise required.
Machine Learning
AIGoMarket
AIGoMarket is an Edge AI Foundry and marketplace designed to democratize edge AI development. It enables creators to upload and monetize their optimized AI models, while providing developers with a platform to discover, license, and deploy high-performance AI solutions for various edge devices and applications.
Model Marketplace
Baseten Comments (0)
Sign in to comment.
Sign inNo comments yet.