
Models Overview
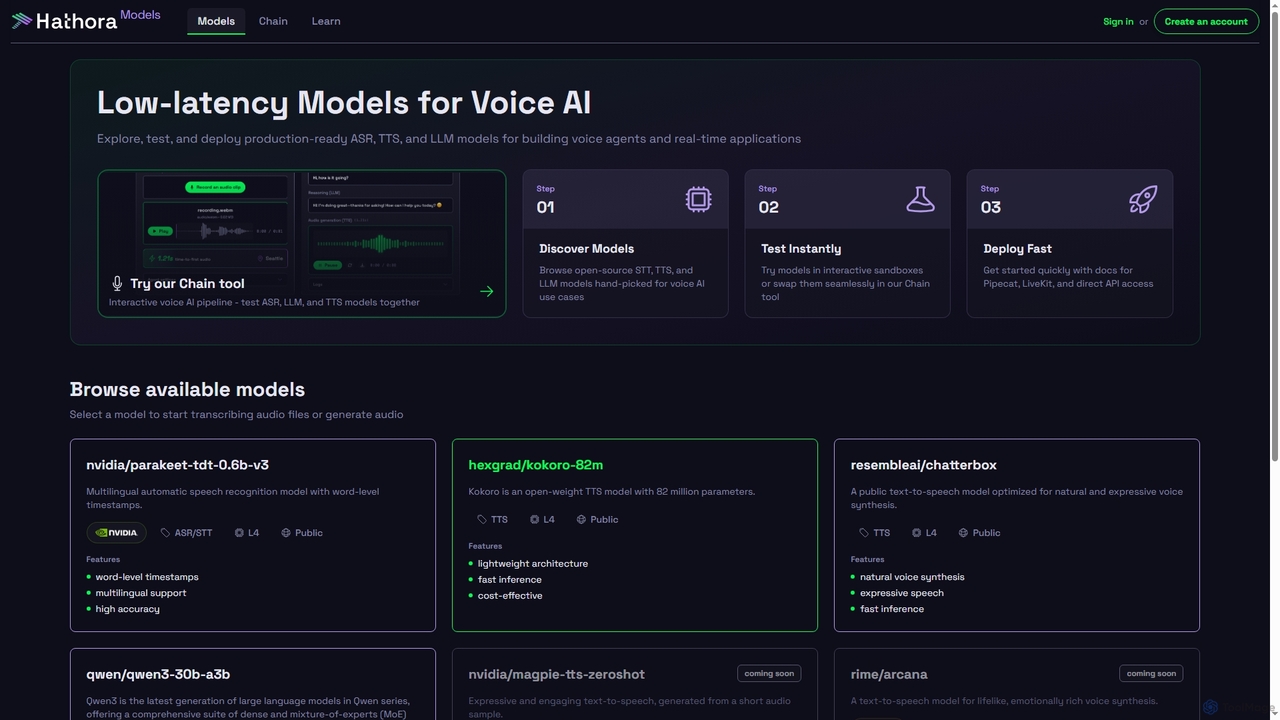
Models by Hathora offers a specialized platform designed for developers and engineers to efficiently discover, test, and deploy high-performance AI models for voice-centric applications. Focusing on low-latency requirements, the platform provides a curated selection of Automatic Speech Recognition (ASR), Text-to-Speech (TTS), and Large Language Model (LLM) models. These models are hand-picked and optimized for building sophisticated voice agents and real-time interactive experiences, ensuring production readiness and ease of integration.
How to use Models
To use Models, developers can begin by exploring the comprehensive catalog of open-source ASR, TTS, and LLM models, each specifically chosen for voice AI use cases. Once a model is selected, it can be instantly tested within interactive sandboxes provided on the platform. For more complex scenarios, the innovative Chain tool allows users to test ASR, LLM, and TTS models together in an interactive voice AI pipeline. Deployment is streamlined with documentation and direct API access, supporting integration with platforms like Pipecat and LiveKit, enabling rapid development of real-time applications.
Core Features of Models
- Curated Model Catalog: Access a hand-picked selection of open-source ASR, TTS, and LLM models optimized for voice AI.
- Interactive Testing Sandboxes: Instantly try out models in dedicated sandboxes to evaluate performance and capabilities.
- Chain Tool: An interactive pipeline for testing ASR, LLM, and TTS models collaboratively for end-to-end voice AI solutions.
- Fast Deployment Options: Quick integration with documentation for Pipecat, LiveKit, and direct API access.
- Low-Latency Performance: Models are optimized for real-time applications and voice agents.
- Multilingual Support: Includes models like `nvidia/parakeet-tdt-0.6b-v3` for multilingual ASR and `Qwen/Qwen3-30B-A3B` supporting 100+ languages.
- Word-Level Timestamps: Available with ASR models like `nvidia/parakeet-tdt-0.6b-v3` for precise transcription.
- Expressive Voice Synthesis: TTS models such as `ResembleAI/chatterbox` and `rime/arcana` offer natural, expressive, and emotionally rich speech.
- Zero-Shot Voice Cloning: Upcoming TTS models like `nvidia/magpie-tts-zeroshot` will offer voice cloning from short audio samples.
Use Cases for Models
Models is ideal for developing a wide range of voice AI applications. It can be used to build highly responsive voice assistants and chatbots that understand and respond naturally. Developers can leverage it for creating real-time transcription services, enabling live captioning or meeting summaries. Its TTS capabilities are perfect for generating natural and expressive voiceovers for content, interactive voice response (IVR) systems, or personalized audio experiences. Furthermore, the LLM integration allows for advanced reasoning and instruction-following in conversational AI, making it suitable for complex agent capabilities in customer service, education, or entertainment.
Advantages of Models
The primary advantage of Models lies in its focus on low-latency, production-ready voice AI. Developers benefit from a curated selection of high-quality, open-source models, saving time on model discovery and evaluation. The interactive testing environment, including the unique Chain tool, accelerates the development cycle by allowing seamless experimentation and integration of different AI components. Fast deployment options via API and popular platforms ensure that applications can go live quickly. The platform's emphasis on performance, multilingual support, and advanced features like word-level timestamps and expressive voice synthesis provides a robust foundation for cutting-edge voice AI solutions.
Models FAQ
Models Alternatives
Play
play is an advanced Voice AI platform for businesses, specializing in ultra-realistic Text-to-Speech (TTS) models and intelligent Voice Agents. It enables companies to create 24/7 automated agents for customer service, sales, and operations. With features like custom knowledge bases, API integrations for real-world actions, on-premise deployment for data security, and support for over 30 languages, play helps businesses scale their voice communications and enhance customer interactions globally.
Text To Speech
Gabber
Gabber is a powerful platform for building real-time, multimodal AI applications that can see, hear, and speak. It offers low-latency inference for Vision Language Models (VLM), Text-to-Speech (TTS), and Speech-to-Text (STT), coupled with a graph-based orchestration system for rapid development and deployment.
Conversational Ai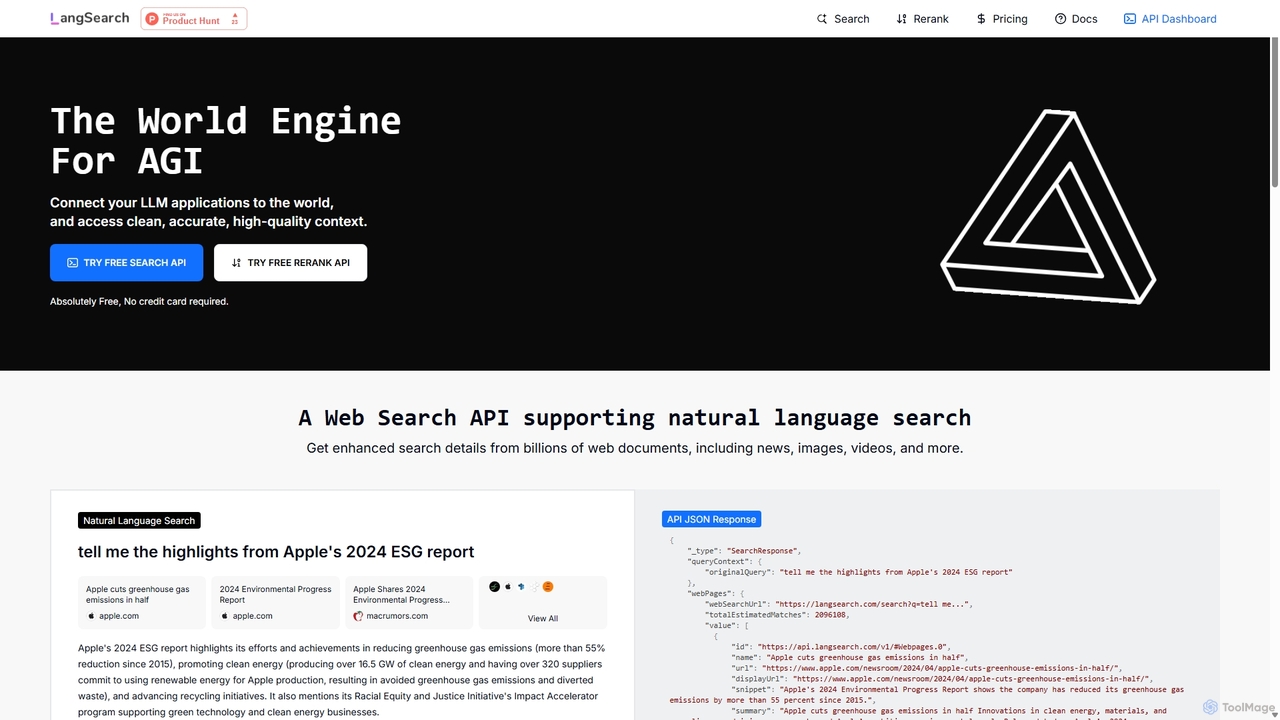
LangSearch
LangSearch provides free Web Search and Semantic Rerank APIs designed to connect LLM applications with clean, accurate, real-world context. It supports natural language queries, hybrid search, and offers a highly efficient reranker to improve result accuracy for AI agents, chatbots, and RAG systems.
Llm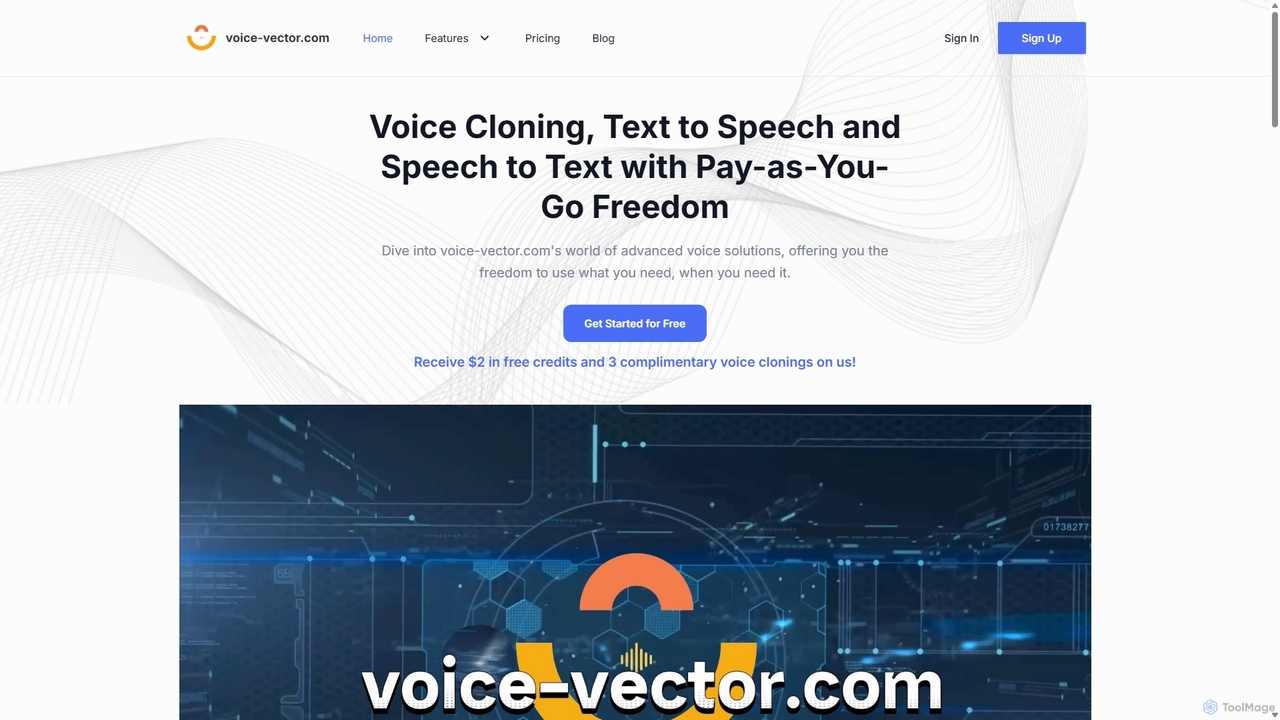
voice_vector
voice_vector is a powerful AI voice platform offering high-fidelity voice cloning, expressive text-to-speech (TTS), and accurate speech recognition. With a unique pay-as-you-go and subscription hybrid model, it provides a flexible, cost-effective solution for content creators, developers, and businesses. Create unlimited private cloned voices and integrate advanced voice capabilities into your projects via a robust API.
Text To Speech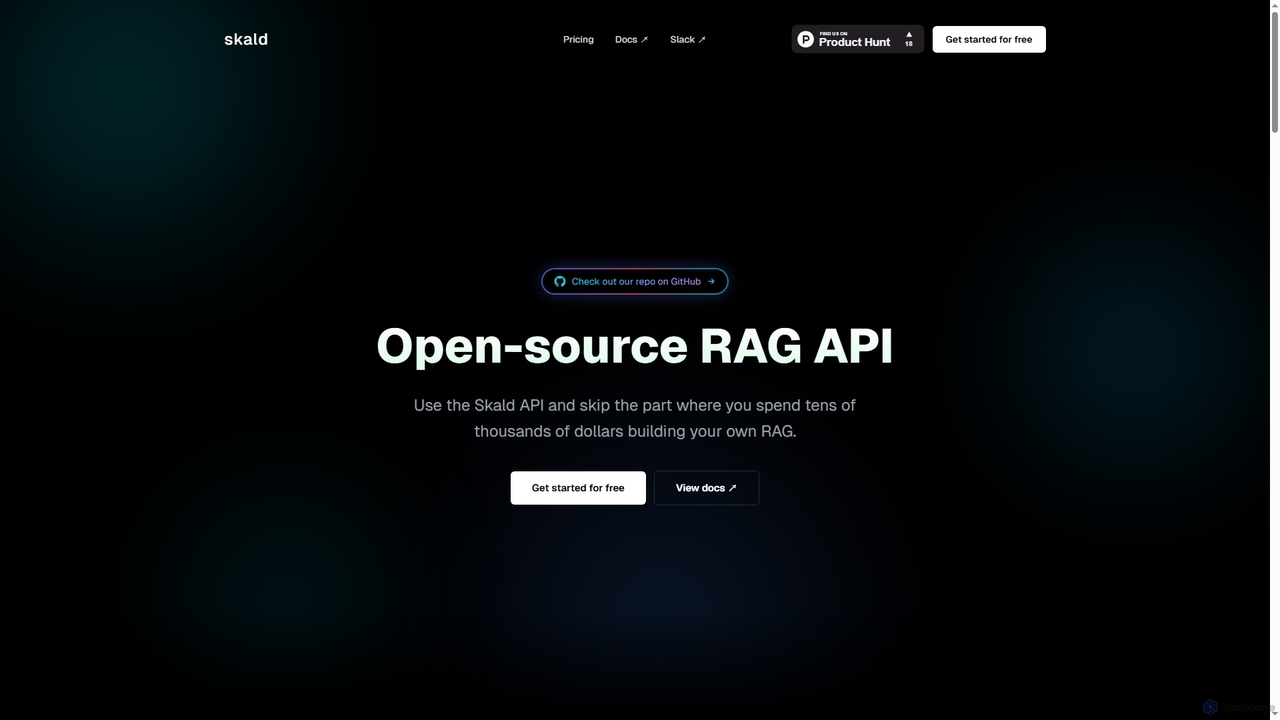
Skald
Skald is an open-source RAG API designed for developers to quickly build AI agents without the complexity of managing RAG infrastructure. It simplifies knowledge storage, context management, and semantic search, offering a powerful solution for integrating long-term memory into AI applications.
RagModels Categories
Models Jobs
Models Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Gabber
Gabber is a powerful platform for building real-time, multimodal AI applications that can see, hear, and speak. It offers low-latency inference for Vision Language Models (VLM), Text-to-Speech (TTS), and Speech-to-Text (STT), coupled with a graph-based orchestration system for rapid development and deployment.
Conversational Ai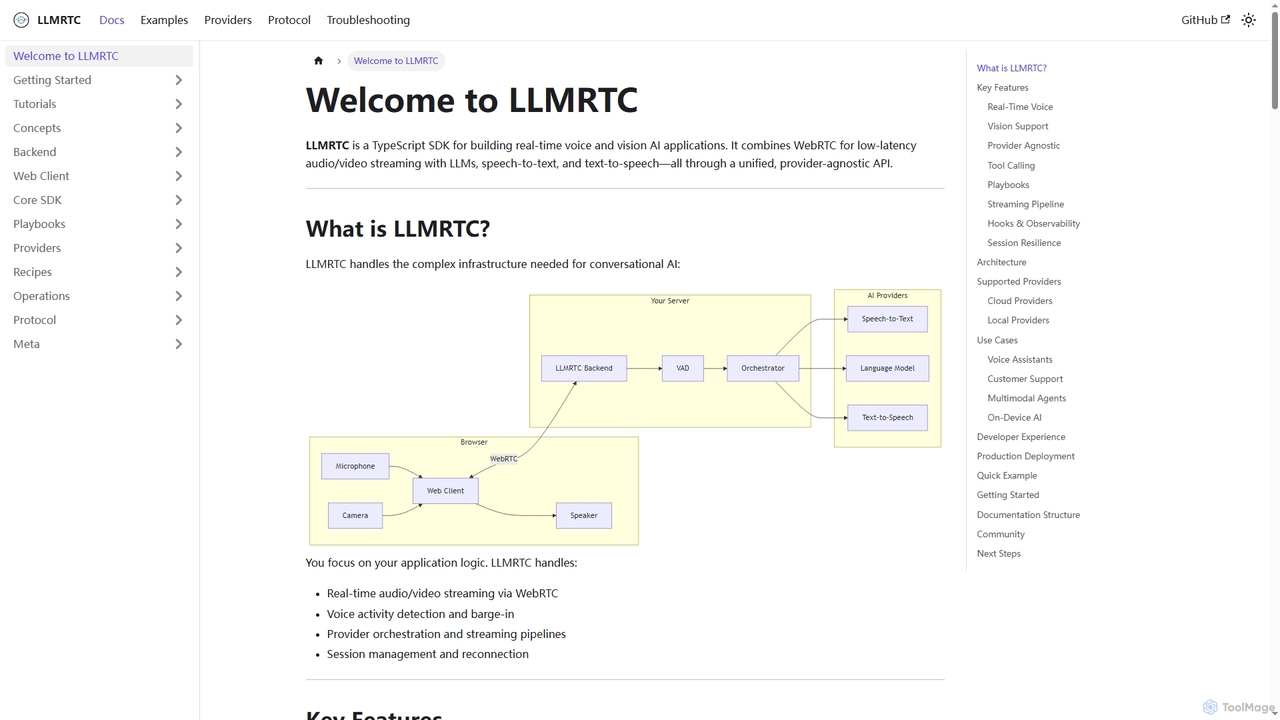
LLMRTC
LLMRTC is a TypeScript SDK for building real-time voice and vision AI applications. It integrates WebRTC for low-latency audio/video streaming with LLMs, speech-to-text, and text-to-speech technologies through a unified, provider-agnostic API. Developers can focus on application logic while LLMRTC handles complex conversational AI infrastructure.
Conversational AiPlay
play is an advanced Voice AI platform for businesses, specializing in ultra-realistic Text-to-Speech (TTS) models and intelligent Voice Agents. It enables companies to create 24/7 automated agents for customer service, sales, and operations. With features like custom knowledge bases, API integrations for real-world actions, on-premise deployment for data security, and support for over 30 languages, play helps businesses scale their voice communications and enhance customer interactions globally.
Text To Speechvoice_vector
voice_vector is a powerful AI voice platform offering high-fidelity voice cloning, expressive text-to-speech (TTS), and accurate speech recognition. With a unique pay-as-you-go and subscription hybrid model, it provides a flexible, cost-effective solution for content creators, developers, and businesses. Create unlimited private cloned voices and integrate advanced voice capabilities into your projects via a robust API.
Text To Speech
Intervo
Intervo is an open-source platform for businesses to build and deploy intelligent voice and chat AI agents. It automates customer interactions, streamlines workflows, and enhances lead qualification, customer support, and internal operations with advanced conversational AI.
Chatbot
Vectra
Vectra is an open-source, production-grade SDK for Node.js and Python, designed to build, manage, and query advanced Retrieval-Augmented Generation (RAG) pipelines. It offers a comprehensive toolkit for developing context-aware AI applications, optimized for low latency, high precision, and scalability.
Rag Pipelines
Peargent
Peargent is a modern, powerful Python framework designed for building intelligent, production-grade AI agents. It offers an intuitive API, flexible LLM support, multi-agent orchestration, and persistent memory, enabling developers to create scalable and robust AI solutions for real-world use.
Agent Development
Sindarin
Sindarin is an accelerated cloud platform for developers building low-latency, conversational voice AI. It provides an API and a no-code platform to create highly responsive and natural-sounding AI personas. With industry-leading turn-taking and seamless interruption handling, Sindarin enables the creation of truly interactive voice experiences for applications in customer service, wellness, gaming, and more, offering enterprise-grade scale and reliability.
Virtual Assistant
Outspeed
An API and SDK for developers to build and deploy AI voice companions with real-time emotion and memory. Easily integrate natural, low-latency voice interactions into web and mobile applications.
Voice Chatbot
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
AutomationLangSearch
LangSearch provides free Web Search and Semantic Rerank APIs designed to connect LLM applications with clean, accurate, real-world context. It supports natural language queries, hybrid search, and offers a highly efficient reranker to improve result accuracy for AI agents, chatbots, and RAG systems.
LlmSkald
Skald is an open-source RAG API designed for developers to quickly build AI agents without the complexity of managing RAG infrastructure. It simplifies knowledge storage, context management, and semantic search, offering a powerful solution for integrating long-term memory into AI applications.
Rag
LLM Models
LLM Models is a comprehensive online directory and comparison platform for large language models and foundation models. It provides detailed technical specifications, benchmark performance, and feature comparisons to help developers, researchers, and businesses select the most suitable AI models for their needs.
Model Directory
LangDrive
LangDrive is a developer-centric platform offering a unified API to fine-tune, manage, and deploy open-source Large Language Models (LLMs). It simplifies the complex MLOps pipeline, enabling businesses to create powerful, custom AI models for specialized tasks with greater control over data and costs.
Api Management
Helicone
Helicone is an open-source platform offering an AI Gateway and LLM Observability for developers. It helps build reliable AI applications by providing tools to route, monitor, debug, and analyze LLM usage. Key features include a unified API for 100+ models, intelligent caching, rate limiting, prompt management, and detailed performance analytics.
Api Management
Models Comments (0)
Sign in to comment.
Sign inNo comments yet.