

Pinecone Overview
Pinecone is a leading, fully managed vector database designed to be the long-term memory for AI. It empowers developers to build high-performance, knowledgeable, and reliable AI applications by providing a simple and scalable way to store, index, and query high-dimensional vector embeddings. With its serverless architecture, Pinecone eliminates the complexities of infrastructure management, allowing teams to focus on creating innovative AI-powered features such as semantic search, retrieval-augmented generation (RAG), recommendation systems, and intelligent agents.
Trusted by some of the world's most innovative companies, Pinecone is built for production workloads, capable of handling billions of vectors with low latency and high accuracy. It provides the critical infrastructure needed to connect large language models (LLMs) to private data, ensuring that AI applications can deliver relevant, accurate, and context-aware responses.
How to use Pinecone
Getting started with Pinecone is straightforward and designed for a seamless developer experience:
- Sign Up & Get API Key: Create a free account on the Pinecone website to obtain your API key and environment details.
- Install Client: Install the official Pinecone client for your preferred language, such as Python:
pip install pinecone. - Initialize Connection: In your application, import and initialize the Pinecone client with your API key and environment.
- Create an Index: Define and create a vector index. You need to specify a name for the index, the dimension of your vectors (e.g., 1536 for OpenAI's Ada-002), and the distance metric (e.g., 'cosine', 'euclidean').
- Generate & Upsert Vectors: Convert your data (text, images, etc.) into vector embeddings using a model of your choice. Then, 'upsert' (update or insert) these vectors, along with their unique IDs and any associated metadata, into your Pinecone index.
- Query Your Data: To find relevant information, generate a query vector from your input (e.g., a user's search query) and use it to query the index. Pinecone will return the most similar vectors based on the chosen metric, which you can then use to retrieve the original data. You can also apply metadata filters to refine search results.
Core Features of Pinecone
- Serverless Architecture: Automatically scales compute and storage resources based on your workload, ensuring high performance and cost-efficiency without any manual intervention.
- High-Performance Search: Delivers low-latency, high-recall search results, even across billions of vectors, making it suitable for real-time applications.
- Hybrid Search: Combines dense vector search (for semantic meaning) with sparse keyword search (for exact matches) to deliver superior relevance.
- Advanced Metadata Filtering: Supports rich, real-time filtering on metadata associated with vectors, allowing for complex and precise queries.
- Real-time Indexing: Vectors are indexed and available for querying within milliseconds of being upserted, ensuring your application always has access to the freshest data.
- Namespaces: Allows for partitioning data within a single index, enabling multi-tenancy, data isolation, and easier management for different users or data sources.
- Broad Integrations: Seamlessly integrates with popular cloud providers (AWS, GCP, Azure), machine learning frameworks (LangChain, LlamaIndex), and embedding models.
- Enterprise-Grade Security & Compliance: Offers robust security features including encryption at rest and in transit, private networking, and is compliant with SOC 2, GDPR, ISO 27001, and HIPAA.
Use Cases for Pinecone
Pinecone is versatile and powers a wide range of AI applications:
- Retrieval-Augmented Generation (RAG): Connect LLMs to your private knowledge bases to provide factual, up-to-date context, reducing hallucinations and enabling question-answering over your own data.
- Semantic Search: Implement search systems that understand the intent and context of a query, not just keywords. This is used for searching across documents, products, images, and more.
- Recommender Systems: Build sophisticated recommendation engines that suggest relevant products, articles, or content to users based on their behavior and the semantic similarity of items.
- AI Agents: Provide long-term memory for autonomous agents, allowing them to recall past interactions and information to perform complex, multi-step tasks more effectively.
- Threat Detection & Anomaly Detection: Identify unusual patterns or outliers in large datasets by finding data points that are distant from others in the vector space.
Advantages of Pinecone
Pinecone offers significant advantages for developers and businesses:
- Ease of Use: A simple API and fully managed service abstract away the complexity of vector databases.
- Scalability: Effortlessly scales from free-tier projects to enterprise applications with billions of items.
- Cost-Effective: The serverless, pay-as-you-go model ensures you only pay for the resources you consume, optimizing costs.
- High Relevance: Advanced features like hybrid search and rerankers ensure the most accurate and useful results are returned to the user.
- Reliability: Designed for mission-critical applications with high uptime SLAs and robust support options.
Pricing and Plans
Pinecone offers a flexible, freemium pricing model designed to scale with your needs:
- Starter Plan (Free): Perfect for getting started, experimenting, and for small-scale applications. It includes a generous free tier for storage and monthly operations.
- Standard Plan (Paid): A pay-as-you-go plan starting at a minimum of $50/month. It's designed for production applications of any scale and offers unlimited storage, more projects, and advanced features like backup and restore.
- Enterprise Plan (Paid): Starting at a minimum of $500/month, this plan is for mission-critical applications requiring the highest level of security, support, and reliability. It includes features like SAML SSO, private networking, HIPAA compliance, and a 99.95% uptime SLA.
- Dedicated Plan (Custom): For organizations that require a dedicated deployment within their own cloud environment (BYOC) for maximum security and control. Pricing is custom.
Usage is typically billed based on storage (per GB/month), write units (per million), and read units (per million).
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 713.5K
- 2026-1: 627.7K
- 2026-2: 536.6K
- 2026-3: 648.0K
- 2026-4: 602.3K
- 2026-5: 648.0K
Geography
Top 5 countries / regions
- 🇺🇸United States49.4%
- 🇮🇳India39.3%
- 🇬🇧United Kingdom4.5%
- 🇨🇦Canada3.8%
- 🇩🇪Germany3.0%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 74.3% |
Referral | 21.8% |
Email | 3.9% |
Top keywords
| Keyword | Cost per click |
|---|---|
| pinecode | $0.77 |
| pinecone | $1.58 |
| pinecone ai | $10.80 |
| pinecone nexus | $0.00 |
| pinecone vector database | $3.11 |
Pinecone Videos on YouTube


Harrys Waller | AI Automation


Aishwarya Srinivasan

Simplilearn
Pinecone Alternatives
LanceDB
LanceDB is an open-source, AI-native multimodal lakehouse designed for building and scaling AI applications. It provides a unified platform for storing, searching, and managing complex data like text, images, voice, and vectors. Ideal for RAG, semantic search, and model training, LanceDB offers blazing-fast hybrid search, massive scalability to petabytes, and significant cost savings, making it a powerful foundation for enterprise-grade AI.
Vector Database
Milvus
Milvus is a high-performance, open-source vector database built for AI applications. It enables developers to manage and search through billions of high-dimensional vectors with minimal latency. Ideal for building scalable systems like retrieval-augmented generation (RAG), recommendation engines, and semantic search, Milvus offers flexible deployment options from local prototyping to large-scale distributed clusters.
Machine Learning
Superlinked
Superlinked is a Python framework and cloud infrastructure, known as The Vector Computer, designed for AI engineers. It enables the creation of high-performance search and recommendation applications by effectively combining structured and unstructured data into multi-modal vector embeddings.
Vector Search
Morphik
Morphik is an advanced developer platform for building highly accurate Retrieval-Augmented Generation (RAG) systems and AI agents. It specializes in eliminating hallucinations by using visual-first retrieval to understand complex, domain-specific documents, including diagrams and schematics. Deployable with just two lines of code, it offers superior performance, speed, and scalability for enterprise-grade AI applications.
Enterprise
SvectorDB
SvectorDB is a serverless vector database designed for developers. It simplifies building AI applications like recommendation engines, semantic search, and RAG systems with pay-per-request pricing, instant updates, and built-in vectorizers. Go from prototype to production with just a few lines of code.
Vector SearchPinecone Categories
Pinecone Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
LanceDB
LanceDB is an open-source, AI-native multimodal lakehouse designed for building and scaling AI applications. It provides a unified platform for storing, searching, and managing complex data like text, images, voice, and vectors. Ideal for RAG, semantic search, and model training, LanceDB offers blazing-fast hybrid search, massive scalability to petabytes, and significant cost savings, making it a powerful foundation for enterprise-grade AI.
Vector DatabaseMilvus
Milvus is a high-performance, open-source vector database built for AI applications. It enables developers to manage and search through billions of high-dimensional vectors with minimal latency. Ideal for building scalable systems like retrieval-augmented generation (RAG), recommendation engines, and semantic search, Milvus offers flexible deployment options from local prototyping to large-scale distributed clusters.
Machine LearningSuperlinked
Superlinked is a Python framework and cloud infrastructure, known as The Vector Computer, designed for AI engineers. It enables the creation of high-performance search and recommendation applications by effectively combining structured and unstructured data into multi-modal vector embeddings.
Vector SearchSvectorDB
SvectorDB is a serverless vector database designed for developers. It simplifies building AI applications like recommendation engines, semantic search, and RAG systems with pay-per-request pricing, instant updates, and built-in vectorizers. Go from prototype to production with just a few lines of code.
Vector Search
Qdrant
Qdrant is a high-performance, open-source vector database and similarity search engine built in Rust. It's designed to power next-generation AI applications by efficiently managing and searching billions of high-dimensional vectors. With advanced features like rich filtering, payload storage, and various quantization methods, Qdrant enables developers to build scalable and cost-effective solutions for semantic search, recommendation systems, and Retrieval Augmented Generation (RAG).
Vector Search
Skald
Skald is an open-source RAG API designed for developers to quickly build AI agents without the complexity of managing RAG infrastructure. It simplifies knowledge storage, context management, and semantic search, offering a powerful solution for integrating long-term memory into AI applications.
Rag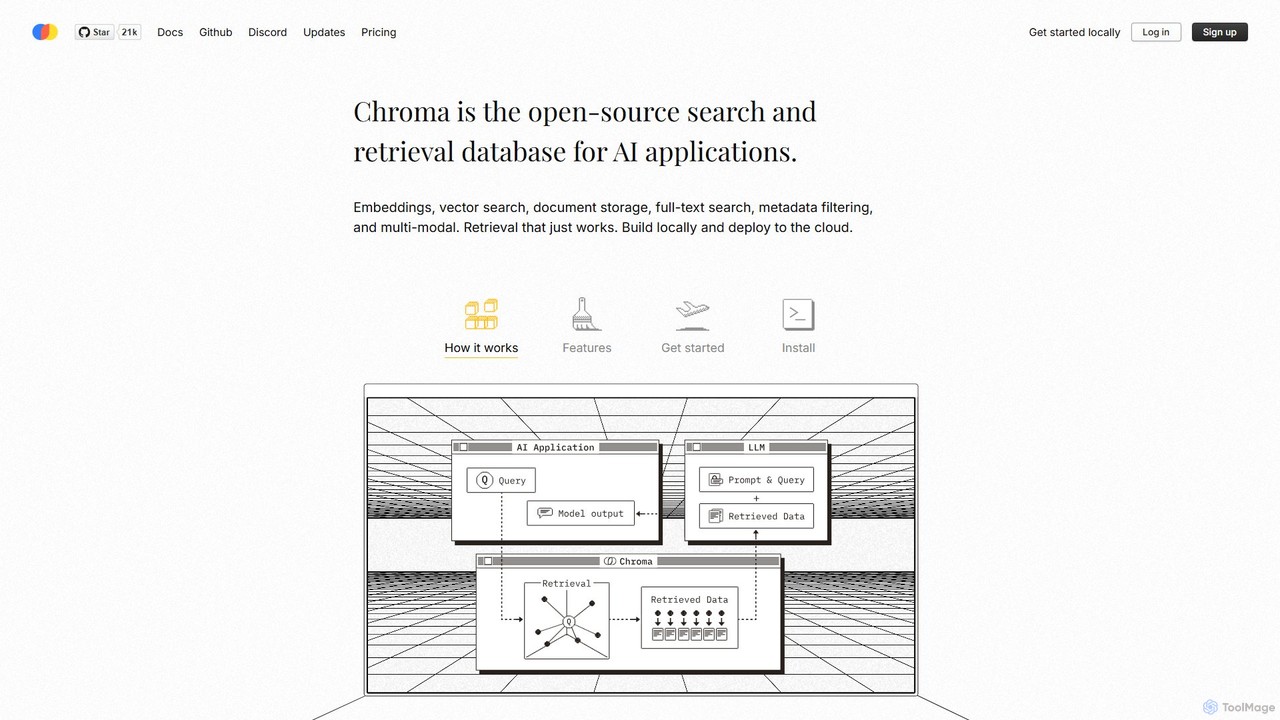
Chroma
Chroma is the open-source, AI-native retrieval database designed for building powerful AI applications with Retrieval-Augmented Generation (RAG). It simplifies storing and searching embeddings, documents, and metadata, offering vector search, full-text search, and a scalable, serverless cloud platform. It's built to be easy to use, cost-effective, and powerful, from local development to large-scale production.
Vector Database
Zilliz
Zilliz is an enterprise-grade vector database built for scalable AI applications. Powered by the popular open-source project Milvus, it provides a high-performance, cost-effective, and fully-managed service (Zilliz Cloud) for storing, indexing, and searching billions of vector embeddings. It's designed to power applications like RAG, recommendation systems, and multimodal search, with seamless integrations into major AI frameworks and cloud platforms.
Machine Learning
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
Weaviate
Weaviate is an open-source, AI-native vector database designed for developers. It enables scalable, low-latency vector, keyword, and hybrid search. Ideal for building AI applications like semantic search, recommendation engines, and Retrieval-Augmented Generation (RAG) systems, it integrates seamlessly with popular machine learning models to store and query data based on semantic meaning.
Vector Database
SurrealDB
SurrealDB is a next-generation, multi-model cloud database designed for modern applications. It simplifies backend development by unifying document, relational, graph, and time-series models with built-in full-text search, vector search, and in-database machine learning. Built for scalability and real-time data, it empowers developers to build complex, AI-powered applications with unprecedented ease and speed.
Vector Database
MyScale
MyScale is a high-performance vector database that uniquely combines vector search with the power of SQL. It's designed for building advanced AI applications like RAG, semantic search, and recommendation systems, simplifying the tech stack by allowing developers to run hybrid queries on vectors and structured data using a single, familiar interface.
Vector Database
Mixpeek
Mixpeek is a developer-first API and multimodal data warehouse for processing, searching, and analyzing unstructured data like video, audio, images, and documents. It simplifies the AI/ML pipeline with unified semantic search, automated classification, and seamless model management, allowing developers to build powerful multimodal applications.
Machine Learning
ragie
Ragie is a fully managed RAG-as-a-Service platform designed for developers. It simplifies the process of building and deploying AI applications by handling the entire Retrieval-Augmented Generation pipeline. Connect your data sources, and use a simple API to power accurate, context-aware chatbots, semantic search, and knowledge management systems without the complexity of managing infrastructure.
Machine Learning
Graphlit
Graphlit is a developer-focused Knowledge API platform for building AI applications and agents. It streamlines the ingestion, memory, and retrieval of unstructured data from any source, offering a powerful RAG-as-a-Service solution. With SDKs for major languages and tools for AI agent integration, it simplifies the creation of sophisticated AI systems.
Rag
Pinecone Comments (0)
Sign in to comment.
Sign inNo comments yet.