

InfluxData Overview
InfluxData is the creator of InfluxDB, the premier open-source time series database platform. It is purpose-built to handle the massive volumes and high velocity of time-stamped data generated by sensors, applications, and infrastructure. At its core, InfluxData provides the engine for real-world AI, enabling systems to detect, respond, and predict intelligently based on patterns in data over time. The latest version, InfluxDB 3.0, is re-architected in Rust and leverages the Apache ecosystem—including Arrow, DataFusion, and Parquet—to deliver unparalleled performance, unlimited cardinality, and significant cost savings through advanced compression. This platform is designed for developers, offering flexible deployment options from cloud to on-premise to the edge, ensuring that you can build powerful real-time systems wherever you need them.
How to use InfluxData
Getting started with InfluxData involves a straightforward process tailored for developers and data teams:
- Choose Your Deployment: Select the InfluxDB product that fits your needs. You can start for free with InfluxDB Cloud Serverless, opt for a managed InfluxDB Cloud Dedicated instance, or self-host with InfluxDB Enterprise or the open-source InfluxDB 3 Core.
- Ingest Data: Use Telegraf, InfluxData's open-source data collector with over 300 input plugins, to pull metrics from your systems, sensors, and applications. Alternatively, use the extensive client libraries for languages like Python, Go, JavaScript, and C# to stream data directly into InfluxDB.
- Query and Analyze: Leverage the power of SQL to query your time series data. InfluxDB's high-performance query engine, built on Apache DataFusion, allows for real-time analytics, enabling you to transform and analyze millions of data points per second.
- Integrate and Extend: Connect InfluxDB to your existing technology stack. Its open data format (Apache Parquet) and catalog integration (Apache Iceberg) allow for zero-copy data sharing with data lakes and warehouses. This enables you to train AI/ML models or run complex analytics in tools like Spark or Snowflake without moving or duplicating data.
- Automate and Monitor: Set up automated tasks for downsampling high-resolution data, creating alerts for anomalous behavior, and automatically evicting cold data to cheaper object storage to manage costs effectively.
Core Features of InfluxData
- High-Performance at Scale: Ingest millions of data points per second without performance degradation and query massive datasets with sub-second latency.
- Real-Time Analytics Engine: Perform complex analytical queries, aggregations, and transformations on streaming data as it arrives.
- Advanced Data Compression: Utilizes Apache Parquet columnar format and advanced compression algorithms to reduce storage costs by up to 90% compared to other databases.
- Unlimited Cardinality: The InfluxDB 3.0 engine is designed to handle high-cardinality data without the performance limitations of older time series solutions.
- Flexible Deployment: Run InfluxDB anywhere—in the cloud (multi-tenant or dedicated), on-premise in your data center, or at the network edge for localized processing.
- Open and Extensible: Built on open standards (SQL, Parquet, Arrow, Iceberg) and integrates seamlessly with over 300 tools via Telegraf, plus extensive client libraries for all major programming languages.
- Data Lifecycle Management: Automatically manages data tiers, moving recent, "hot" data from in-memory storage to cheaper, "cold" object storage over time.
Use Cases for InfluxData
InfluxData is the backbone for a wide range of real-time applications across various industries:
- Real-Time AI and Predictive Analytics: Provides high-resolution, context-rich time series data that AI and ML models need to infer cause and effect, enabling accurate forecasting and intelligent automation.
- Anomaly Detection: Monitor critical systems in real-time to instantly detect unusual patterns or deviations from the norm, triggering automated responses to prevent failures.
- Predictive Maintenance: Analyze sensor data from industrial equipment and machinery to predict potential failures, allowing for proactive maintenance that minimizes downtime and costs.
- IoT and Industrial IoT (IIoT): Collect, store, and analyze data from millions of connected devices, from smart home sensors to factory floor machinery, to gain operational insights.
- DevOps and Infrastructure Monitoring: Monitor the health and performance of servers, containers, applications, and networks with high-granularity metrics to ensure reliability and performance.
Advantages of InfluxData
Developers and enterprises choose InfluxData for several key advantages:
- Developer-Centric: Built by developers, for developers, with a focus on ease of use, powerful APIs, comprehensive documentation, and a vibrant community.
- Superior Performance: Outperforms other time series databases in both ingest and query speed, which is critical for real-time applications.
- Massive Cost Savings: The combination of extreme data compression and the ability to use low-cost object storage for historical data leads to a significantly lower total cost of ownership.
- Future-Proof Architecture: By embracing open data standards like Parquet and Iceberg, InfluxData avoids vendor lock-in and ensures interoperability with the broader data ecosystem, including data lakes and AI platforms.
- Unified Platform: Manages the entire data lifecycle within a single, cohesive platform, from high-speed ingestion and real-time querying to long-term storage and integration.
Pricing and Plans
InfluxData offers a flexible pricing structure to suit different needs and scales:
- InfluxDB Cloud Serverless: A fully managed, multi-tenant service with a perpetual free tier for getting started. Paid plans operate on a pay-as-you-go basis, charging for data ingested, queried, and stored, with a $250 credit for new upgrades.
- InfluxDB Cloud Dedicated: A fully managed, single-tenant service on dedicated infrastructure for larger workloads requiring enhanced security, performance, and unlimited scale. Pricing is custom and based on configuration.
- InfluxDB Enterprise: A self-managed, highly available, and scalable version for deployment on-premise or in a private cloud. It includes enterprise-grade features and support. Pricing is available upon request.
- InfluxDB 3 Core (OSS): The free, open-source time series engine for single-node deployments, perfect for smaller projects, testing, and edge computing.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 362.0K
- 2026-1: 377.0K
- 2026-2: 312.8K
- 2026-3: 367.5K
- 2026-4: 323.3K
- 2026-5: 310.4K
Geography
Top 5 countries / regions
- 🇺🇸United States30.2%
- 🇩🇪Germany23.2%
- 🇮🇳India18.6%
- 🇻🇳Vietnam17.7%
- 🇨🇳China10.2%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 80.6% |
Referral | 16.4% |
Email | 3.0% |
Top keywords
| Keyword | Cost per click |
|---|---|
| influx | $4.39 |
| influxdata | $5.81 |
| influx db | $0.88 |
| influxdb | $1.90 |
| telegraf | $0.15 |
InfluxData Videos on YouTube

InfluxData Alternatives
Milvus
Milvus is a high-performance, open-source vector database built for AI applications. It enables developers to manage and search through billions of high-dimensional vectors with minimal latency. Ideal for building scalable systems like retrieval-augmented generation (RAG), recommendation engines, and semantic search, Milvus offers flexible deployment options from local prototyping to large-scale distributed clusters.
Machine Learning
ChartDB
ChartDB is an AI-powered database schema visualizer that instantly generates interactive ER diagrams from a single query. It's designed for developers and teams to design, document, and collaborate on database structures. It features real-time collaboration, database synchronization, and an AI assistant to optimize schema design. Both cloud and self-hosted open-source versions are available.
Visualization
Vanna.AI
Vanna.AI is an open-source, personalized AI SQL agent that transforms natural language questions into accurate SQL queries. It uses a Retrieval-Augmented Generation (RAG) model trained on your specific database schema, documentation, and past queries to achieve high accuracy on complex datasets. It's designed for security, flexibility, and easy integration into any application, empowering both technical and non-technical users to gain insights from their data effortlessly.
Business Intelligence
Activeloop
Activeloop provides Deep Lake, a specialized Database for AI, designed to manage, query, and stream large-scale multimodal datasets (text, images, audio, video) for building advanced AI applications. It simplifies complex data infrastructure, enabling developers to create powerful Retrieval-Augmented Generation (RAG) systems, semantic search engines, and intelligent AI agents with ease.
Data Management
ParadeDB
ParadeDB is a modern Elasticsearch alternative built directly on Postgres. It enhances Postgres with powerful, real-time search and analytics capabilities, including full-text search, fuzzy matching, and faceting, eliminating the need for complex ETL processes and separate search engines.
SearchInfluxData Categories
InfluxData Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
Milvus
Milvus is a high-performance, open-source vector database built for AI applications. It enables developers to manage and search through billions of high-dimensional vectors with minimal latency. Ideal for building scalable systems like retrieval-augmented generation (RAG), recommendation engines, and semantic search, Milvus offers flexible deployment options from local prototyping to large-scale distributed clusters.
Machine LearningChartDB
ChartDB is an AI-powered database schema visualizer that instantly generates interactive ER diagrams from a single query. It's designed for developers and teams to design, document, and collaborate on database structures. It features real-time collaboration, database synchronization, and an AI assistant to optimize schema design. Both cloud and self-hosted open-source versions are available.
Visualization
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
AutomationVanna.AI
Vanna.AI is an open-source, personalized AI SQL agent that transforms natural language questions into accurate SQL queries. It uses a Retrieval-Augmented Generation (RAG) model trained on your specific database schema, documentation, and past queries to achieve high accuracy on complex datasets. It's designed for security, flexibility, and easy integration into any application, empowering both technical and non-technical users to gain insights from their data effortlessly.
Business IntelligenceParadeDB
ParadeDB is a modern Elasticsearch alternative built directly on Postgres. It enhances Postgres with powerful, real-time search and analytics capabilities, including full-text search, fuzzy matching, and faceting, eliminating the need for complex ETL processes and separate search engines.
Search
NeoBase
NeoBase is an open-source AI copilot for databases, enabling users to interact with their data using natural language. It connects to various SQL and NoSQL databases, translates plain English queries into optimized code, and visualizes the results. Designed for both technical and non-technical users, it streamlines data analysis, debugging, and reporting, eliminating the need for complex query writing and providing full data control through self-hosting.
Data Analysis
SQL Chat
SQL Chat is an open-source, chat-based SQL client and editor that uses AI to translate natural language questions into SQL queries. Connect to your database, ask questions in plain English, and get results instantly, democratizing data access for both technical and non-technical users.
Code Assistant
PostgresML
PostgresML is a powerful open-source extension that integrates machine learning and AI directly into your PostgreSQL database. It enables GPU-accelerated inference, vector search, and complete RAG pipelines using simple SQL commands, eliminating data movement and simplifying the MLOps stack for high-performance, scalable AI applications.
Mlops
ClickHouse
ClickHouse is a high-performance, open-source, column-oriented OLAP database management system. It's designed for real-time analytics on large-scale data, enabling blazing-fast queries for observability, business intelligence, ML/GenAI, and more, while remaining resource-efficient and cost-effective.
Databases
SingleStore
SingleStore is a high-performance, real-time data platform designed for enterprise AI and data-intensive applications. It unifies transactional (OLTP) and analytical (OLAP) workloads, including vector search, in a single, distributed SQL database, delivering millisecond latency at scale.
Vector Database
Metorial
Metorial is an integration platform for AI agents, enabling developers to quickly build, deploy, and monitor powerful agentic AI applications. It provides seamless connections to hundreds of tools, data sources, and APIs via its serverless Model Context Protocol (MCP) platform, offering robust SDKs, observability, and enterprise-grade security for scalable AI solutions.
Agentic Ai
MindsDB
MindsDB is an AI data automation platform that brings machine learning into your database. It allows developers and data analysts to create, train, and deploy AI models using standard SQL queries, connecting to over 200 data sources to provide real-time predictions and analytics without complex ETL pipelines.
Business Intelligence
Postgres Sandbox
An intuitive, web-based visual tool for designing, prototyping, and experimenting with PostgreSQL database schemas. Create tables, define relationships, and generate SQL code in a risk-free sandbox environment. Ideal for developers, DBAs, and students.
Database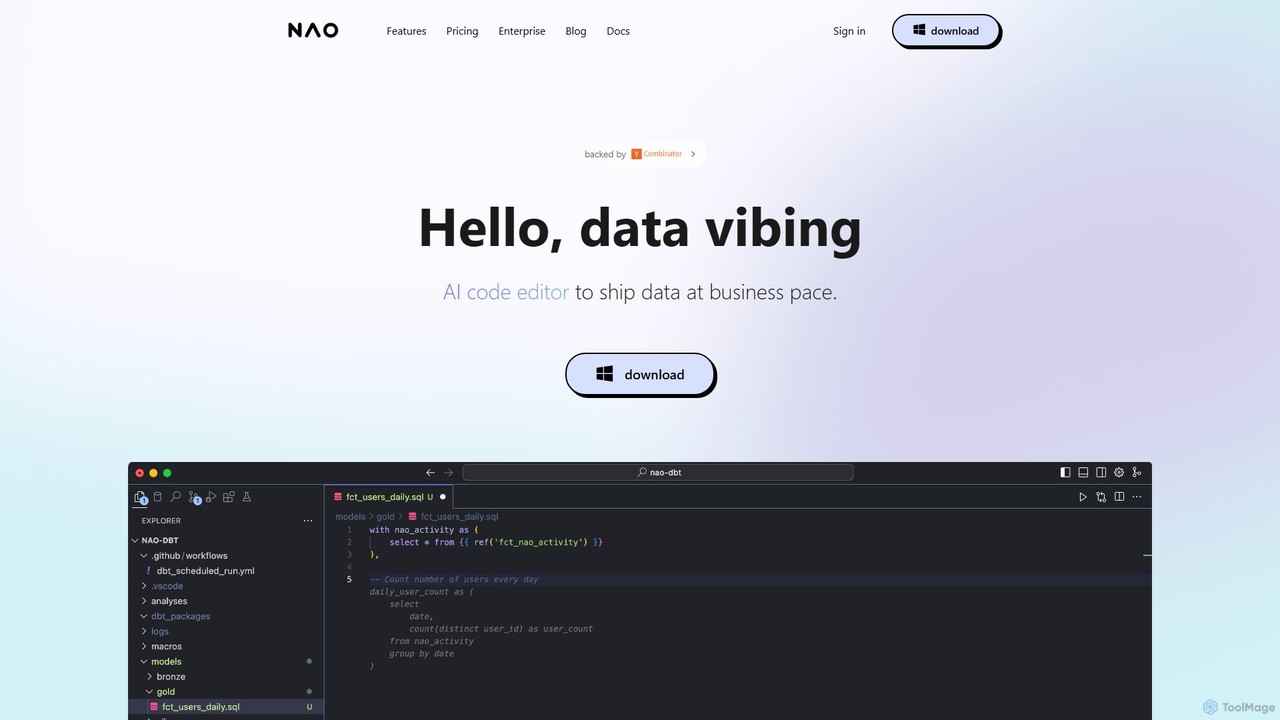
nao
nao is an AI-powered code editor designed for data teams. It streamlines SQL and Python data pipeline creation, dbt workflows, and analytics by natively connecting to your data warehouse. Its intelligent agent provides data-aware code suggestions, quality checks, and instant diff previews to help you ship data faster and more safely.
Analytics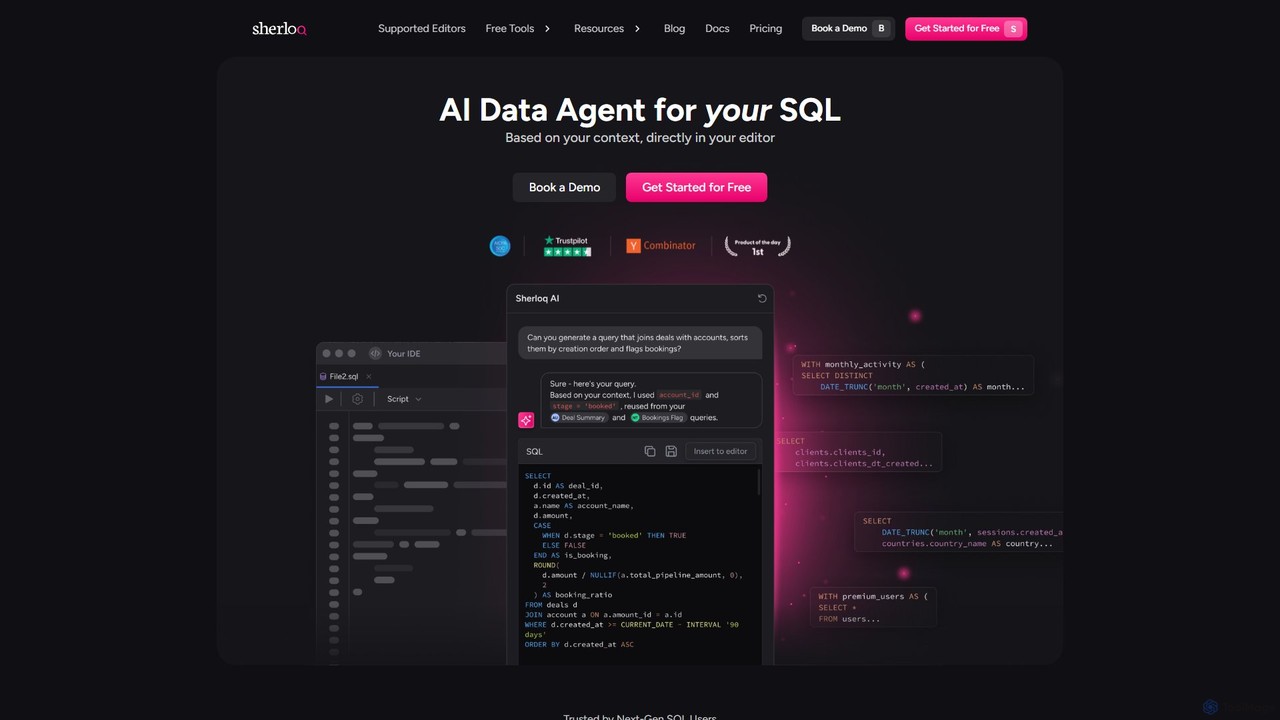
sherloqdata
Sherloqdata is an AI-powered data agent for SQL that works directly in your editor. It helps data professionals write, fix, and manage SQL queries faster by using your existing SQL repository for context. Features include an AI SQL Chat, query management, version control, and team collaboration.
Database
InfluxData Comments (0)
Sign in to comment.
Sign inNo comments yet.