
Unsloth Overview
Unsloth is a revolutionary open-source AI library engineered to solve two of the biggest challenges in Large Language Model (LLM) customization: training speed and memory consumption. Developed by a dedicated team, Unsloth redefines the efficiency of fine-tuning by employing manually derived mathematical optimizations and hand-written GPU kernels. This innovative approach allows developers, researchers, and enterprises to train models like Llama, Mistral, and Gemma up to 30 times faster than with standard methods like Flash Attention 2, and with a staggering 90% reduction in memory usage. This means tasks that once took a month can now be completed in just 24 hours, and powerful models can be fine-tuned on a single consumer-grade GPU.
The core magic of Unsloth lies in its deep optimization at the hardware level. Instead of relying on generic high-level libraries, Unsloth's creators have gone back to first principles, rewriting the most compute-heavy steps of the training process to maximize GPU efficiency. This results in not only faster training but also significantly faster inference speeds (up to 2x), allowing for quicker deployment of the fine-tuned models. Unsloth is designed for scalability, performing exceptionally on single GPUs, multi-GPU systems, and even multi-node clusters for enterprise-level tasks.
How to use Unsloth
Using Unsloth is designed to be straightforward for anyone familiar with the Python and Hugging Face ecosystem. The process typically involves these steps:
- Installation: Install the Unsloth library into your Python environment, usually with a simple pip command. The library is available as open-source freeware.
- Import and Model Loading: In your training script, import the `FastLanguageModel` from Unsloth. Instead of loading a model directly from Hugging Face's `transformers`, you use Unsloth's function to load the base model. This function automatically applies all the necessary performance patches and optimizations. You can specify the model name (e.g., 'unsloth/llama-3-8b-Instruct-bnb-4bit') and data type (e.g., 4-bit quantization) during this step.
- Adding LoRA Adapters: Unsloth simplifies the process of adding Low-Rank Adaptation (LoRA) adapters to the model. You can configure the LoRA parameters (like `r`, `lora_alpha`, `target_modules`) and apply them to the model with a single line of code.
- Data Preparation: Prepare your training dataset as you normally would for a Hugging Face fine-tuning task.
- Training: Use the Hugging Face `SFTTrainer` or a similar training class, passing in your Unsloth-optimized model, dataset, and training arguments. Unsloth seamlessly integrates with this workflow, automatically accelerating the backpropagation and optimization steps.
- Inference: Once training is complete, you can use the fine-tuned model for inference, which also benefits from Unsloth's speed enhancements.
Core Features of Unsloth
- Extreme Speed Boost: Up to 30x faster training and fine-tuning compared to standard implementations like Flash Attention 2.
- Massive Memory Reduction: Reduces VRAM usage by up to 90%, enabling fine-tuning of large models on consumer GPUs (like Tesla T4 or even GeForce RTX series).
- Hand-Written GPU Kernels: Core mathematical operations are manually optimized for maximum hardware performance, surpassing generic library capabilities.
- Broad Model Support: Natively supports a wide range of popular open-source LLMs, including Llama 1/2/3, Mistral, Gemma, Qwen, DeepSeek, and more.
- Quantization Support: Full support for 4-bit and 16-bit LoRA fine-tuning, making training even more memory-efficient.
- Scalability: Optimized for single GPU, multi-GPU (up to 8), and multi-node (Enterprise) configurations.
- Faster Inference: Delivers up to 2x faster inference speeds post-training, making model deployment more efficient.
- Accuracy Improvement: The Enterprise plan offers features that can boost model accuracy by up to 30% on certain tasks.
Use Cases for Unsloth
Unsloth is a versatile tool for anyone working with LLMs:
- AI Startups: Build and iterate on custom, specialized models for niche applications without incurring massive cloud computing costs.
- Academic Researchers: Accelerate research cycles and run more experiments on limited university hardware budgets.
- Enterprise MLOps Teams: Drastically reduce the cost and time of training internal models for tasks like customer support, document analysis, or code generation.
- Individual Developers & Hobbyists: Experiment with and learn about LLM fine-tuning on personal computers, lowering the barrier to entry for cutting-edge AI development.
- Data Scientists: Quickly fine-tune models on specific datasets to extract insights or build predictive tools for business intelligence.
Advantages of Unsloth
The primary advantage of Unsloth is its unparalleled efficiency. By tackling the core bottlenecks of speed and memory, it democratizes access to powerful AI customization. This leads to significant cost savings on GPU hardware and cloud services. Its open-source nature fosters transparency and community-driven improvement, while the seamless integration with the Hugging Face ecosystem ensures it's easy to adopt for anyone already in the field. Ultimately, Unsloth empowers users to achieve more with less, turning what was once a resource-intensive process into a fast and accessible one.
Pricing and Plans
Unsloth operates on a freemium model with three distinct tiers:
- Free: This is the open-source, freeware version of Unsloth. It provides a 2x speed boost, 60% VRAM reduction, and supports single GPU setups. It's perfect for individuals and small-scale projects, supporting 4-bit and 16-bit LoRA fine-tuning for models like Mistral, Gemma, and Llama.
- Unsloth Pro: Aimed at professionals and teams, this plan offers a 2.5x speed boost per GPU, 80% VRAM reduction, and enhanced multi-GPU support (up to 8 GPUs). This plan is suitable for any use case requiring more power and efficiency. Pricing is available upon contacting the Unsloth team.
- Unsloth Enterprise: The ultimate performance tier for large-scale operations. It unlocks up to 32x faster training, 90% VRAM reduction, multi-node support, and up to a 30% accuracy boost. It also includes support for full model training (not just LoRA), 5x faster inference, and dedicated customer support. Pricing is available upon contacting the Unsloth team.
Traffic
Latest traffic
Status
Monthly traffic trend
- 2025-9: 426.2K
- 2026-1: 574.8K
- 2026-2: 698.3K
- 2026-3: 1.3M
- 2026-4: 1.6M
- 2026-5: 1.1M
Geography
Top 5 countries / regions
- 🇨🇳China43.4%
- 🇺🇸United States30.2%
- 🇮🇳India11.4%
- 🇰🇷South Korea7.9%
- 🇩🇪Germany7.1%
Traffic sources
| Source type | Percentage |
|---|---|
Direct | 64.9% |
Referral | 34.0% |
Email | 1.1% |
Top keywords
| Keyword | Cost per click |
|---|---|
| kimi k2.6 | $0.00 |
| qwen3.5 | $0.00 |
| unsloth | $2.86 |
| unsloth ai | $3.35 |
| unsloth studio | $2.57 |
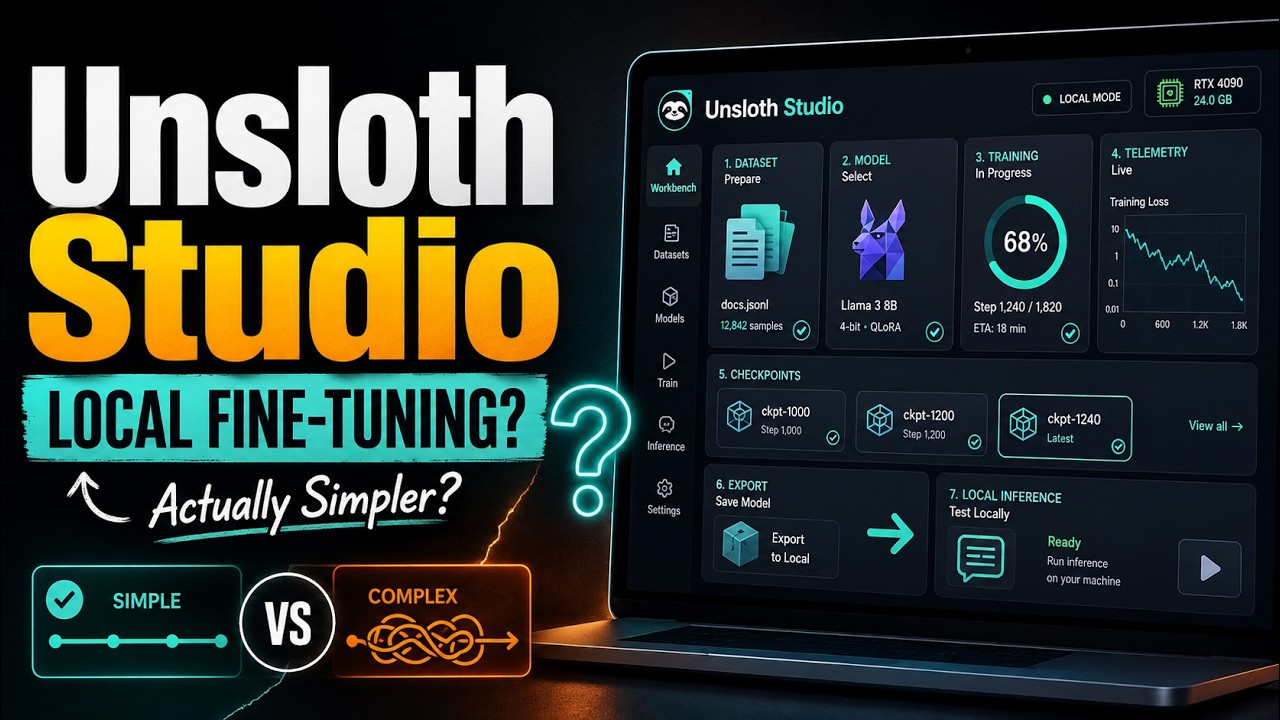
Unsloth Videos on YouTube

Byte Goose AI.



Docker

Unsloth Alternatives
xTuring
xTuring is an open-source Python library designed to simplify the process of building, fine-tuning, and controlling Large Language Models (LLMs). It provides a user-friendly interface for developers and researchers to personalize AI models for specific data and applications with high efficiency and customizability.
Model Training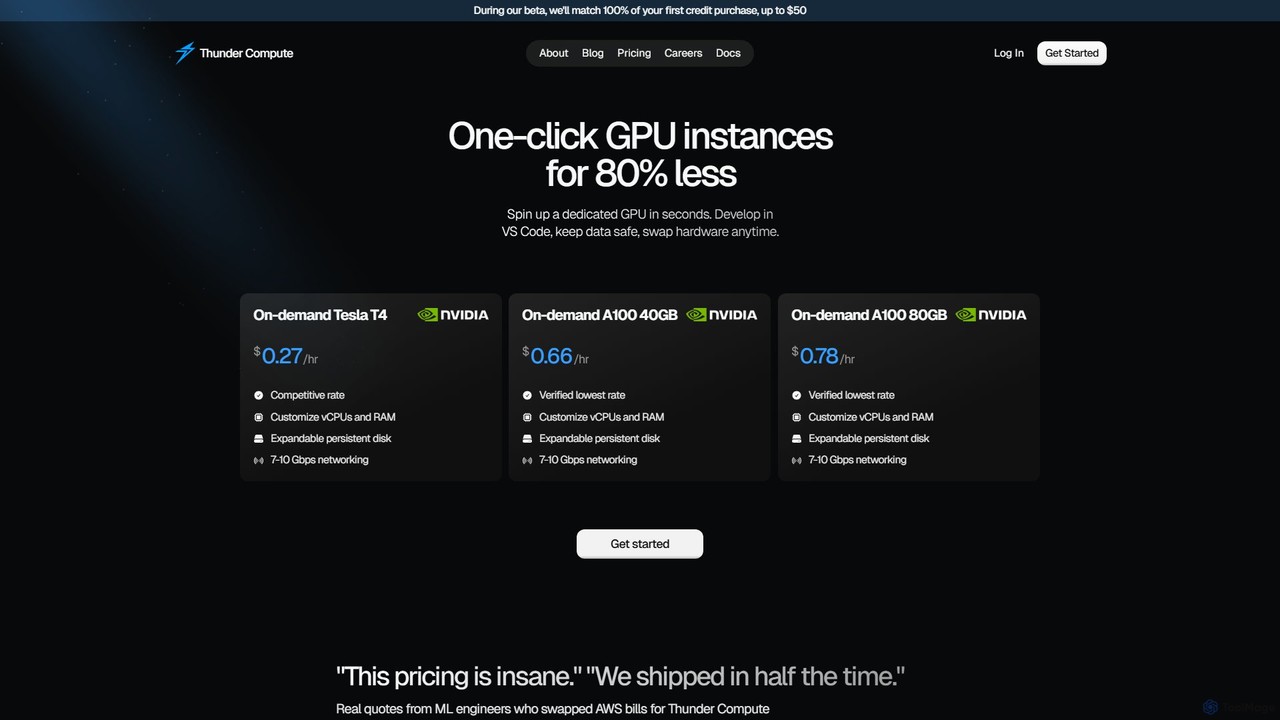
thundercompute
Thunder Compute offers an ultra-low-cost GPU cloud platform designed for AI and machine learning developers. It provides on-demand GPU instances like the NVIDIA A100 and T4 at prices up to 80% lower than major cloud providers. With features like one-click setup, VS Code integration, and seamless scalability, it dramatically simplifies the development workflow, from prototyping to production, allowing developers to focus on building models rather than managing infrastructure.
Machine Learning
Predibase
Predibase is an end-to-end developer platform for efficiently fine-tuning and serving open-source Large Language Models (LLMs). It enables users to build custom AI models that outperform large proprietary models like GPT-4 on specific tasks, while significantly reducing costs and inference latency. The platform features advanced techniques like Reinforcement Fine-Tuning (RFT) and LoRAX for high-speed, multi-model serving.
Machine Learning
Fluidstack
Fluidstack is a leading AI cloud platform providing high-performance, dedicated GPU clusters for training and serving frontier AI models. It offers rapid deployment of thousands of GPUs, fully managed services with 24/7 expert support, and transparent pricing with zero egress fees, empowering AI teams to scale without infrastructure friction.
Enterprise Solutions
Nebius
Nebius is a high-performance cloud platform specifically engineered for demanding AI and Machine Learning workloads. It provides scalable access to the latest NVIDIA GPUs, from single instances to massive clusters, complemented by a suite of managed services and an integrated AI Studio to streamline the entire ML lifecycle from training to inference.
Gpu CloudUnsloth Categories
Unsloth Embed Widget
Copy this embed code to place the badge on your blog, article, or product site and send readers directly to this ToolMage detail page.

Related AI tools
xTuring
xTuring is an open-source Python library designed to simplify the process of building, fine-tuning, and controlling Large Language Models (LLMs). It provides a user-friendly interface for developers and researchers to personalize AI models for specific data and applications with high efficiency and customizability.
Model Training
Ludwig
Ludwig is a low-code, open-source deep learning framework that simplifies building and training custom AI models. Using declarative YAML configurations, users can easily create complex models, including LLMs, for multi-modal and multi-task learning without extensive boilerplate code. It's designed for scalability, production-readiness, and integrates with popular tools like HuggingFace and MLFlow.
Model Training
FinetuneDB
FinetuneDB is an all-in-one AI fine-tuning platform for developers. It simplifies the entire workflow of creating custom Large Language Models (LLMs), from building high-quality datasets and fine-tuning models like Llama 3 and GPT-4o mini, to deployment and continuous evaluation on a single, secure platform.
Llmopsthundercompute
Thunder Compute offers an ultra-low-cost GPU cloud platform designed for AI and machine learning developers. It provides on-demand GPU instances like the NVIDIA A100 and T4 at prices up to 80% lower than major cloud providers. With features like one-click setup, VS Code integration, and seamless scalability, it dramatically simplifies the development workflow, from prototyping to production, allowing developers to focus on building models rather than managing infrastructure.
Machine LearningPredibase
Predibase is an end-to-end developer platform for efficiently fine-tuning and serving open-source Large Language Models (LLMs). It enables users to build custom AI models that outperform large proprietary models like GPT-4 on specific tasks, while significantly reducing costs and inference latency. The platform features advanced techniques like Reinforcement Fine-Tuning (RFT) and LoRAX for high-speed, multi-model serving.
Machine Learning
Ollama
Ollama is a powerful open-source framework for running large language models (LLMs) like Llama 3, Mistral, and Gemma locally on your own hardware. Available for macOS, Windows, and Linux, it simplifies the setup and management of open-source models, enabling private, offline, and cost-effective AI development and usage.
Machine Learning
GPT4All
GPT4All is a free, open-source, and privacy-focused AI chatbot that runs powerful language models locally on your desktop. It works offline, ensuring your data never leaves your device, and allows you to chat with your own documents securely.
Machine Learning
GreenNode
GreenNode is a one-stop AI cloud infrastructure provider, offering high-performance NVIDIA GPU solutions for startups and enterprises. It provides instant access to cutting-edge resources like H100 GPUs, scalable infrastructure, and expert AI Lab support. Focused on cost-effectiveness and performance, GreenNode helps accelerate model training, fine-tuning, and inference, with a strong presence in Southeast Asia.
Model Training
EntryPoint AI
EntryPoint AI is a no-code platform designed to simplify the fine-tuning of large language models (LLMs). It enables users to manage datasets, train, evaluate, and deploy custom AI models from providers like OpenAI without writing any code. The platform helps improve model quality, speed, and predictability for specific business tasks, making advanced AI customization accessible to teams of any size.
Data Management
Metrics Help
Metrics Help is an open-source web tool for machine learning practitioners. It functions as a comprehensive guide and an interactive analyzer for ML training metrics. Users can paste training logs to get instant explanations for key metrics like accuracy, loss, and perplexity, aiding in model performance analysis and debugging.
Model Training
hyperficient
hyperficient is an open-source AI tool for developers and ML engineers that automates the search for the most efficient fine-tuning strategies for neural networks. It significantly reduces computational costs, GPU time, and manual effort, enabling optimal model performance on limited resources.
Libraries
TensorFlow
TensorFlow is an end-to-end open-source platform for machine learning developed by Google. It provides a comprehensive, flexible ecosystem of tools, libraries, and community resources that lets researchers and developers build and deploy ML-powered applications. From beginners to experts, TensorFlow offers intuitive high-level APIs for easy model building and powerful low-level APIs for advanced research, enabling deployment across servers, edge devices, and browsers.
Frameworks
Label Studio
Label Studio is a versatile open-source data labeling platform designed for a wide range of data types. It enables users to annotate images, text, audio, video, and time-series data to fine-tune LLMs, prepare training data for machine learning, and validate AI models with human-in-the-loop feedback.
Training Data
Forefront
Forefront is a developer platform for building with open-source AI. It simplifies running, fine-tuning, and deploying large language models (LLMs) on your private data, providing a scalable, secure, and cost-effective alternative to closed-source platforms. Own your data, your models, and your AI.
Large Language Models
Jyek
Jyek is an AI agent platform that understands objectives, creates execution plans, uses tools, and delivers verifiable results for complex, multi-step tasks.
Automation
Unsloth Comments (0)
Sign in to comment.
Sign inNo comments yet.